<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="https://adam-gladstone.github.io/feed.xml" rel="self" type="application/atom+xml" /><link href="https://adam-gladstone.github.io/" rel="alternate" type="text/html" /><updated>2026-09-12T10:56:00+00:00</updated><id>https://adam-gladstone.github.io/feed.xml</id><title type="html">Adam’s Software Lab</title><subtitle>A collection of personal projects that reflect areas that I am interested in and technologies that I am learning about.</subtitle><author><name>Adam Gladstone</name></author><entry><title type="html">Connecting C++ to JavaScript using WASM</title><link href="https://adam-gladstone.github.io/software%20interoperability/web%20development/native%20c++%20code/Connecting-C++-to-JavaScript-using-WASM/" rel="alternate" type="text/html" title="Connecting C++ to JavaScript using WASM" /><published>2026-08-17T00:00:00+00:00</published><updated>2026-08-17T00:00:00+00:00</updated><id>https://adam-gladstone.github.io/software%20interoperability/web%20development/native%20c++%20code/Connecting-C++-to-JavaScript-using-WASM</id><content type="html" xml:base="https://adam-gladstone.github.io/software%20interoperability/web%20development/native%20c++%20code/Connecting-C++-to-JavaScript-using-WASM/"><![CDATA[<h3 id="introduction">Introduction</h3>
<p>Recently, I have been doing a lot of web development. I wanted to use a reasonably non-trivial C++ library of statistical functions in a web application that uses a basic client-side HTML/CSS/JavaScript stack. The intention here, as on previous occasions (<a href="https://github.com/Adam-Gladstone/SoftwareInteroperability">Software Interoperability</a>), was to see how feasible (and easy or otherwise) it is to build a component to connect a native C++ library to JavaScript. The more general use-case is to provide access to any native C++ functionality and make it available in a browser (hence cross-platform).</p>

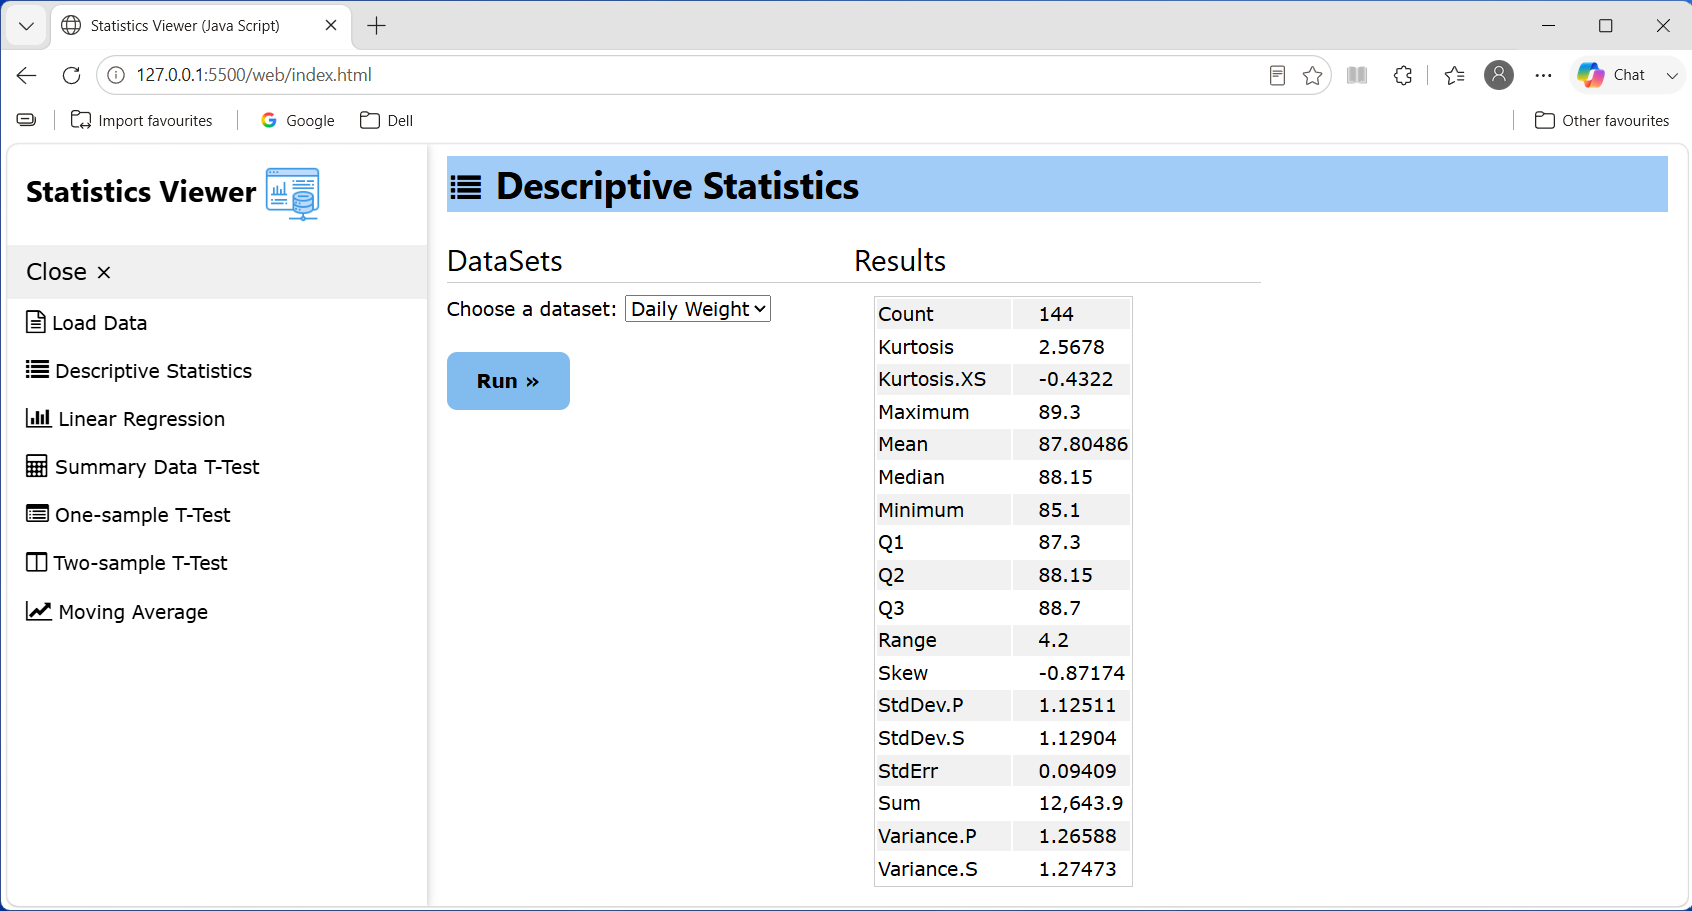
<p>This blog post describes the steps required to compile a native C++ library to <a href="https://webassembly.org/">WebAssembly(WASM)</a>, and to use this in a simple web application. The resulting application is shown below.</p>

<p><img src="https://adam-gladstone.github.io/assets/images/StatisticsViewer-DescriptiveStats.png" alt="StatsLibViewer" /></p>

<p>The full project is available <a href="https://github.com/Adam-Gladstone/SoftwareInteroperability/tree/master/StatsLibScript">here</a>.</p>

<h3 id="emscripten">Emscripten</h3>
<p>The main tool that we use is <a href="https://emscripten.org/docs/getting_started/FAQ.html#why-the-weird-name-for-the-project"><em>emscripten</em></a>. The documentation describes <em>emscripten</em> as a complete Open Source compiler toolchain to WebAssembly. More specifically <a href="https://emscripten.org/docs/introducing_emscripten/about_emscripten.html">using Emscripten you can</a>:</p>

<ul>
  <li><em>“Compile C and C++ code, or any other language that uses LLVM, into WebAssembly, and run it on the Web, Node.js, or other Wasm runtimes.”</em></li>
  <li><em>“Compile the C/C++ runtimes of other languages into WebAssembly, and then run code in those other languages in an indirect way (for example, this has been done for Python and Lua).”</em></li>
</ul>

<p>My own interest here is in compiling a C++ library for use in a basic web application. Specifically, the goal is to produce a WebAssembly module that contains (and exports) all of the functionality from the library that we want to consume from JavaScript. <em>emscripten</em> provides all the necessary <a href="https://emscripten.org/docs/index.html">tools</a> to manage this. It is also well-documented. Follow the Emscripten documentation for <a href="https://emscripten.org/docs/getting_started/downloads.html#installation-instructions">instructions on how to install the SDK</a>. The rest of this post will assume that you have activated the latest Emscripten SDK in your PATH via source <code class="language-plaintext highlighter-rouge">./emsdk_env.sh</code> (or <code class="language-plaintext highlighter-rouge">emsdk_env.bat</code> on Windows).</p>

<h3 id="the-c-library">The C++ Library</h3>
<p>The C++ library that I use is called <a href="https://github.com/Adam-Gladstone/SoftwareInteroperability/tree/master/Common">StatsLib</a>. The library is written in C++20 and uses <a href="https://www.boost.org/releases/1.91.0/">boost 1.91</a>. I have used this on previous occasions to demonstrate software interoperability with C++ from languages like C#, Python and R. The library consists of a number of classes and functions to perform basic statistical analyses. <code class="language-plaintext highlighter-rouge">DescriptiveStatistics</code> provides summary data for a given dataset. <code class="language-plaintext highlighter-rouge">LinearRegression</code> performs a univariate linear regression. And there are a number of classes derived from <code class="language-plaintext highlighter-rouge">StatisticalTest</code> that form a class hierarchy for handling statistical hypothesis tests. There are classes to perform a student’s t-test, a z-test and an F-test. There is also a class that performs a basic moving average as part of a time series analysis. Finally, the <code class="language-plaintext highlighter-rouge">DataManager</code> class provides a simple caching mechanism for datasets. It enables users to load datasets from files, then store and retrieve them by name on demand.</p>

<p>There were two main reasons for using this library. Firstly, I wanted an example that was not <a href="https://learn.microsoft.com/en-us/aspnet/core/blazor/webassembly-native-dependencies?view=aspnetcore-10.0">completely trivial</a> as this obscures and ignores important (possibly critical) issues. But also not too complex like the <a href="https://github.com/mono/skiasharp">SkiaSharpViews</a>. A good number of WebAssembly examples are based on a single C function (<code class="language-plaintext highlighter-rouge">add</code>, <code class="language-plaintext highlighter-rouge">fib</code> etc.) with simple <a href="https://learn.microsoft.com/en-us/dotnet/standard/native-interop/blittable-and-non-blittable-types">‘blittable types’</a>. However, I want to be able to use STL types (<code class="language-plaintext highlighter-rouge">std::vector</code>, <code class="language-plaintext highlighter-rouge">std::map</code>, <code class="language-plaintext highlighter-rouge">std::string</code>), and I also want to use classes, methods, and properties.</p>

<p>Secondly, most of the information about WebAssembly focuses specifically on the performance aspect rationale for using a C++ library in a web application hosted in a web browser. However, I think there is a more general use case applicable to any C++ code. One of the main attractions of WebAssembly is that it allows us to leverage the vast library of existing open-source C and C++ code in web applications.</p>

<h3 id="project">Project</h3>
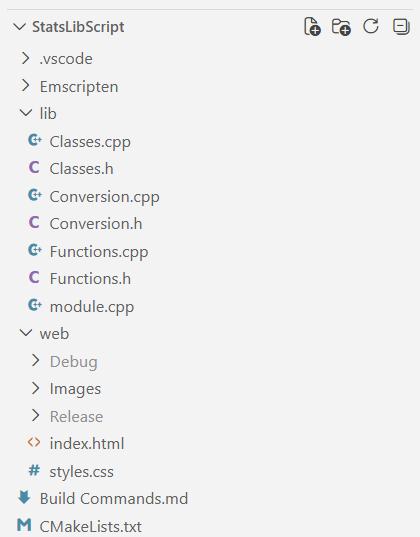
<p><em>StatsLibScript</em> consists of a single project.</p>

<p><img src="https://adam-gladstone.github.io/assets/images/StatsLibScript-Project.png" alt="project" />.</p>

<p>The <code class="language-plaintext highlighter-rouge">StatsLibScript</code> folder is divided into <code class="language-plaintext highlighter-rouge">\lib</code> and <code class="language-plaintext highlighter-rouge">\web</code> sub-folders. The <code class="language-plaintext highlighter-rouge">\lib</code> folder contains the sources and the <code class="language-plaintext highlighter-rouge">\web</code> folder contains the web application.</p>

<h4 id="the-statslibscript-component">The StatsLibScript Component</h4>
<p>The <code class="language-plaintext highlighter-rouge">\lib</code> folder contains the C++ code that is compiled into wasm. This consists broadly of the <a href="https://emscripten.org/docs/porting/connecting_cpp_and_javascript/embind.html">emscripten bindings</a> and auxilliary classes/functions that help with the communication between C++ and JavaScript.</p>

<p>The auxilliary classes/functions are:</p>
<ul>
  <li>
    <p>Conversion.h/Conversion.cpp</p>

    <p>This is where we locate any functions needed to convert between native C++ (and STL) types and types understood by JavaScript/Wasm. The only conversion of interest concerns the results returned from <em>StatsLib</em> functions. In general these are returned as a <code class="language-plaintext highlighter-rouge">std::unordered_map&lt;std::string, double&gt;</code>. However, even after registering this type (see below), wasm did not appear to ‘process’ it. As far as I could tell, there is no template defined for this <code class="language-plaintext highlighter-rouge">MapType</code> in <code class="language-plaintext highlighter-rouge">bind.h</code>. Therefore, I wrote a conversion to a <code class="language-plaintext highlighter-rouge">std::map&lt;std::string, double&gt;</code>. An earlier version of the component made use of <code class="language-plaintext highlighter-rouge">emscripten::val v</code> which allows converting JavaScript types to C++. However, these turned out not to be needed as the bindings specified in <code class="language-plaintext highlighter-rouge">module.cpp</code> (see below) worked directly.</p>
  </li>
  <li>
    <p>Functions.h/Functions.cpp</p>

    <p>This contains all the function wrappers which are called through the bindings.</p>
  </li>
  <li>
    <p>Classes.h/Classes.cpp</p>

    <p>This contains proxy classes for the <code class="language-plaintext highlighter-rouge">DataManager</code>, <code class="language-plaintext highlighter-rouge">TTest</code> and <code class="language-plaintext highlighter-rouge">ZTest</code> classes of <em>StatsLib</em>. These are not strictly necessary if the C++ types can be registered (or for classes where the specific functionality is not exposed). But with functionality like <code class="language-plaintext highlighter-rouge">DataManager::ListDataSets</code> we needed to convert from <code class="language-plaintext highlighter-rouge">std::vector&lt;DataSetInfo&gt;</code> to the registered ‘VectorString’ type i.e. <code class="language-plaintext highlighter-rouge">std::vector&lt;std::string&gt;</code>. Similarly, to handle the results coming back from <code class="language-plaintext highlighter-rouge">TTest</code> and <code class="language-plaintext highlighter-rouge">ZTest</code> classes we convert to the registered ‘MapStringDouble’ type i.e. <code class="language-plaintext highlighter-rouge">std::map&lt;std::string, double&gt;</code>.</p>
  </li>
  <li>
    <p>module.cpp</p>

    <p>This contains the main module with the emscripten bindings. The macro <code class="language-plaintext highlighter-rouge">EMSCRIPTEN_BINDINGS(my_module)</code> contains the definitions of the bindings. These are the functions that JavaScript will call and the classes that can be used.</p>
  </li>
</ul>

<p>In detail, first off, we <a href="https://emscripten.org/docs/porting/connecting_cpp_and_javascript/embind.html#built-in-type-conversions">register vector and map types</a>. This allows us to use these types conveniently from JavaScript, e.g.:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>let xs = new Module.VectorDouble();
xs.push_back(0.0);
xs.push_back(1.0);
...
</code></pre></div></div>

<p>This vector can be passed directly to C++ functions/classes. We can also iterate over the values and convert to a JavaScript array:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>let arr = new Array(xs.size()).fill(0).map((_, id) =&gt; xs.get(id));
console.log("DataSet: ", arr);
</code></pre></div></div>

<p>The module also defines the functions we want to overload. We use the <a href="https://emscripten.org/docs/porting/connecting_cpp_and_javascript/embind.html#overloaded-functions"><code class="language-plaintext highlighter-rouge">select_overload</code></a> method in embind to define two overloads for the <code class="language-plaintext highlighter-rouge">DescriptiveStatistics</code> function, with or without a list of keys that identify the results we want to retrieve:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>let keys = new Module.VectorString()
keys.push_back("Mean");
keys.push_back("StdDev.S");

const results = Module.DescriptiveStatistics(xs, keys)

console.log("Mean: ", results.get(keys.get(0)));
console.log("StdDev.S: ", results.get(keys.get(1)));
</code></pre></div></div>

<p>We also declare an enumerated type mapped to the underlying C++ type:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>enum_&lt;StatisticsLibrary::DescriptiveStatistics::VarianceType&gt;("VarianceType")
    .value("Sample", StatisticsLibrary::DescriptiveStatistics::VarianceType::Sample)
    .value("Population", StatisticsLibrary::DescriptiveStatistics::VarianceType::Population);
</code></pre></div></div>

<p>This can then be used in JavaScript:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>console.log("Standard Deviation (Population): ", Module.StandardDeviation(xs, Module.VarianceType.Population));
console.log("Standard Deviation (Sample): ", Module.StandardDeviation(xs, Module.VarianceType.Sample));
</code></pre></div></div>

<p>Finally, we define the wrapper classes in terms of constructors and functions. The <code class="language-plaintext highlighter-rouge">DataManager</code> class takes a simple constructor, followed by a number of functions. The <code class="language-plaintext highlighter-rouge">TTest/ZTest</code> wrappers both have multiple constructors. It is worth pointing out that the overload resolution is done using the number of arguments, not the types. This causes a slight issue in the case of the T-Test. The arguments for the second and third constructor are either a <code class="language-plaintext highlighter-rouge">double</code> and a <code class="language-plaintext highlighter-rouge">std::vector&lt;double&gt;</code> or two <code class="language-plaintext highlighter-rouge">std::vector&lt;double&gt;</code>’s. Since they have the same number of arguments, embind doesn’t distinguish between the two.</p>

<p>For example,</p>
<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>.constructor&lt;double, double, double, double&gt;()                          // 4 args - OK
.constructor&lt;double, const std::vector&lt;double&gt;&amp;&gt;()                      // 2 args - double and vector
.constructor&lt;const std::vector&lt;double&gt;&amp;, const std::vector&lt;double&gt;&amp;&gt;()  // 2 args - vector and vector
</code></pre></div></div>

<p>When calling this from JavaScript, it does not distinguish the case of 2 args. To work around this we added a dummy initial third argument, which is not ideal.</p>

<p>Depending on the exact requirements of the C++ library that is being exposed, there is a lot more that can be done. This is covered in the <a href="https://emscripten.org/docs/porting/connecting_cpp_and_javascript/embind.html"><em>emscripten documentation</em></a>. This project only just scratches the surface.</p>

<h4 id="compiling--building">Compiling &amp; Building</h4>
<p>Compiling and building consists of a single command line:</p>
<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>emcc --bind module.cpp Conversion.cpp Functions.cpp Classes.cpp 
	&lt;path&gt;/SoftwareInteroperability/Common/source/DataManager.cpp 
	&lt;path&gt;/SoftwareInteroperability/Common/source/DescriptiveStatistics.cpp 
	&lt;path&gt;/SoftwareInteroperability/Common/source/StatisticalTests.cpp 
	&lt;path&gt;/SoftwareInteroperability/Common/source/StatisticsLibrary.cpp 
	&lt;path&gt;/SoftwareInteroperability/Common/source/TimeSeries.cpp 
	-O0 
	-o StatsLibScript.js 
	-sENVIRONMENT="web" 
	-I D:/Libraries/boost_1_91_0/ 
	-I &lt;path&gt;/SoftwareInteroperability/Common/include/ 
	-std=c++20 
	-sNO_DISABLE_EXCEPTION_CATCHING 
	--no-entry
</code></pre></div></div>

<p>We have referenced the sources directly, just for convenience. We could equally have built (<strong>an LLVM compatible</strong>) library file and included it. Use this link for additional information regarding <a href="https://emscripten.org/docs/compiling/Building-Projects.html#building-projects">building projects</a>. There are a number of useful <a href="https://emscripten.org/docs/tools_reference/settings_reference.html#emscripten-compiler-settings">compiler flags</a>. We have only used a small subset here. The break down is as follows:</p>

<ul>
  <li>-O0	optimisation level for Debug</li>
  <li>-o	output a java script ‘bootstrap’ file</li>
  <li>-sENVIRONMENT=”web”</li>
  <li>-I …include boost library and the common includes for StatsLib</li>
  <li>-std=c++20 specifies the C++ language standard</li>
  <li>-sNO_DISABLE_EXCEPTION_CATCHING flag to indicate that we want to enable exception handling. This allows us to decorate the JavaScript functions with <code class="language-plaintext highlighter-rouge">try { ... } catch(e) {}</code> blocks and process the native C++ exception.</li>
  <li><a href="https://emscripten.org/docs/compiling/Building-Projects.html#troubleshooting">–no-entry</a></li>
</ul>

<p>After the build, we copy the artifacts to the Debug or Release directory.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>copy "StatsLibScript.js" "../web/Debug/StatsLibScript.js"
copy "StatsLibScript.wasm" "../web/Debug/StatsLibScript.wasm"
</code></pre></div></div>

<p>For convenience, I have set this up so that it can be built from a single command line and run (using live server) from Visual Studio Code. This seemed to me the easiest approach for development. However, there is also a CMake project and a Visual Studio 2022 solution if you prefer. Further details relating to the build can be found in: <a href="https://github.com/Adam-Gladstone/SoftwareInteroperability/blob/master/StatsLibScript/Build%20Commands.md">Build Commands.md</a>.</p>

<h4 id="the-statistics-viewer-web-application">The ‘Statistics Viewer’ web application</h4>
<p>The <code class="language-plaintext highlighter-rouge">\web</code> folder contains the web infrastructure and the debug and release build outputs. There is a single <code class="language-plaintext highlighter-rouge">index.html</code> file and a stylesheet (<code class="language-plaintext highlighter-rouge">styles.css</code>). <code class="language-plaintext highlighter-rouge">index.html</code> contains the main code to load the <code class="language-plaintext highlighter-rouge">StatsLibScript.js</code> module.</p>

<p>To use the WebAssembly module, we reference the compiled <code class="language-plaintext highlighter-rouge">StatsLibScript.js</code> in the <code class="language-plaintext highlighter-rouge">script</code> element:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>&lt;script src="Debug/StatsLibScript.js"&gt;&lt;/script&gt;
</code></pre></div></div>

<p>We also need a script tag to initialise the module.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>	Module.onRuntimeInitialized = _ =&gt; {

		const v = Module.getVersion();
		console.log("Version =", v);

		console.log("Initializing DataManager...");

		dataManager = new Module.DataManager();

		console.log("Number of DataSets: ", dataManager.CountDataSets());
	};

</code></pre></div></div>
<p>An alternative is to <code class="language-plaintext highlighter-rouge">fetch</code> the wasm code directly.</p>

<p>The rest of the html code deals with calling the functions and processing results.</p>

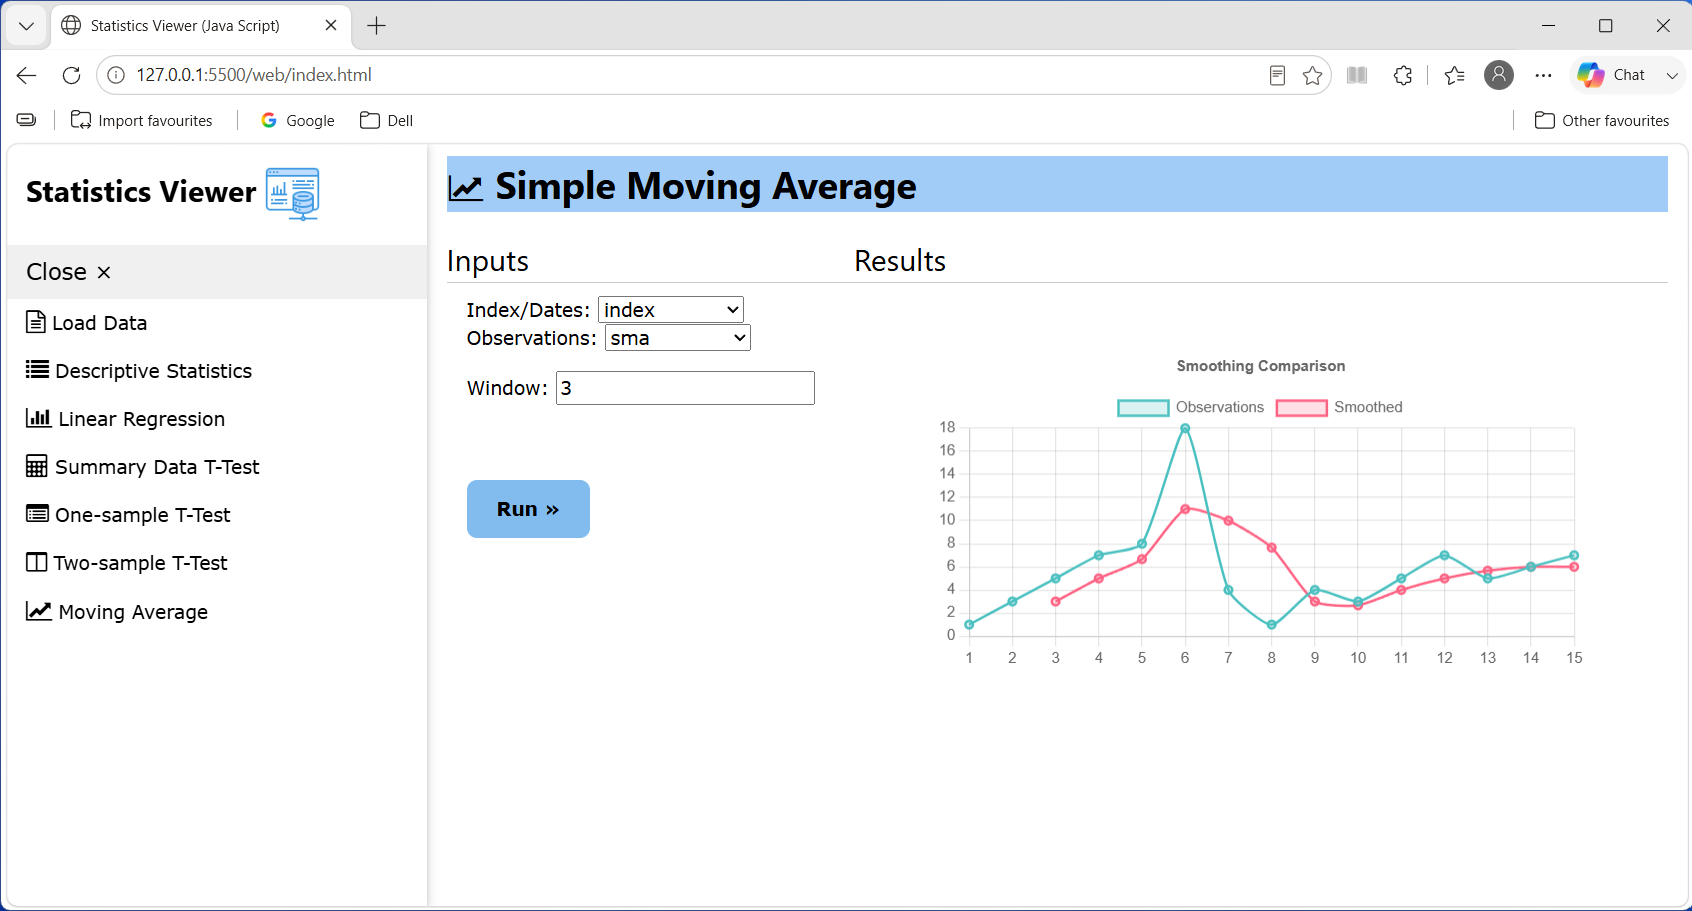
<p>The web application allows the user to load datasets and then perform statistical analyses, for example request descriptive statistics or carry out a linear regression. In terms of the UI, the web application consists of a left-hand side collapsible menu. The main page content consists of sections referenced by the navigation menu. Each section consists of a left-hand panel that contains inputs (typically dataset(s) and/or single values) and a <code class="language-plaintext highlighter-rouge">Run&gt;&gt;</code> button. The right-hand panel is used to display the outputs (typically a table, but for the Moving Average we use a graph).</p>

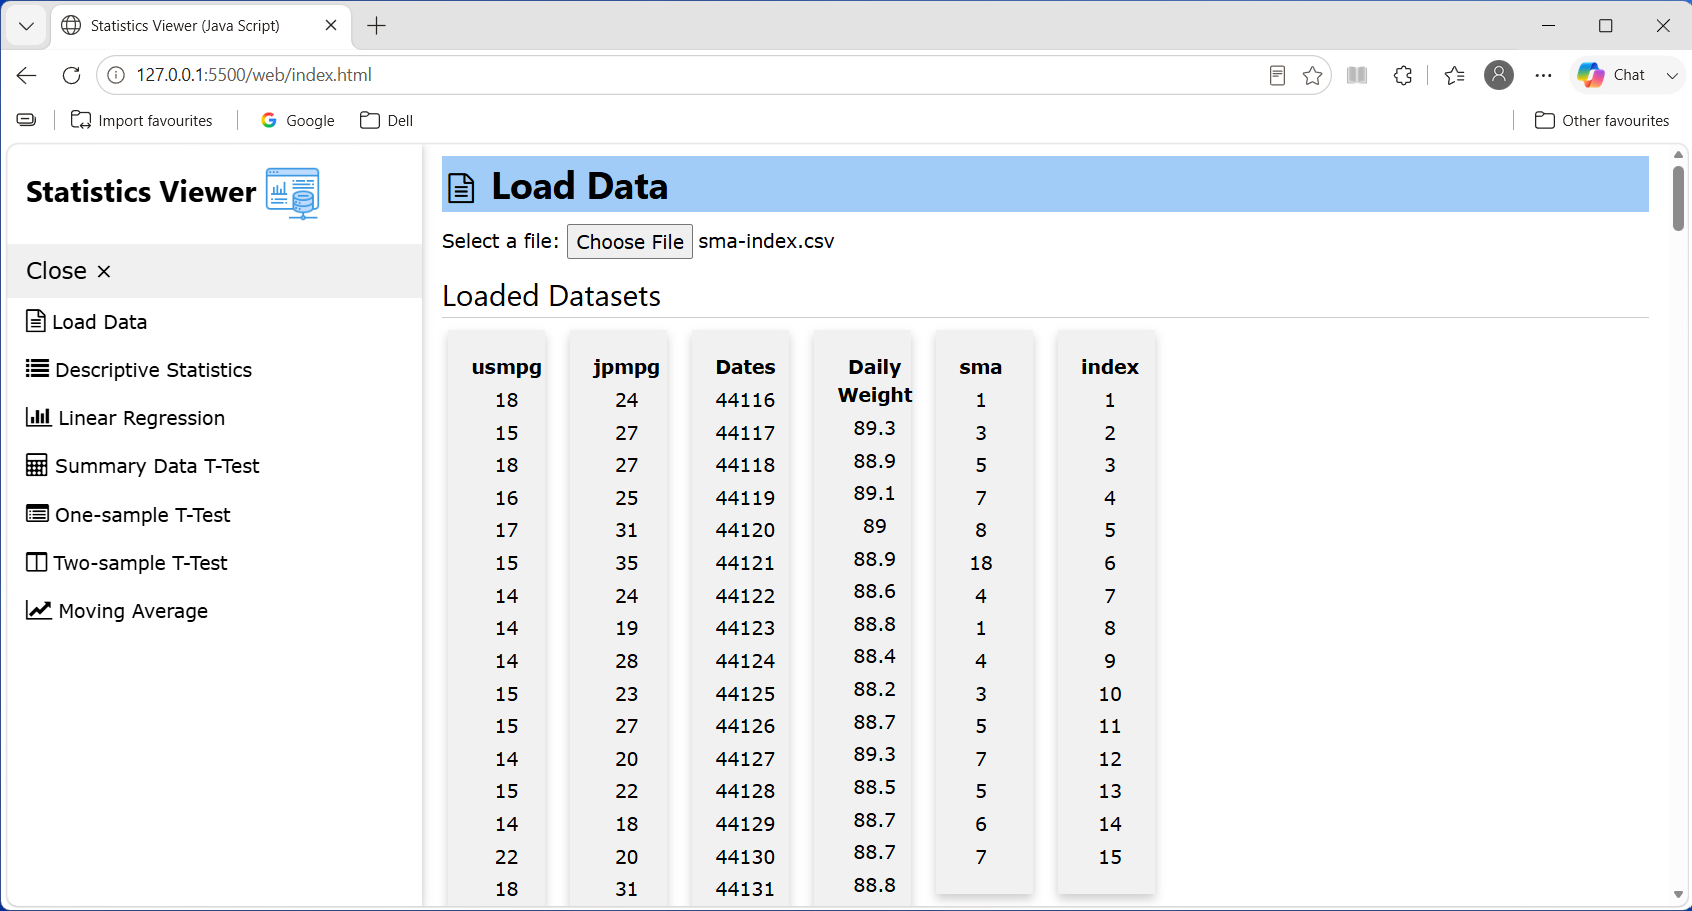
<p>To use the application, run a local server and load the <code class="language-plaintext highlighter-rouge">index.html</code> page. Then load some data sets into the DataManager. A dataset is a single .csv file with a column of data and a heading. The heading is used as a dataset name. There are a number of examples in the <a href="https://github.com/Adam-Gladstone/SoftwareInteroperability/tree/master/Data"><code class="language-plaintext highlighter-rouge">SoftwareInteroperability\Data</code> directory</a>.</p>

<p><img src="https://adam-gladstone.github.io/assets/images/StatisticsViewer-LoadData.png" alt="Load Data Set" /></p>

<p>Here we see a screenshot after four datasets have been loaded.</p>

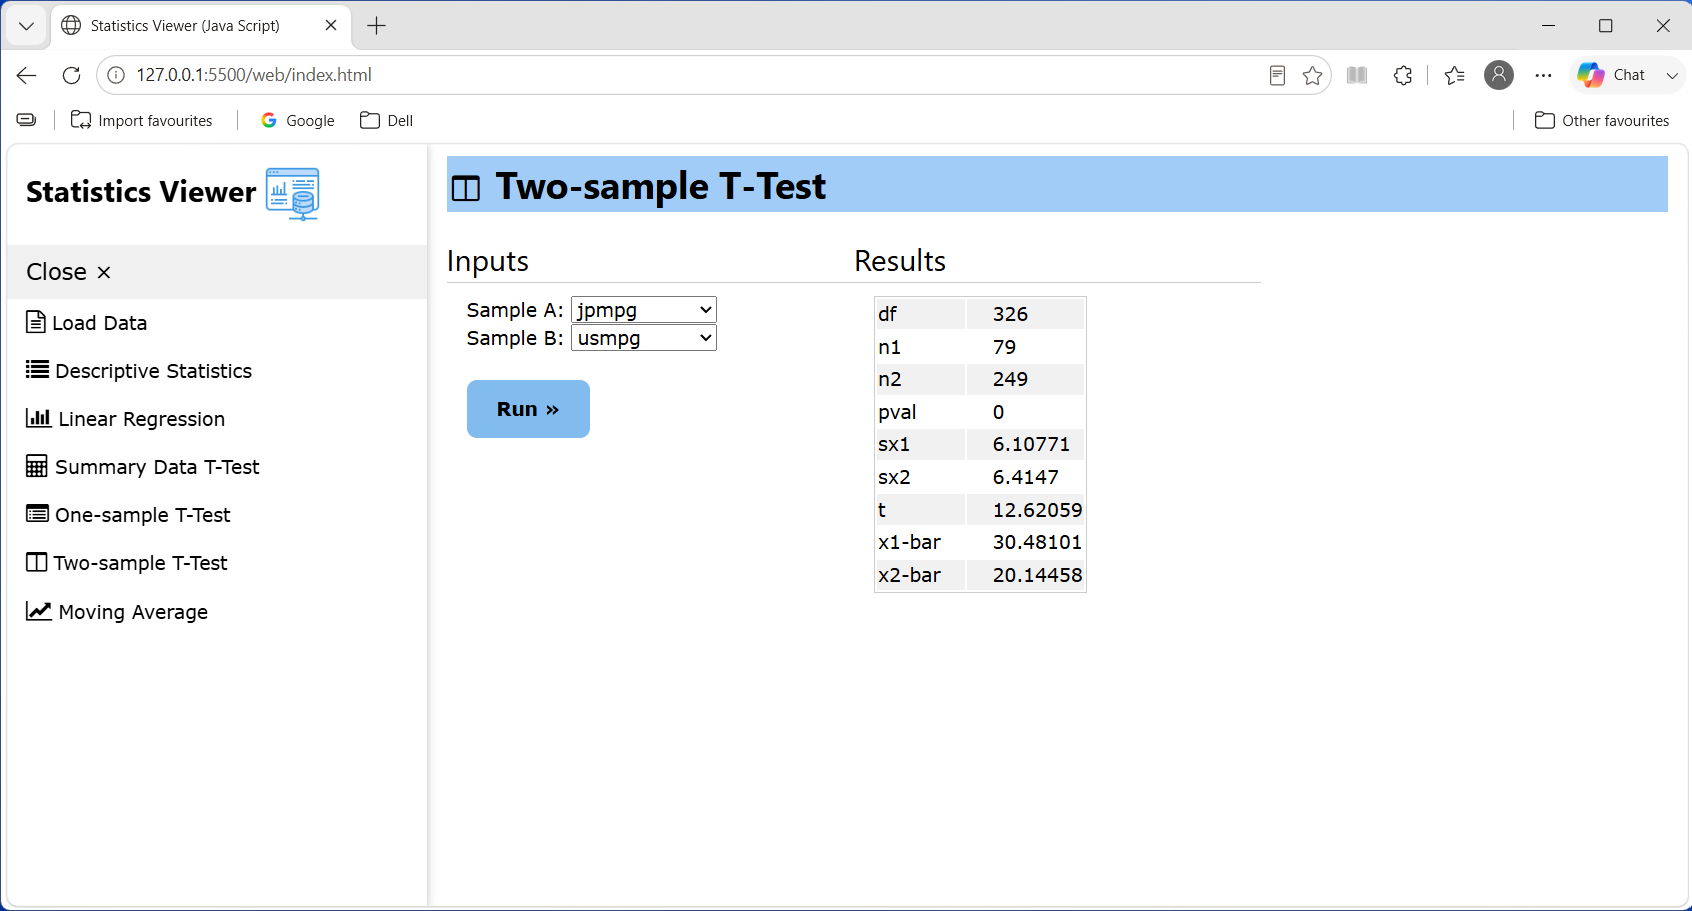
<p>Then, depending on the dataset, we can choose <em>Descriptive Statistics</em>, <em>Linear Regression</em>, <em>TTests</em>, or <em>Moving Average</em>. Select the appropriate dataset(s) and press ‘Run’. The results are shown in a table on the right-hand side.</p>

<p><img src="https://adam-gladstone.github.io/assets/images/StatisticsViewer-DescriptiveStats.png" alt="Descriptive Statistics" /></p>

<p><img src="https://adam-gladstone.github.io/assets/images/StatisticsViewer-TwoSampleTTest.png" alt="T-tests (summary, one- and two-sample)" /></p>

<p><img src="https://adam-gladstone.github.io/assets/images/StatisticsViewer-MovingAverage.png" alt="Moving Average" /></p>

<h4 id="debugging">Debugging</h4>

<p>Debugging makes use of the developer tools available in the web browser.</p>

<h3 id="conclusion">Conclusion</h3>
<p>In this blog post we have seen how to take a native C++ library and compile it to WebAssembly using emscripten. We have seen how to use embind to define the types, classes and functions that we want to expose to JavaScript. And we have built this into a simple ‘Statistics Viewer’ web application.</p>

<h3 id="see-also">See also</h3>
<ul>
  <li><a href="https://emscripten.org/docs/getting_started/index.html">Emscripten</a>.</li>
  <li><a href="https://github.com/WebAssembly/wabt">WebAssembly binary toolkit (wabt)</a>: a suite of tools for inspecting and manipulating WebAssembly files.</li>
</ul>]]></content><author><name>Adam Gladstone</name></author><category term="Software Interoperability" /><category term="Web development" /><category term="Native C++ code" /><category term="cpp" /><category term="c++" /><category term="emscripten" /><category term="WebAssembly" /><category term="WASM" /><category term="javascript" /><category term="js" /><category term="html" /><category term="css" /><summary type="html"><![CDATA[I have a small library of native C++ functions that perform statistical analyses. I wanted to be able to use these functions and display the results in a basic web application using standard HTML, CSS and some JavaScript. This post describes how to do this using WASM (WebAssembly).]]></summary></entry><entry><title type="html">Part V - Using R in Excel - Inferential Statistics</title><link href="https://adam-gladstone.github.io/r-project/Part-V-Using-R-in-Excel-Inferential-Statistics/" rel="alternate" type="text/html" title="Part V - Using R in Excel - Inferential Statistics" /><published>2025-10-14T00:00:00+00:00</published><updated>2025-10-14T00:00:00+00:00</updated><id>https://adam-gladstone.github.io/r-project/Part%20V%20-%20Using%20R%20in%20Excel%20-%20Inferential%20Statistics</id><content type="html" xml:base="https://adam-gladstone.github.io/r-project/Part-V-Using-R-in-Excel-Inferential-Statistics/"><![CDATA[<h3 id="introduction">Introduction</h3>
<p>In the previous posts in this series (<strong>Using R in Excel</strong>) I have demonstrated some basic use-cases where using R in Excel is useful. Specifically we have looked at <a href="https://adam-gladstone.github.io/r-project/Part-I-Using-R-in-Excel-Descriptive-Statistics/">descriptive statistics</a>, <a href="https://adam-gladstone.github.io/r-project/Part-II-Using-R-in-Excel-Linear-Regression/">linear regression</a>, <a href="https://adam-gladstone.github.io/r-project/Part-III-Using-R-in-Excel-Forecasting/">forecasting</a>, and <a href="https://adam-gladstone.github.io/r-project/Part-IV-Using-R-in-Excel-Calling-Python/">calling Python</a>. In this post, I am going to look at inferential statistics and how R can be used (in Excel) to perform some typical statistical tests. Excel provides many excellent facilities for data wrangling and analysis. However, for certain types of statistical data analysis the limitations of the built-in functions and the Analysis ToolPak is not sufficient, and R provides superior facilities.</p>

<p>The workbook for this part of the series is: <a href="https://adam-gladstone.github.io/assets/images/Part-V-R-in-Excel-Inferential-Statistics.xlsx">“Part V - R in Excel - Inferential Statistics.xlsx”</a>. As before, the ‘References’ worksheet lists links to external references. The ‘Libraries’ worksheet loads additional (non-default) packages. In this demonstration, I use <a href="https://rpkgs.datanovia.com/ggpubr/"><code class="language-plaintext highlighter-rouge">ggpubr</code></a> and the <a href="https://www.rdocumentation.org/packages/lsr/versions/0.5.2"><code class="language-plaintext highlighter-rouge">lsr</code></a> package. The <code class="language-plaintext highlighter-rouge">ggpubr</code> package provides some easy-to-use functions for creating and customizing ‘ggplot2’-based publication ready plots. The <code class="language-plaintext highlighter-rouge">lsr</code> package provides some useful wrappers for common hypothesis tests and basic data manipulation. These packages should be present and loaded before continuing with the analyses.</p>

<p>The ‘Datasets’ worksheet contains the data referenced in the worksheets. The data for the main analyses represents the weights (in Kg’s) of 9 women and 9 men. The data has been loaded and an Excel table created named <code class="language-plaintext highlighter-rouge">tWeightData</code>.</p>

<h3 id="analysis-i">Analysis I</h3>
<h4 id="creating-the-data-frame">Creating the data frame</h4>
<p>The first thing to do is to create an R data frame. However, rather than having a table with two columns (women_weight and men_weight) we want a ‘Group’ column and a ‘Weight’ column. To do this we first create vectors using:</p>

<p><code class="language-plaintext highlighter-rouge">=RScript.CreateVector('women_weight',Datasets!N2:N10)</code></p>

<p>and</p>

<p><code class="language-plaintext highlighter-rouge">=RScript.CreateVector('men_weight',Datasets!O2:O10)</code></p>

<p>After this, we create the data frame specifying the grouping factors and the data. The corresponding vectors and the <code class="language-plaintext highlighter-rouge">weight_data</code> data frame should appear in the Excel R AddIn panel.</p>

<h4 id="comparing-means">Comparing Means</h4>
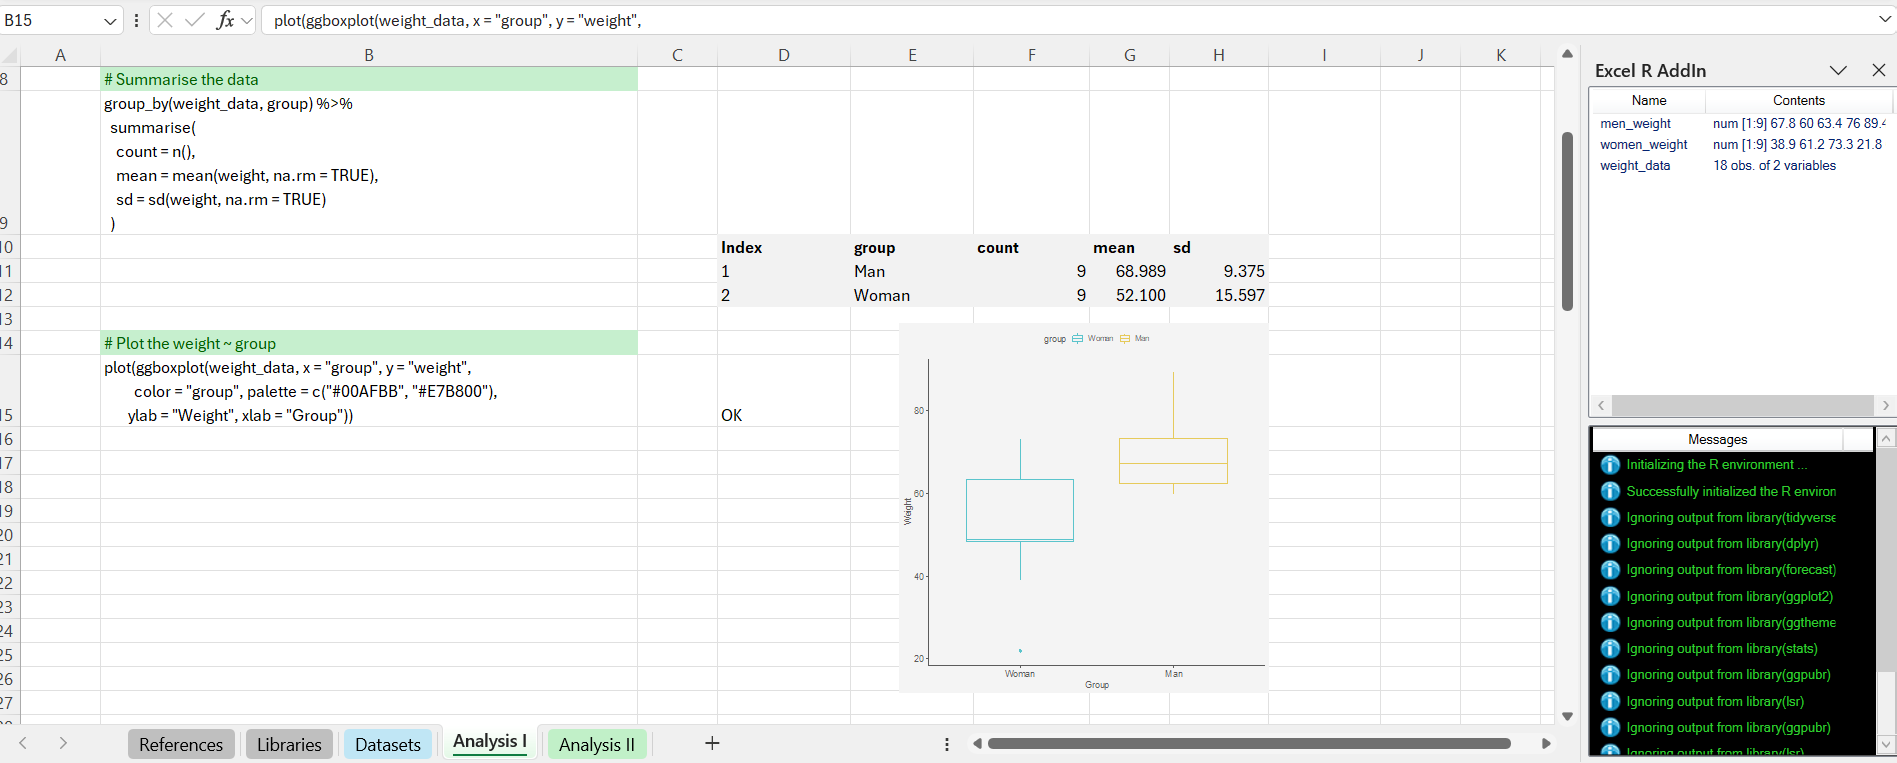
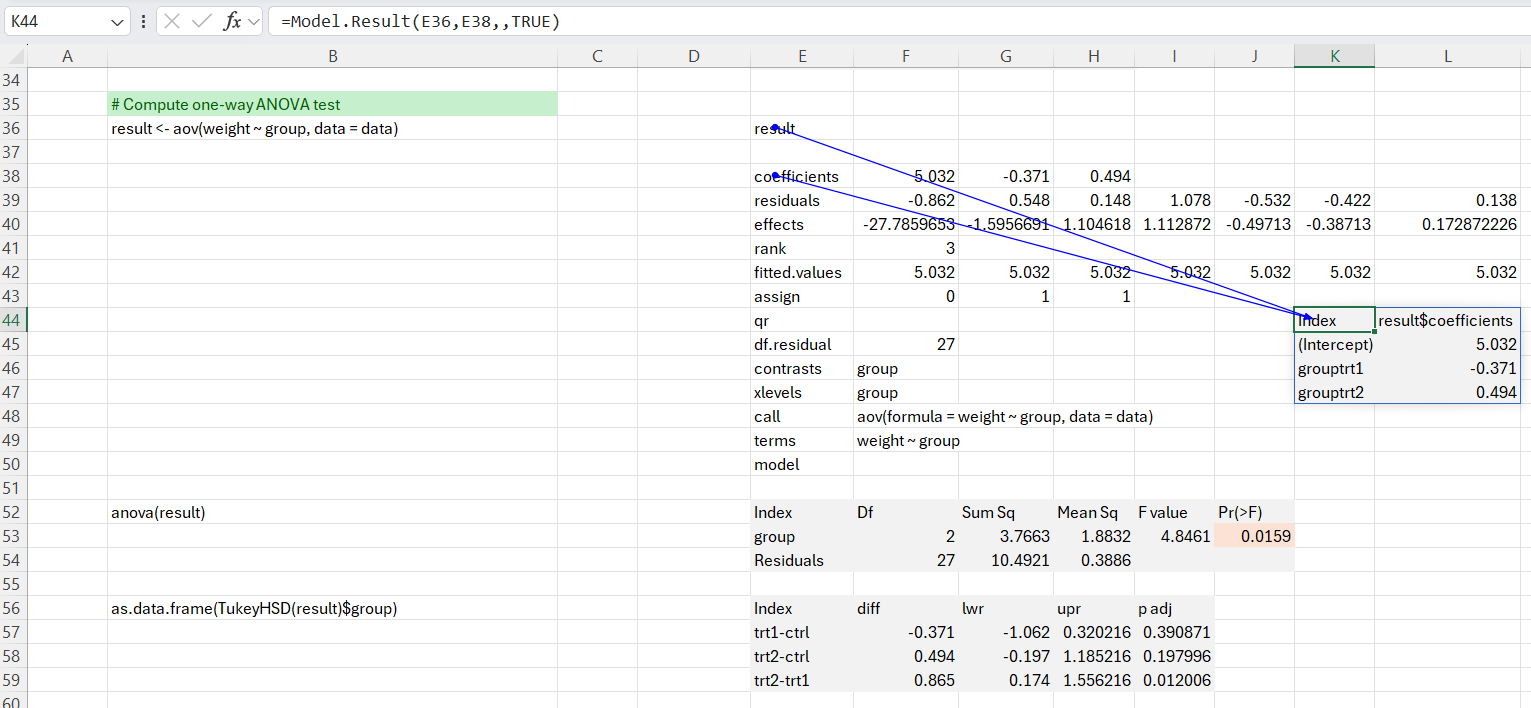
<p>The first analysis checks whether there’s a significant difference in the weights of the different groups. For this, we perform an independent samples t-test. Prior to performing the test, it is useful to provide a summary of the data, so we group the data to obtain the means and standard deviations, and we also produce a boxplot.</p>

<p><img src="https://adam-gladstone.github.io/assets/images/WeightSummaryAndPlot.png" alt="Summary Data and Plot" /></p>

<p>From the plot, there seems to be a plausible difference in the means. It is worth noting in passing that we use the standard <code class="language-plaintext highlighter-rouge">ggboxplot(...)</code> function, but wrap it in a call to the <code class="language-plaintext highlighter-rouge">plot(...)</code> function. This outputs the result to a separate graphics window, from which we can paste the resulting graphic as a Windows metafile. This is not ideal, but as yet I have not found a way to draw a plot directly in an Excel worksheet.</p>

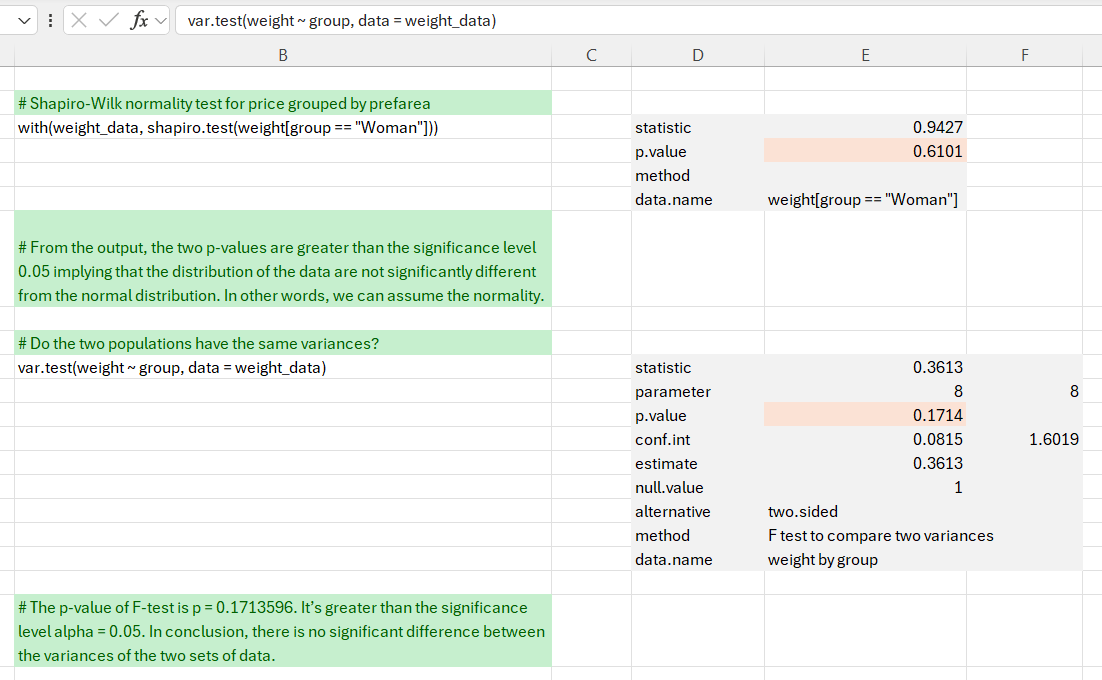
<p>Before doing the t-test we want to check the independent t-test assumptions. Specifically, the two samples are independent since the observations come from distinct groups (men and women). We also want to check that the data from each of the groups follow a normal distribution. We perform a Shapiro-Wilk normality test for each group. We could also have inspected the data visually with a histogram or a qqplot.</p>

<p>From the output of the Shapiro-Wilk test, the two p-values are greater than the significance level 0.05 implying that the distribution of the data are not significantly different from the normal distribution. Therefore, we can assume the observations from each group follow a normal distribution.</p>

<h4 id="comparing-variances">Comparing Variances</h4>
<p>In addition to the Shapiro-Wilk test, we perform an F-test to compare variances since one of the assumptions of a t-test is that the population variances should be equal. The output of <code class="language-plaintext highlighter-rouge">var.test</code> is a list containing the individual results, which we display. The p-value of F-test is p = 0.17136. Since it is greater than the significance level (alpha = 0.05) we conclude that there is no significant difference between the variances of the two sets of data. Therefore, we can use the classic t-test which assume equality of the two variances.</p>

<p><img src="https://adam-gladstone.github.io/assets/images/ComparingVariances.png" alt="Comparing Variances" /></p>

<h4 id="unpaired-two-samples-t-test">Unpaired two-samples t-test</h4>
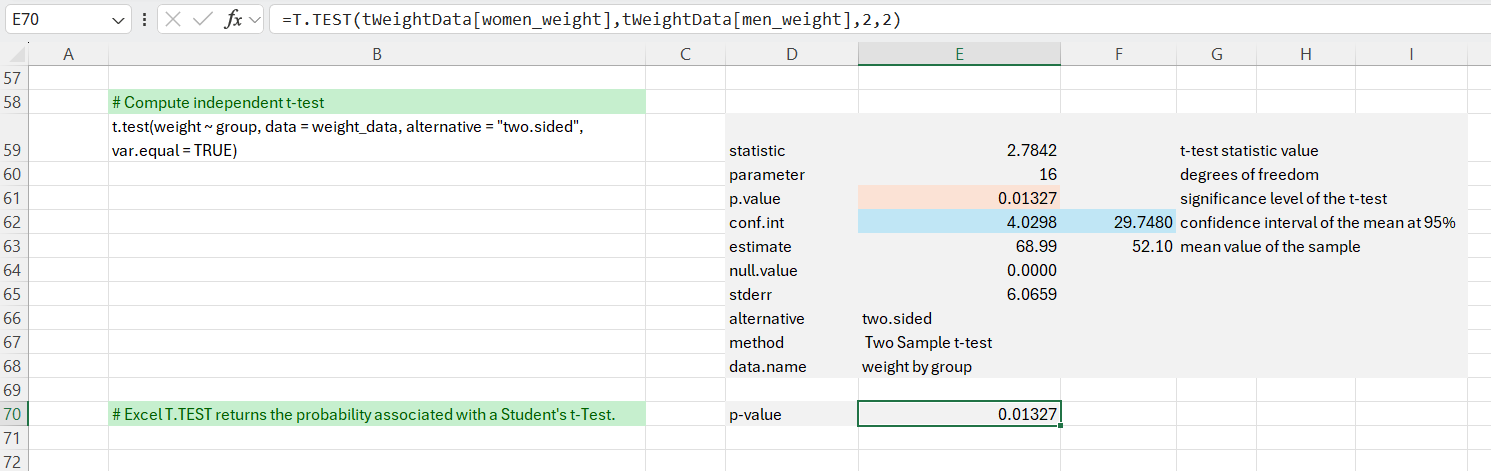
<p>Finally, we compute an independent t-test. As before, we extract the individual statistics. The p-value of the test is 0.01327, which is less than the significance level (alpha = 0.05). We can conclude that men’s average weight is significantly different from women’s average weight in this dataset with a p-value = 0.01327.</p>

<p><img src="https://adam-gladstone.github.io/assets/images/IndependentTTest.png" alt="T-Test" /></p>

<p>We can also check that Excel’s <code class="language-plaintext highlighter-rouge">=T.TEST()</code> function produces the same result.</p>

<h3 id="analysis-ii">Analysis II</h3>
<h4 id="one-way-anova">One-way ANOVA</h4>
<p>For the second analysis, we want to perform a one-way ANOVA test. We use the built-in R data set named <a href="https://www.rdocumentation.org/packages/datasets/versions/3.6.2/topics/PlantGrowth"><code class="language-plaintext highlighter-rouge">PlantGrowth</code></a>. It contains the weight of plants obtained under a control and two different treatment conditions.</p>

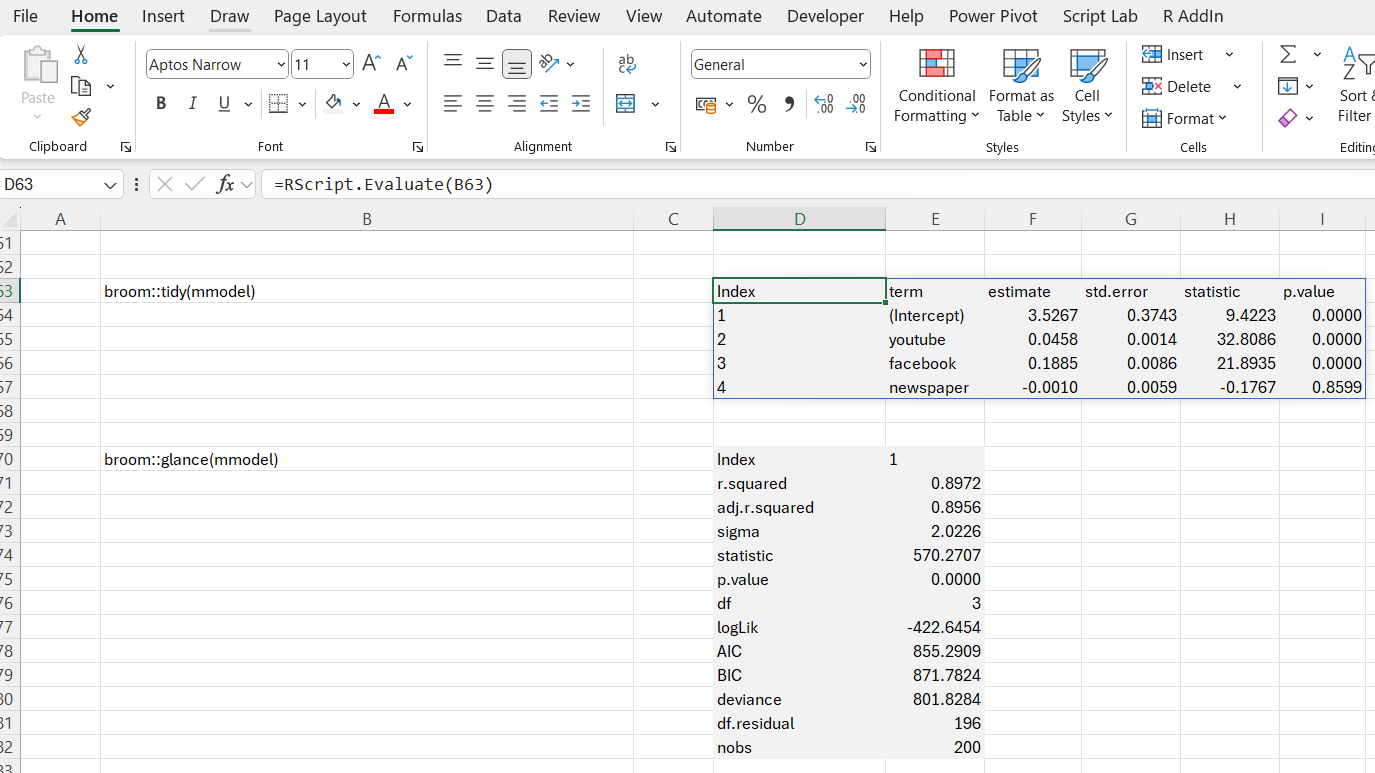
<p>As before, we display a brief summary of the data and a boxplot to visually display the means of each group. Then we compute the one-way ANOVA. The output contains a lot of data, so we extract the individual components as required.</p>

<p>We can also use the <code class="language-plaintext highlighter-rouge">anova</code> function to summarise the test results.</p>

<p><img src="https://adam-gladstone.github.io/assets/images/ComputeOneWayAnova.png" alt="One-way ANOVA" /></p>

<p>As the p-value is less than the significance level 0.05, we can conclude that there are significant differences between the groups.</p>

<p>Because the test result is significant, we compute <a href="https://www.rdocumentation.org/packages/stats/versions/3.6.2/topics/TukeyHSD">Tukey HSD</a> for performing multiple pairwise-comparison between the means of groups. It can be seen from the output, that only the difference between <code class="language-plaintext highlighter-rouge">trt2</code> and <code class="language-plaintext highlighter-rouge">trt1</code> is significant with an adjusted p-value of 0.012. The same test can be performed using Excel’s Analysis ToolPak ‘Single Factor ANOVA’ function. This is demonstrated in the ‘Single Factor ANOVA’ worksheet.</p>

<h3 id="wrap-up">Wrap Up</h3>
<p>In this post we have used R in Excel to perform some basic tests for inferential statistics. We have performed a Shapiro-Wilk test, an F-test, an independent samples t-test and a one-way ANOVA. In passing, we have also seen how to plot data and how to set up and retrieve model results. While some of this could have been done using Excel’s native functions, the advantage of using R from within Excel is that it gives us access to an extensive ecosystem, which in turn gives us a good deal of flexibility in creating solutions.</p>]]></content><author><name>Adam Gladstone</name></author><category term="R-project" /><category term="R" /><category term="RStudio" /><category term="r-project" /><category term="Office365" /><category term="Excel" /><category term="ExcelRAddIn" /><summary type="html"><![CDATA[This post describes using R functions to perform a number of inferential statistics tests in an Excel worksheet.]]></summary></entry><entry><title type="html">Part I - Using R in Excel - Descriptive Statistics</title><link href="https://adam-gladstone.github.io/r-project/Part-I-Using-R-in-Excel-Descriptive-Statistics/" rel="alternate" type="text/html" title="Part I - Using R in Excel - Descriptive Statistics" /><published>2025-07-25T00:00:00+00:00</published><updated>2025-07-25T00:00:00+00:00</updated><id>https://adam-gladstone.github.io/r-project/Part%20I%20-%20Using%20R%20in%20Excel%20-%20Descriptive%20Statistics</id><content type="html" xml:base="https://adam-gladstone.github.io/r-project/Part-I-Using-R-in-Excel-Descriptive-Statistics/"><![CDATA[<h3 id="introduction">Introduction</h3>
<p>The purpose of this series of posts is to demonstrate some use-cases for <strong>R in Excel</strong> using the <strong>ExcelRAddIn</strong> component (disclaimer: I am the developer of this add-in: <a href="https://github.com/Adam-Gladstone/Office365AddIns">ExcelRAddIn</a>). The fundamental rationale for the add-in is that it allows access to the extensive R ecosystem within an Excel worksheet. Excel provides many excellent facilities for data wrangling and analysis. However, for certain types of statistical data analysis, the limitations of the built-in functions even alongside the  Analysis ToolPak is not sufficient, and R provides superior facilities (for example, for performing LDA, PCA, forecasting and time series analysis to mention a few).</p>

<p>This series of posts demonstrates four main areas where R is useful in Excel: <em>descriptive statistics</em>, <em>linear regression</em>, <em>forecasting</em>, and <em>accessing Python</em>. Along the way, we will see that using R in Excel is no more difficult than writing a formula and calling the <strong>ExcelRAddIn</strong> to evaluate it. The ‘trick’, if there is one, is unpacking the results into a form that Excel understands and which can be used in a worksheet. We will see several examples of how to do this.</p>

<p>Installing and setting up the <strong>ExcelRAddIn</strong> is described <a href="https://github.com/Adam-Gladstone/Office365AddIns?tab=readme-ov-file#installation">here</a>. Each part of the series is accompanied by an Excel workbook with the R scripts. 
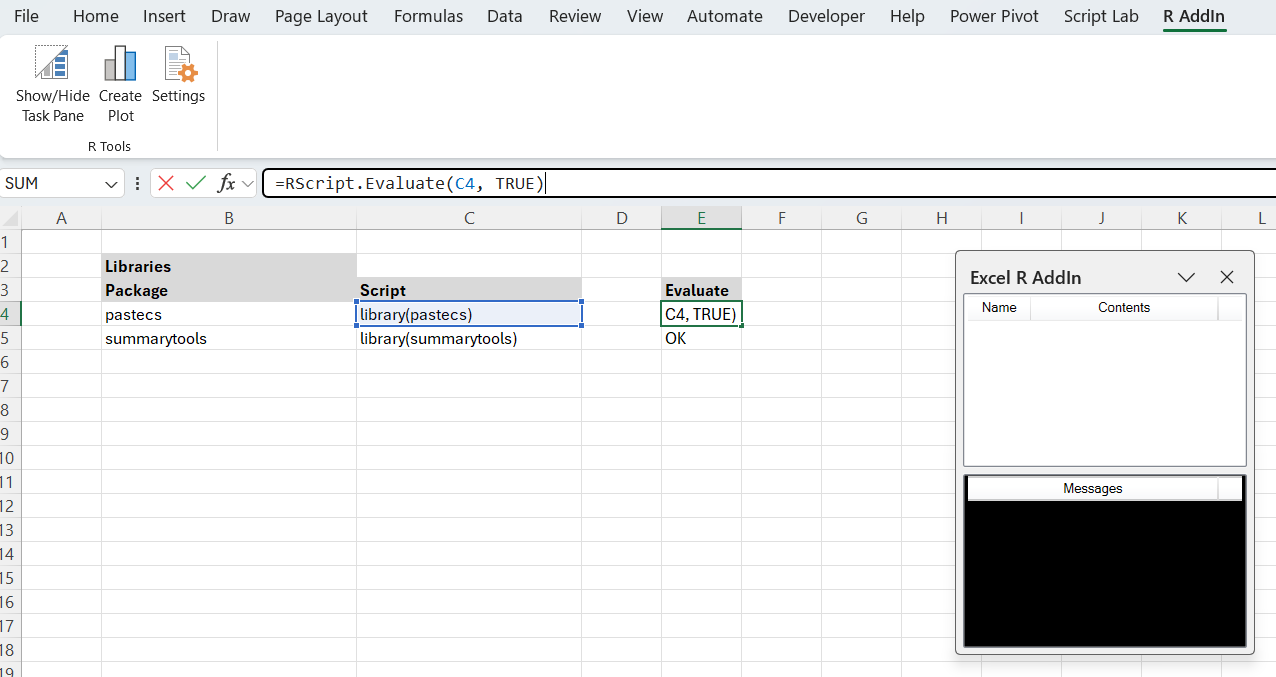
The workbooks depend on the <code class="language-plaintext highlighter-rouge">ExcelRAddIn-AddIn64.dll</code>, so this should be loaded first, and the “R AddIn” menu should appear on the right-hand side of the menu bar.</p>

<p><img src="https://adam-gladstone.github.io/assets/images/ExcelRAddIn.png" alt="ExcelRAddIn" /></p>

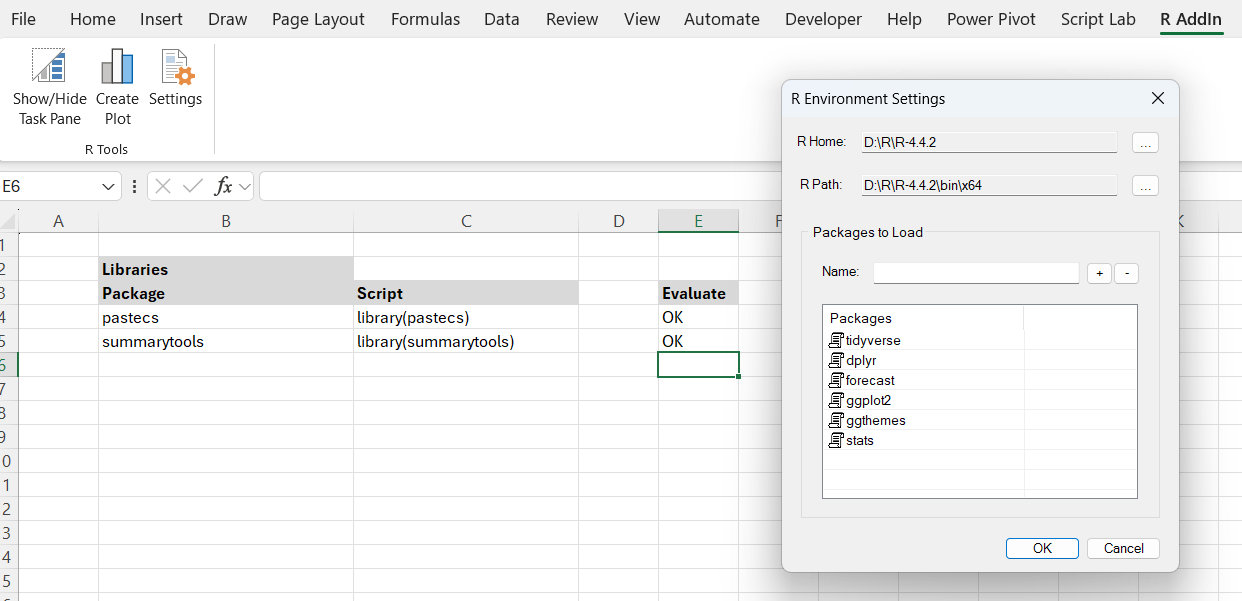
<p>The task pane is empty until the first script is evaluated. This will initialise R using the directories in the “Settings”. The default packages I use are tidyverse, dplyr, forecast, ggplot2, ggthemes, as shown below:</p>

<p><img src="https://adam-gladstone.github.io/assets/images/R-EnvironmentSettings.png" alt="R Environment Settings" /></p>

<p>The workbook for this part of the series is: <a href="https://adam-gladstone.github.io/assets/images/Part-I-R-in-Excel-Descriptive-Statistics.xlsx">Part I - R in Excel - Descriptive Statistics.xlsx</a>. The workbooks all have a similar structure just to keep things organised. The ‘References’ worksheet lists any links to external references. The ‘Libraries’ worksheet loads additional (non-default) packages. The ‘Datasets’ worksheet contains any data referenced in the worksheets.</p>

<h3 id="descriptive-statistics">Descriptive statistics</h3>

<h4 id="loading-data">Loading Data</h4>
<p>The first step is to load some data. This dataset comes from <strong>“Linear Models with R”</strong> by Julian Faraway. In this example, I have loaded the data into Excel from a csv file (<a href="https://adam-gladstone.github.io/assets/images/GalapagosData.csv">GalapagosData.csv</a>) using Power Query. The data has been tidied up and I have created a table (<code class="language-plaintext highlighter-rouge">tableGalapagos</code>) that can be referenced in the workbook.</p>

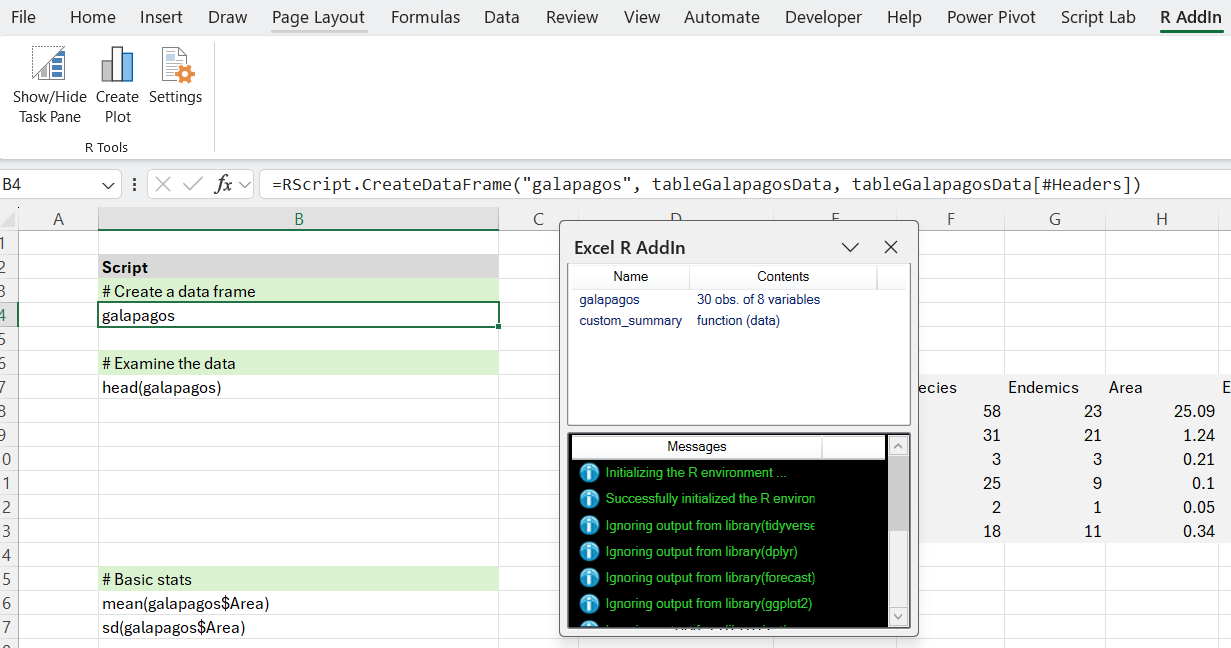
<p>In the Descriptive Statistics worksheet, we first create a data frame using the <code class="language-plaintext highlighter-rouge">CreateDataFrame</code> function.</p>

<p><code class="language-plaintext highlighter-rouge">=RScript.CreateDataFrame("galapagos", tableGalapagosData, tableGalapagosData[#Headers])</code></p>

<p>This function is part of the add-in and simplifies the creation of dataframes. There are also functions to create vectors and matrices. We pass in a name (which will appear in the R environment) and the data and headers. The final parameter (‘Type’ =&gt; character, complex, integer, logical, numeric) is optional; the RType is now determined from the data if possible. This makes it somewhat easier to create objects to pass to R from Excel.</p>

<p><img src="https://adam-gladstone.github.io/assets/images/CreateDataFrame.png" alt="Create Data Frame" /></p>

<p>This copies the data into the R environment. There are a number of alternatives to this approach. We could have loaded the csv file directly into R using:</p>

<p><code class="language-plaintext highlighter-rouge">galapagos &lt;- read.csv("D:\Development\...\GalapagosData.csv")</code></p>

<p>By loading the data into Excel and then copying it to R, we can leverage the Excel import using Power Query, so we automatically get grouping, filtering etc, and can immediately create PivotTables. The downside is that we need to make a copy into R, and this means ensuring the data types are ‘viable’. This is particularly important with dates.</p>

<h4 id="obtaining-statistics">Obtaining Statistics</h4>
<p>Now that we have the data frame in R (and in Excel), we can obtain some descriptive statistics. If we were doing this exclusively in Excel, we might use individual formulas (<code class="language-plaintext highlighter-rouge">=COUNT()</code>, <code class="language-plaintext highlighter-rouge">=AVERAGE()</code>, <code class="language-plaintext highlighter-rouge">=STDEV.S()</code> and so on). Using R, we can accomplish the same thing.</p>

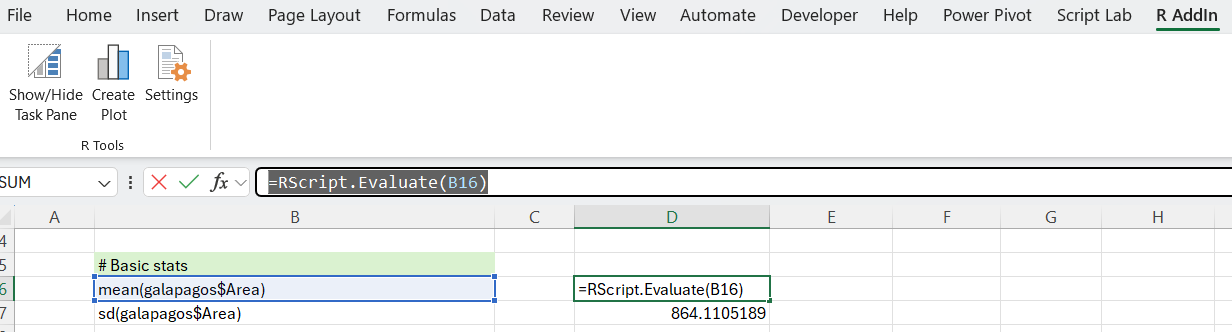
<p><img src="https://adam-gladstone.github.io/assets/images/BasicStatistics.png" alt="Basic Statistics" /></p>

<p>As expected, this returns the mean and standard deviation.</p>

<p>We can improve on this using some additional R functions: <code class="language-plaintext highlighter-rouge">sapply</code> together with <code class="language-plaintext highlighter-rouge">fivenum</code> (<strong>fivenum</strong> returns Tukey’s five number summary (minimum, lower-hinge, median, upper-hinge, maximum) for the input data).</p>

<p><code class="language-plaintext highlighter-rouge">as.data.frame(sapply(galapagos[,2:8], fivenum))</code></p>

<p>When evaluated, all this does is to apply the <code class="language-plaintext highlighter-rouge">fivenum</code> function to columns 2 to 8 (zero-based) of the galapagos dataset, and coerce the result into a dataframe. If we don’t do this we don’t get back the column headings (which is not tremendously useful). You may also have noticed that we have to determine the return values from the documentation. There doesn’t seem to be a way of retrieving this meta data from the function.</p>

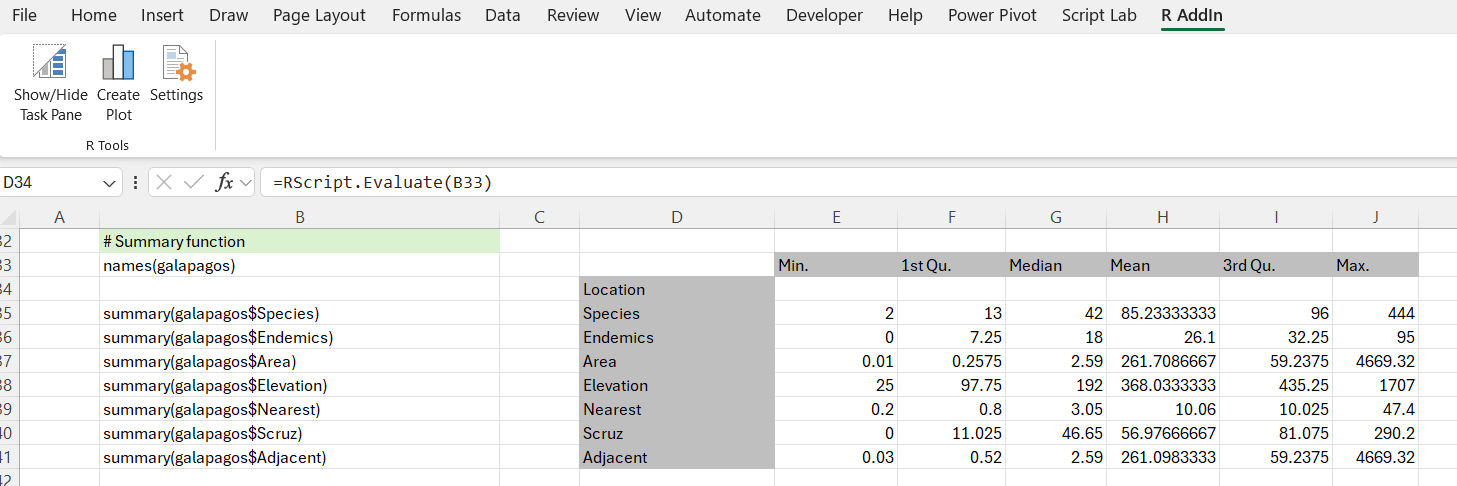
<p>An alternative to the five-number summary is to use the built-in <code class="language-plaintext highlighter-rouge">summary(...)</code> function. Unfortunately the output from this does not work well with Excel, so we need to massage the results in order to obtain a decent table showing the summary with labels.</p>

<p><img src="https://adam-gladstone.github.io/assets/images/SummaryFunction.png" alt="Summary Function" /></p>

<p>Basically, we get the column labels from the galapagos dataset using: <code class="language-plaintext highlighter-rouge">names(galapagos)</code>, and we get the labels for the summary using: <code class="language-plaintext highlighter-rouge">names(summary(galapagos$Species))</code>. Then for each column of the data we are interested in, we request the summary. For example: <code class="language-plaintext highlighter-rouge">summary(galapagos$Elevation)</code>.</p>

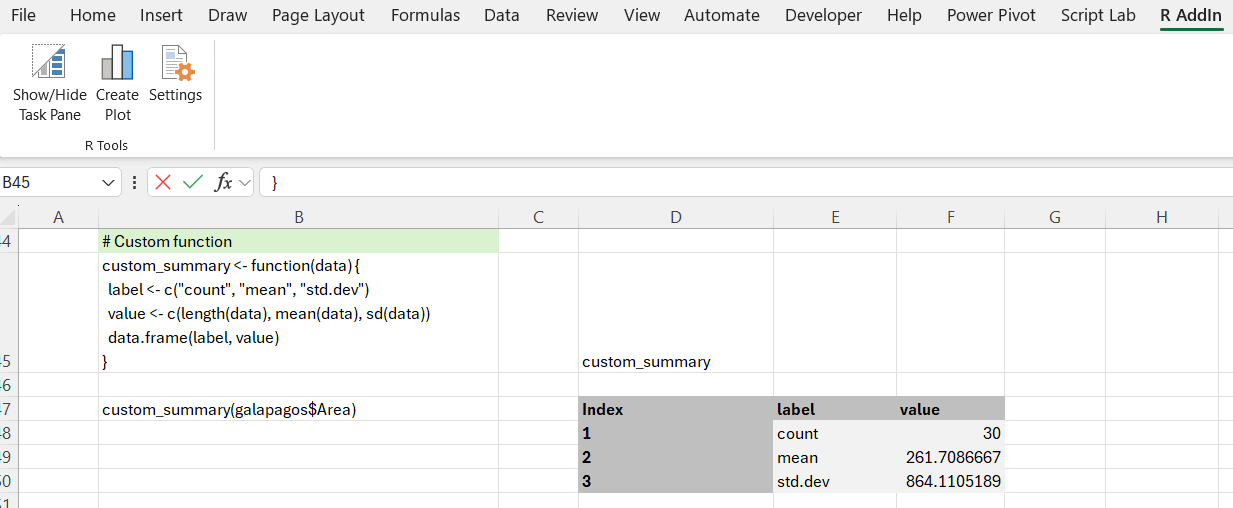
<p>Now that we are massaging the results, we might even consider using a custom function. We can, for example, define a function that returns a dataframe consisting of a label and the corresponding statistic:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>custom_summary &lt;- function(data) {
  label &lt;- c("count", "mean", "std.dev")
  value &lt;- c(length(data), mean(data), sd(data))
  data.frame(label, value)
}
</code></pre></div></div>

<p>Evaluating the function with the script:</p>

<p><code class="language-plaintext highlighter-rouge">custom_summary(galapagos$Area)</code></p>

<p>outputs a small table, as follows:</p>

<p><img src="https://adam-gladstone.github.io/assets/images/CustomFunction.png" alt="Custom Function" /></p>

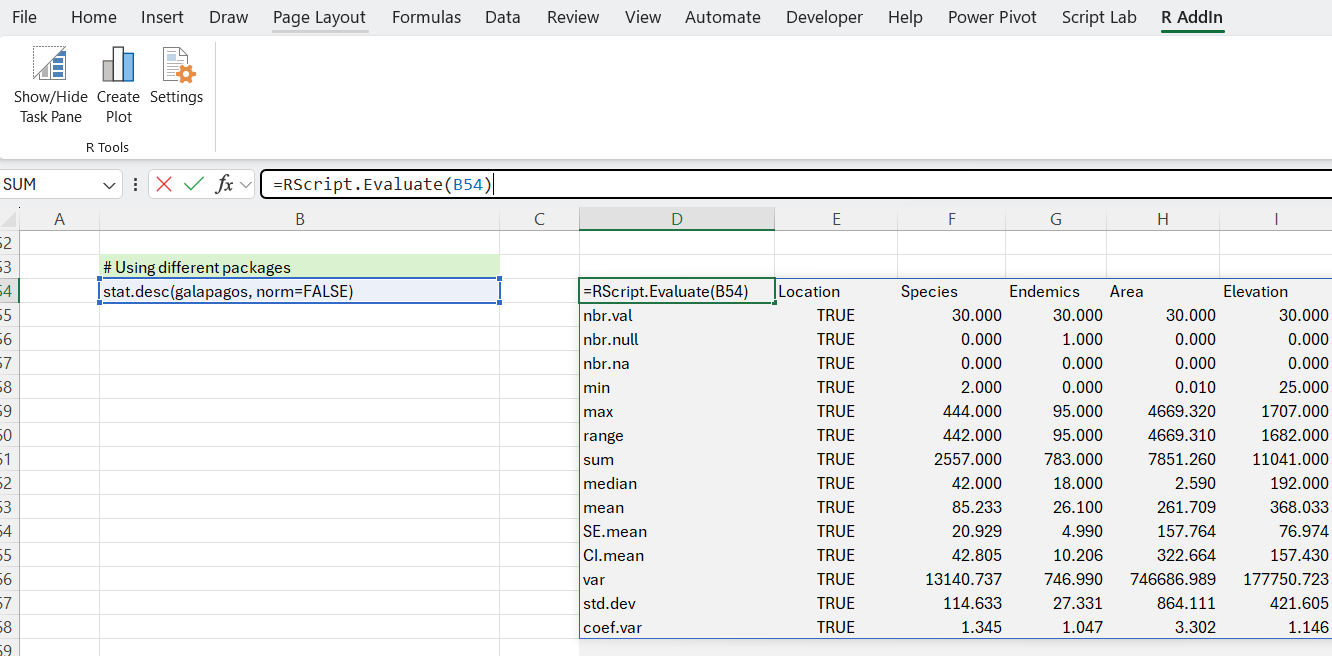
<p>If all this seems quite a lot of hard work, or you are looking for a more sophisticated approach - perhaps a summary that tests the normality of the distribution of the data - then you might prefer to use a summary function from a different package. There are several to choose from. Here we use <code class="language-plaintext highlighter-rouge">pastecs</code> <a href="https://www.rdocumentation.org/packages/pastecs/versions/1.4.2/topics/stat.desc">pastecs</a> and <code class="language-plaintext highlighter-rouge">summarytools</code> <a href="https://www.rdocumentation.org/packages/sjmisc/versions/2.8.10/topics/descr">summarytools</a>. Both of these give good results with minimal effort:</p>

<p><img src="https://adam-gladstone.github.io/assets/images/StatsDescFunction.png" alt="stats.desc function from pastecs" /></p>

<h3 id="wrap-up">Wrap up</h3>
<p>In this post, we have seen various approaches to obtaining descriptive statistics using R in Excel via the <strong>ExcelRAddIn</strong>. We have introduced some basic approaches (similar to what Excel natively offers). But we have also seen some more advanced usage that demonstrates how useful it can be to have access to R functionality in Excel. The next post covers linear regression using R in Excel.</p>]]></content><author><name>Adam Gladstone</name></author><category term="R-project" /><category term="R" /><category term="RStudio" /><category term="r-project" /><category term="Office365" /><category term="Excel" /><category term="ExcelRAddIn" /><summary type="html"><![CDATA[If you are an R user, and you have ever wanted to access the functionality offered by your favourite R packages in Excel, then this series of posts may be of interest to you.]]></summary></entry><entry><title type="html">Part II - Using R in Excel - Linear Regression</title><link href="https://adam-gladstone.github.io/r-project/Part-II-Using-R-in-Excel-Linear-Regression/" rel="alternate" type="text/html" title="Part II - Using R in Excel - Linear Regression" /><published>2025-07-25T00:00:00+00:00</published><updated>2025-07-25T00:00:00+00:00</updated><id>https://adam-gladstone.github.io/r-project/Part%20II%20-%20Using%20R%20in%20Excel%20-%20Linear%20Regression</id><content type="html" xml:base="https://adam-gladstone.github.io/r-project/Part-II-Using-R-in-Excel-Linear-Regression/"><![CDATA[<h3 id="introduction">Introduction</h3>
<p>In the <a href="https://adam-gladstone.github.io/r-project/Part-I-Using-R-in-Excel-Descriptive-Statistics/">first part</a> of this series, I looked at using R in Excel to obtain descriptive statistics. In this second part of the series I am going to look at using R in Excel to perform linear regression, specifically using the <code class="language-plaintext highlighter-rouge">lm()</code> <a href="https://www.rdocumentation.org/packages/stats/versions/3.6.2/topics/lm">function</a>. <code class="language-plaintext highlighter-rouge">lm()</code> is a real workhorse function. It can be used to carry out both single and multiple regression and different types of analysis of variance. For this demonstration I will only focus on single and multiple regression.</p>

<p>The workbook for this part of the series is: <a href="https://adam-gladstone.github.io/assets/images/Part-II-R-in-Excel-Linear-Regression.xlsx">“Part II - R in Excel - Linear Regression.xlsx”</a>. As before, the ‘References’ worksheet lists links to external references. The ‘Libraries’ worksheet loads additional (non-default) packages. In this demonstration, I use the <code class="language-plaintext highlighter-rouge">datarium</code> and <code class="language-plaintext highlighter-rouge">broom</code> packages. The ‘Datasets’ worksheet contains the data referenced in the worksheets.</p>

<h3 id="the-data">The Data</h3>
<p>The dataset is the marketing dataset from the <code class="language-plaintext highlighter-rouge">datarium</code> package. It consists of a data frame containing the impact of three advertising medias (youtube, facebook and newspaper) on sales. Data are the advertising budget in thousands of dollars along with the sales. The advertising experiment has been repeated 200 times. The dataset is described <a href="https://search.r-project.org/CRAN/refmans/datarium/html/marketing.html">here</a>.</p>

<p><img src="https://adam-gladstone.github.io/assets/images/MarketingDataset.png" alt="Marketing Dataset" /></p>

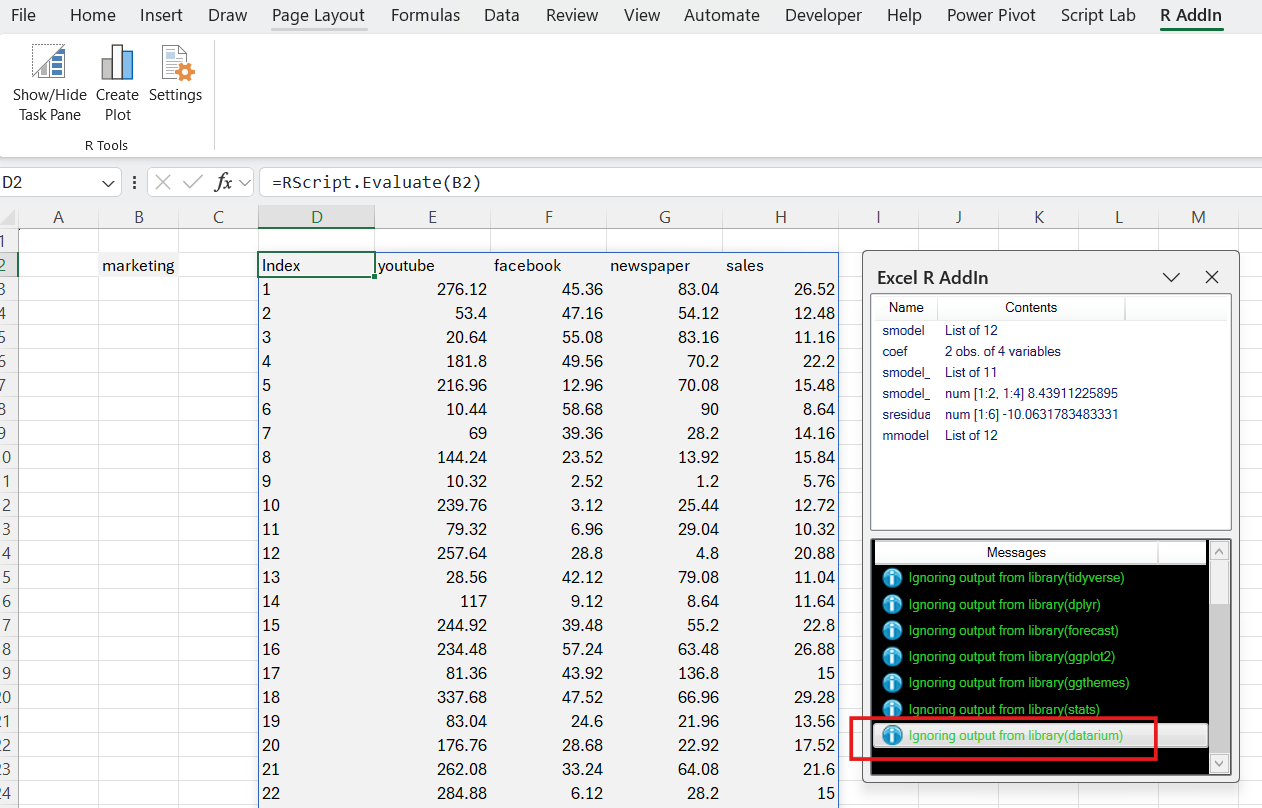
<p>If the dataset is not available, check that the <code class="language-plaintext highlighter-rouge">datarium</code> library is loaded by going to the Libraries worksheet and evaluating:</p>

<p><code class="language-plaintext highlighter-rouge">=RScript.Evaluate(library(datarium), TRUE)</code></p>

<h3 id="simple-linear-regression">Simple Linear Regression</h3>
<p>In the Simple Linear Regression worksheet we create a simple linear model.</p>

<p><code class="language-plaintext highlighter-rouge">smodel &lt;- lm(sales ~ youtube, data = marketing)</code></p>

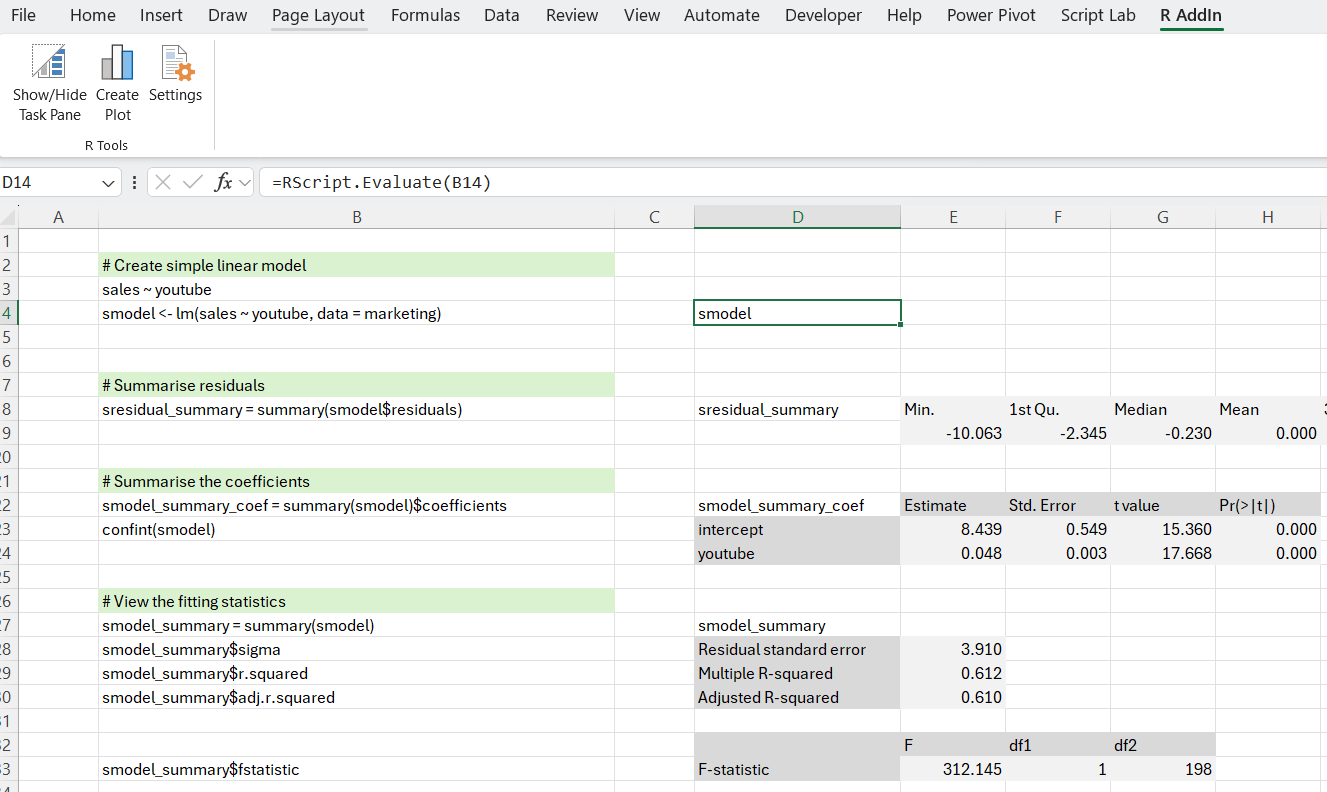
<p>As we did in the first part of this series, we unpack the ‘smodel’. Mostly this is simply a question of evaluating the corresponding R objects, for example the residuals and the coefficients. We also request the 95% confidence intervals for the coefficients.</p>

<p><img src="https://adam-gladstone.github.io/assets/images/ResidualsAndCoefficients.png" alt="Residuals and Coefficients" /></p>

<p>At this point, we can compare the results to the Summary Output provided by the Analysis ToolPak’s regression function (including the 95% confidence intervals).</p>

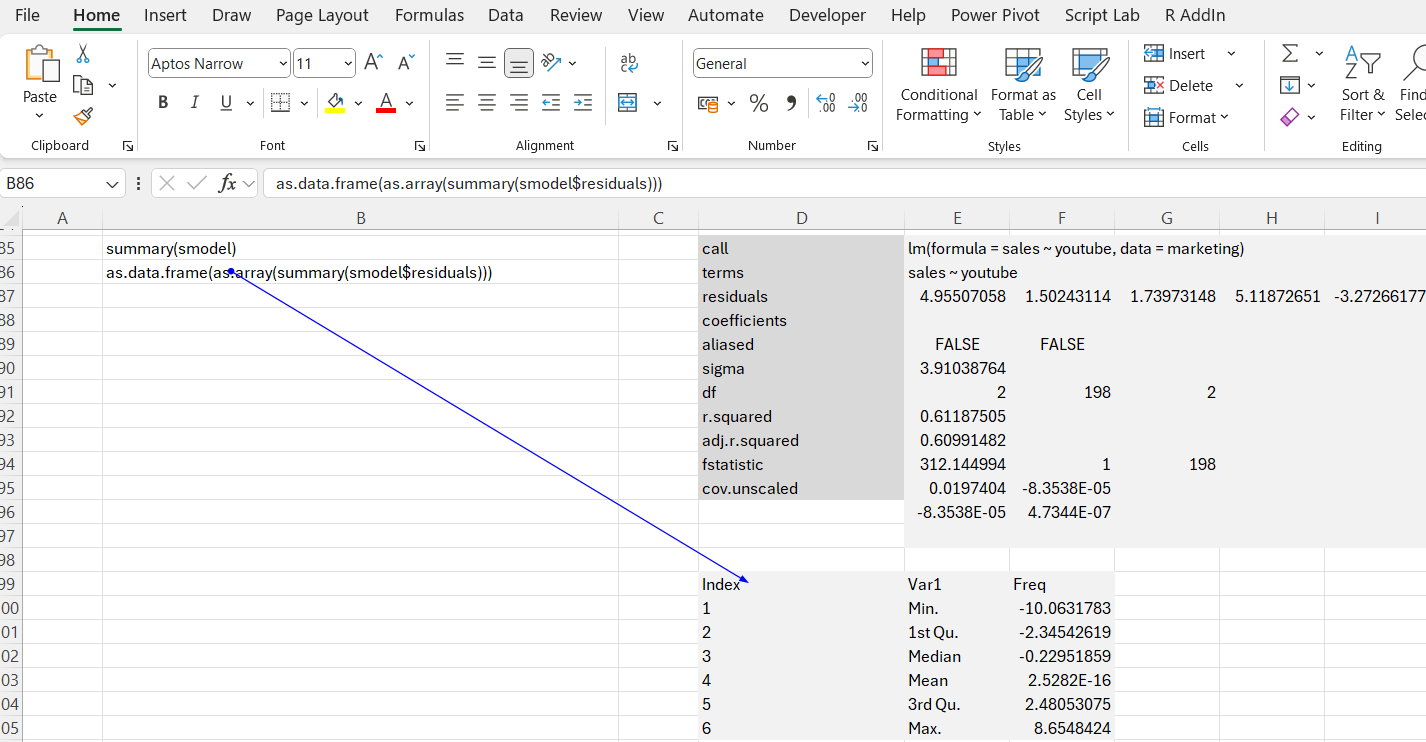
<p>It’s worth emphasising that the output that is returned to Excel via the add-in is not ‘formatted’ as it is in R/RStudio. If we call <code class="language-plaintext highlighter-rouge">summary(smodel)</code> in R we are presented with a familiar tabular output summarising the main features of the model. However, what is returned to Excel via the add-in is more basic. So it is worth spending some time looking at this. We can see from the add-in environment, that the <code class="language-plaintext highlighter-rouge">smodel_summary</code> is a list of 11 items. To use this we need to unpack some of the individual list items.</p>

<p><img src="https://adam-gladstone.github.io/assets/images/ModelSummaryList.png" alt="Model Summary" /></p>

<p>Here we can see the actual call made and the details of the model including the statistics (<code class="language-plaintext highlighter-rouge">sigma</code>, <code class="language-plaintext highlighter-rouge">r-squared</code> and so on). It needs some extra work to unpack the summary data from the model residuals in order to produce a tabular output.</p>

<p><code class="language-plaintext highlighter-rouge">as.data.frame(as.array(summary(smodel$residuals)))</code></p>

<p>This formula summarises the model residuals and coerces the data into an array first (to get the names) and then as a data frame. We perform a similar operation to get the coefficients into a tabular format.</p>

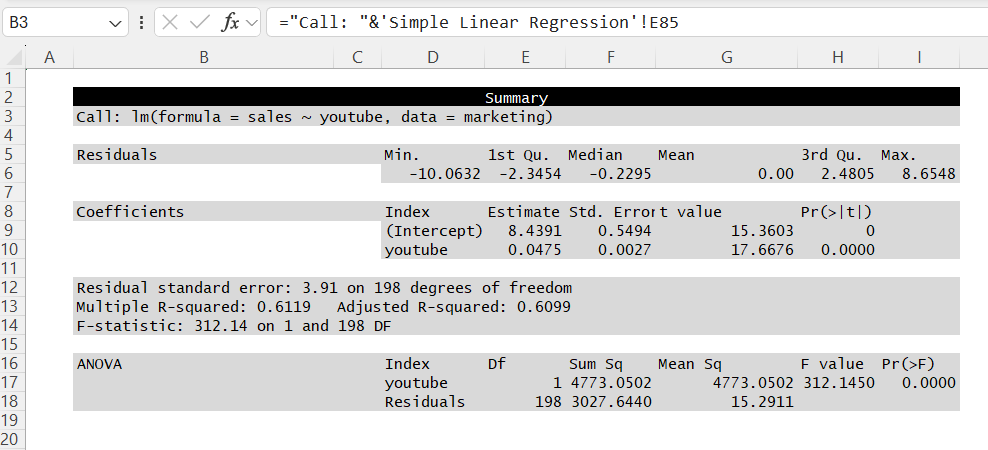
<p>With all the data available in this form, and with a little effort, we can now construct a summary output similar to R.</p>

<p><img src="https://adam-gladstone.github.io/assets/images/SummaryOutput.png" alt="Summary Output" /></p>

<h3 id="multiple-linear-regression">Multiple Linear Regression</h3>
<p>The next worksheet demonstrates multiple linear regression using the same marketing data. This is similar to the previous worksheet and illustrates how to extract relevant values from the returned model data.</p>

<p>However, in this case we make use of the package <code class="language-plaintext highlighter-rouge">broom</code>. This can help <a href="https://cran.r-project.org/web/packages/broom/vignettes/broom.html">tidy up</a> the output data.</p>

<p><img src="https://adam-gladstone.github.io/assets/images/TidyOutput.png" alt="Tidy Output" /></p>

<p>In previous examples, we have extracted model results by concatenating the returned model name with labels from the model. To make it easier to retrieve results, the add-in provides some additional functions for querying models: <code class="language-plaintext highlighter-rouge">Model.Results</code> outputs a list of results from the model. <code class="language-plaintext highlighter-rouge">Model.Result</code> outputs the result obtained from one item of the list of model results. Optionally, the result can be formatted as a data frame. This is somewhat more convenient than having to evaluate scripts of the form <code class="language-plaintext highlighter-rouge">model name'$coeffcients</code>, etc. By extracting the model data and the summary, we can construct an output that is similar to that provided by R.</p>

<h3 id="logistic-regression">Logistic Regression</h3>
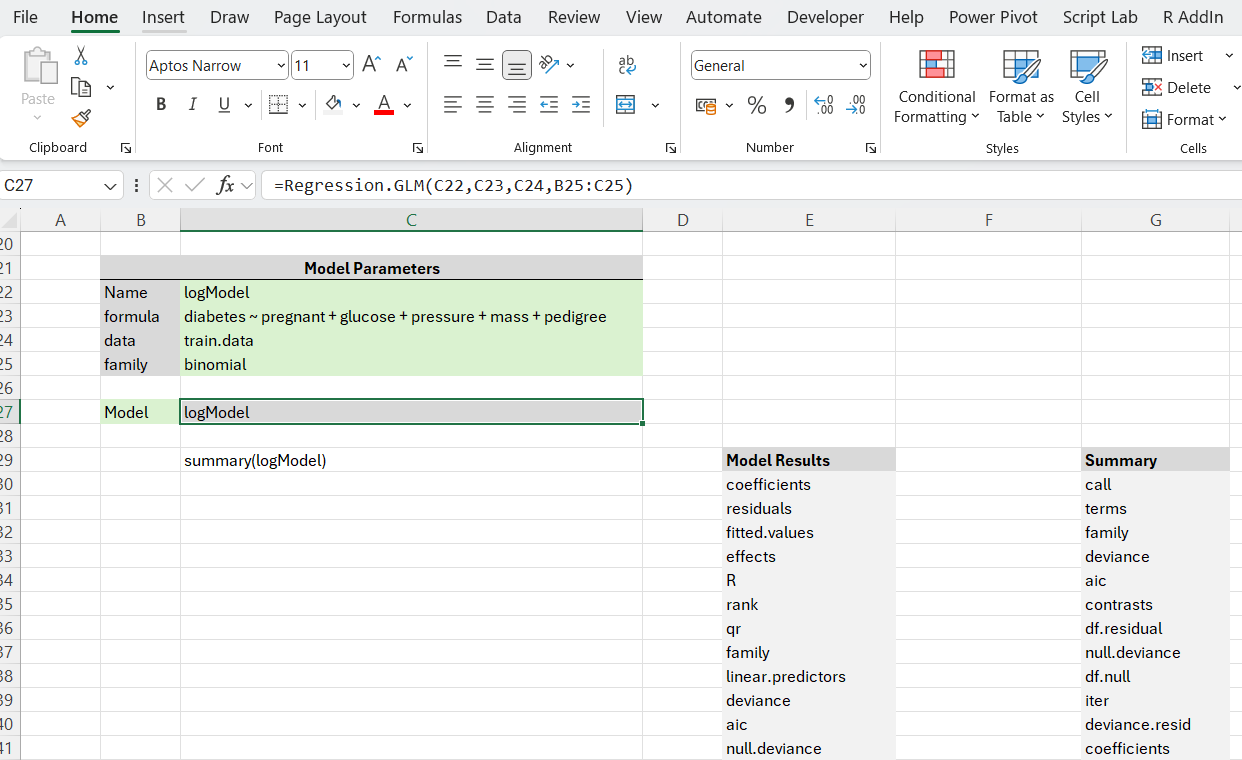
<p>The final example demonstrates logistic regression. At this point you might be thinking that this massaging and extracting output data is not entirely satisfactory. It’s a lot of work and it can be quite brittle (if the cell references change, for example). Furthermore, as the models become more complicated (see <a href="https://adam-gladstone.github.io/r-project/Part-III-Using-R-in-Excel-Forecasting/">Part III in the series</a>) this approach potentially becomes messier. To mitigate this, the add-in provides a couple of wrapper functions around regression. These help with both the setup and the output of more complex models.</p>

<p><img src="https://adam-gladstone.github.io/assets/images/RegressionGLM.png" alt="Regression.GLM" /></p>

<p>The model inputs are specified as a block of parameters, and the function <code class="language-plaintext highlighter-rouge">Regression.GLM</code> is used instead of the R script equivalent using <code class="language-plaintext highlighter-rouge">glm</code>. The model outputs can be ‘queried’ using the <code class="language-plaintext highlighter-rouge">Model.Results</code> and the <code class="language-plaintext highlighter-rouge">Model.Result</code> formulas. However, even with this, it takes some effort to output a summary similar to the one provided by R.</p>

<h3 id="wrap-up">Wrap Up</h3>
<p>In this post, we have looked at how to use R in Excel to perform linear regression, and we have spent some time demonstrating how to extract the different components from the model data. This will be useful in the next two parts of this series.</p>]]></content><author><name>Adam Gladstone</name></author><category term="R-project" /><category term="R" /><category term="RStudio" /><category term="r-project" /><category term="Office365" /><category term="Excel" /><category term="ExcelRAddIn" /><summary type="html"><![CDATA[If you have ever wanted to use R's workhorse lm(...) function in an Excel worksheet, then this post may be of interest to you.]]></summary></entry><entry><title type="html">Part III - Using R in Excel - Forecasting</title><link href="https://adam-gladstone.github.io/r-project/Part-III-Using-R-in-Excel-Forecasting/" rel="alternate" type="text/html" title="Part III - Using R in Excel - Forecasting" /><published>2025-07-25T00:00:00+00:00</published><updated>2025-07-25T00:00:00+00:00</updated><id>https://adam-gladstone.github.io/r-project/Part%20III%20-%20Using%20R%20in%20Excel%20-%20Forecasting</id><content type="html" xml:base="https://adam-gladstone.github.io/r-project/Part-III-Using-R-in-Excel-Forecasting/"><![CDATA[<h3 id="introduction">Introduction</h3>
<p>We have already seen how to obtain descriptive statistics in <a href="https://adam-gladstone.github.io/r-project/Part-I-Using-R-in-Excel-Descriptive-Statistics/">Part I</a> and how to use <code class="language-plaintext highlighter-rouge">lm()</code> in <a href="https://adam-gladstone.github.io/r-project/Part-II-Using-R-in-Excel-Linear-Regression/">Part II</a>. In this part (Part III) of the series we will look at using R in Excel to perform forecasting and time series analysis.</p>

<p>In the previous two parts we have seen different ways to handle the output from R function calls, unpacking and massaging the data as required. In this part we are going to focus on setting up and interacting with a number of models in the ‘forecast’ package (<code class="language-plaintext highlighter-rouge">fpp2</code>).</p>

<p>The workbook for this part of the series is: <a href="https://adam-gladstone.github.io/assets/images/Part-III-R-in-Excel-Forecasting.xlsx">“Part III - R in Excel - Forecasting.xlsx”</a>. As before, the ‘References’ worksheet lists links to external references. The ‘Libraries’ worksheet loads additional (non-default) packages. In this demonstration, I use the <code class="language-plaintext highlighter-rouge">fpp2</code> package. The ‘Datasets’ worksheet contains the data referenced in the worksheets.</p>

<h3 id="moving-average">Moving Average</h3>
<p>In this worksheet we are looking at the moving average function in the <a href="https://cran.r-project.org/web/packages/forecast/forecast.pdf">forecast package</a>. <code class="language-plaintext highlighter-rouge">ma</code> computes a simple moving average smoother of a given time series. The data we use consists of ice cream sales.</p>

<p>In the previous posts we have used ‘scripts’ to call R functions. So, in this case we could evaluate</p>

<p><code class="language-plaintext highlighter-rouge">ma(Sales, 3, FALSE)</code></p>

<p>and get back the smoothed time series.</p>

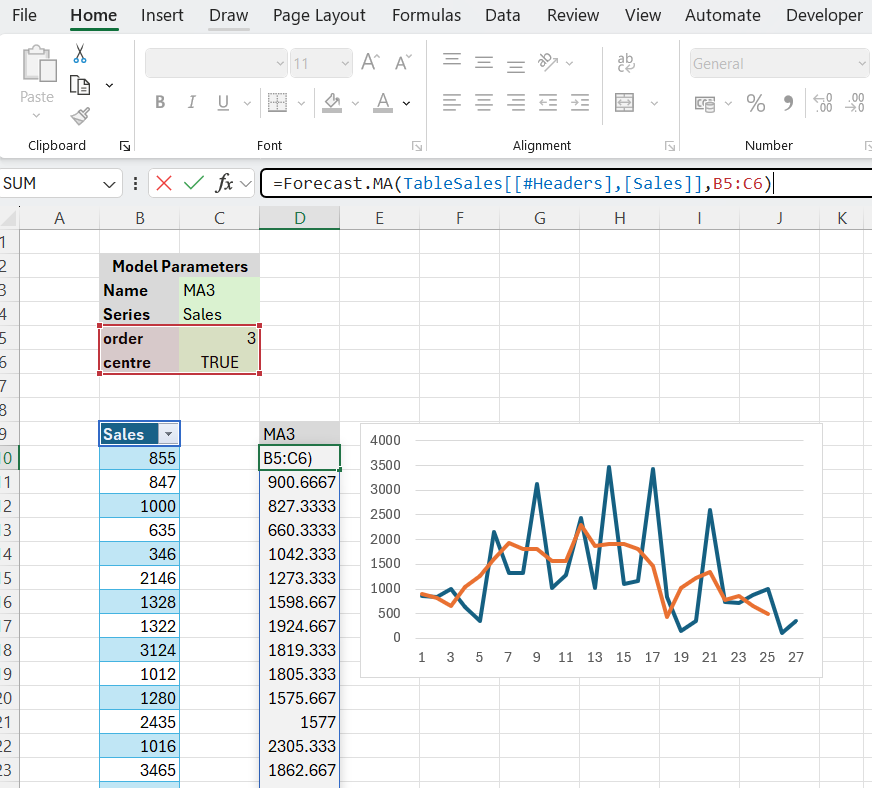
<p>However, as the models become more complex, and the number and types of parameters increases, this approach becomes less manageable. An alternative is to use one of the custom <code class="language-plaintext highlighter-rouge">Forecast.</code> functions provided by the add-in. This allows us to set up the model parameters as a block of named parameters with their corresponding values. We have already seen an example of this in <a href="https://adam-gladstone.github.io/r-project/Part-II-Using-R-in-Excel-Linear-Regression/">Part II</a> where we set up a logistic regression model. In the case of <code class="language-plaintext highlighter-rouge">Forecast.MA</code>, we give the model a descriptive name. We know from the documentation that the model takes two parameters: the order (<em>“order of moving average smoother”</em>) and the center (<em>“if TRUE, then the moving average is centred for even orders”</em>). Then we just call a regular Excel worksheet function.</p>

<p><img src="https://adam-gladstone.github.io/assets/images/MovingAverageModel.png" alt="Moving Average Model" /></p>

<p>The add-in provides wrappers around a number of the functions in the <a href="https://cran.r-project.org/web/packages/forecast/forecast.pdf">forecast package</a>. These are as follows:</p>

<ul>
  <li>Forecast.MA - Moving average smoothing</li>
  <li>Forecast.SES - Simple exponential smoothing</li>
  <li>Forecast.Holt - Holt exponential smoothing</li>
  <li>Forecast.HW - Holt-Winters exponential smoothing.</li>
  <li>Forecast.AutoETS - Exponential smoothing state space model.</li>
  <li>Forecast.Arima - Auto-Regressive Integrated Moving Average model</li>
  <li>Forecast.AutoArima - Fit best ARIMA model to univariate time series</li>
  <li>Forecast.FC - Generic function for forecasting from time series or time series models</li>
  <li>Forecast.meanf - Mean forecast</li>
  <li>Forecast.rwf - Forecasts and prediction intervals for a random walk with drift model</li>
  <li>Forecast.splinef - Local linear forecasts and prediction intervals using cubic smoothing splines</li>
  <li>Forecast.thetaf - Forecasts and prediction intervals for a theta method forecast</li>
  <li>Forecast.Croston - Forecasts and other information for Croston’s forecasts</li>
</ul>

<h3 id="simple-exponential-smoothing">Simple Exponential Smoothing</h3>
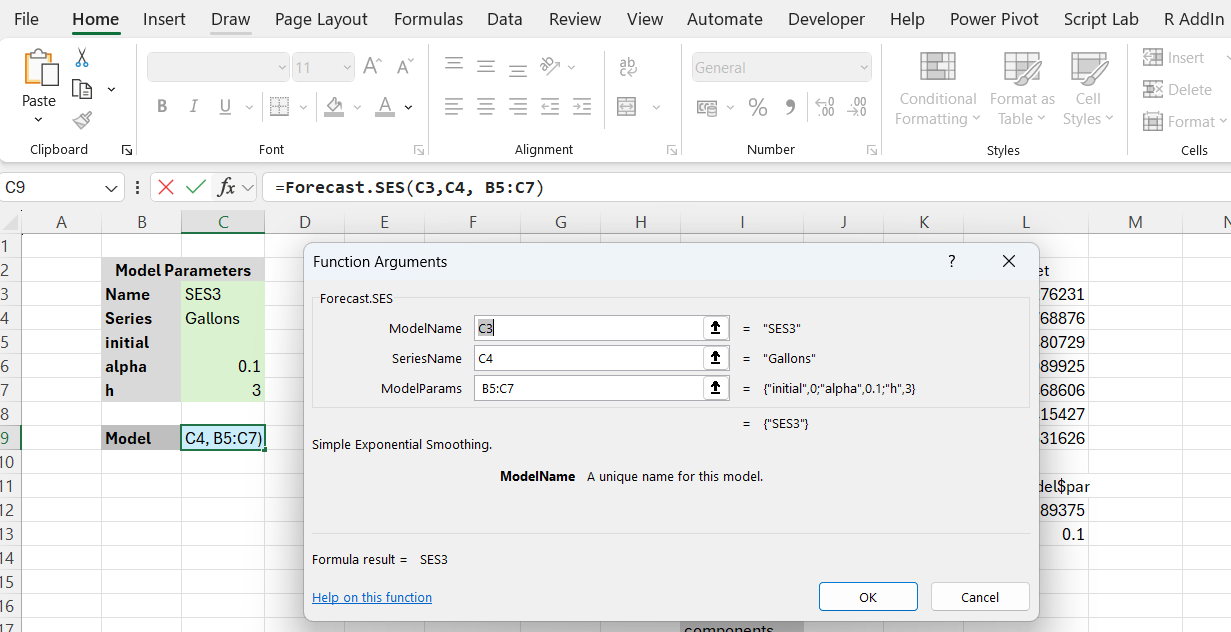
<p>In this example, we create a simple exponential smoothing model. As before we set up the model parameters following the forecast package <code class="language-plaintext highlighter-rouge">ses</code> <a href="https://cran.r-project.org/web/packages/forecast/forecast.pdf">documentation</a>. Fortunately, most of the values are defaulted so we only provide inputs for the following:</p>
<ul>
  <li><em>alpha</em> - the value of the smoothing parameter for the level. If NULL, it will be estimated.</li>
  <li><em>h</em> - the number of periods for forecasting.</li>
</ul>

<p>Then we can call the add-in function <code class="language-plaintext highlighter-rouge">Forecast.SES(...)</code>.</p>

<p><img src="https://adam-gladstone.github.io/assets/images/SimpleExpSmoothing.png" alt="Simple Exponential Smoothing" /></p>

<p>The model returns the requested forecasts with the mean, and lower and upper limits for the prediction intervals.</p>

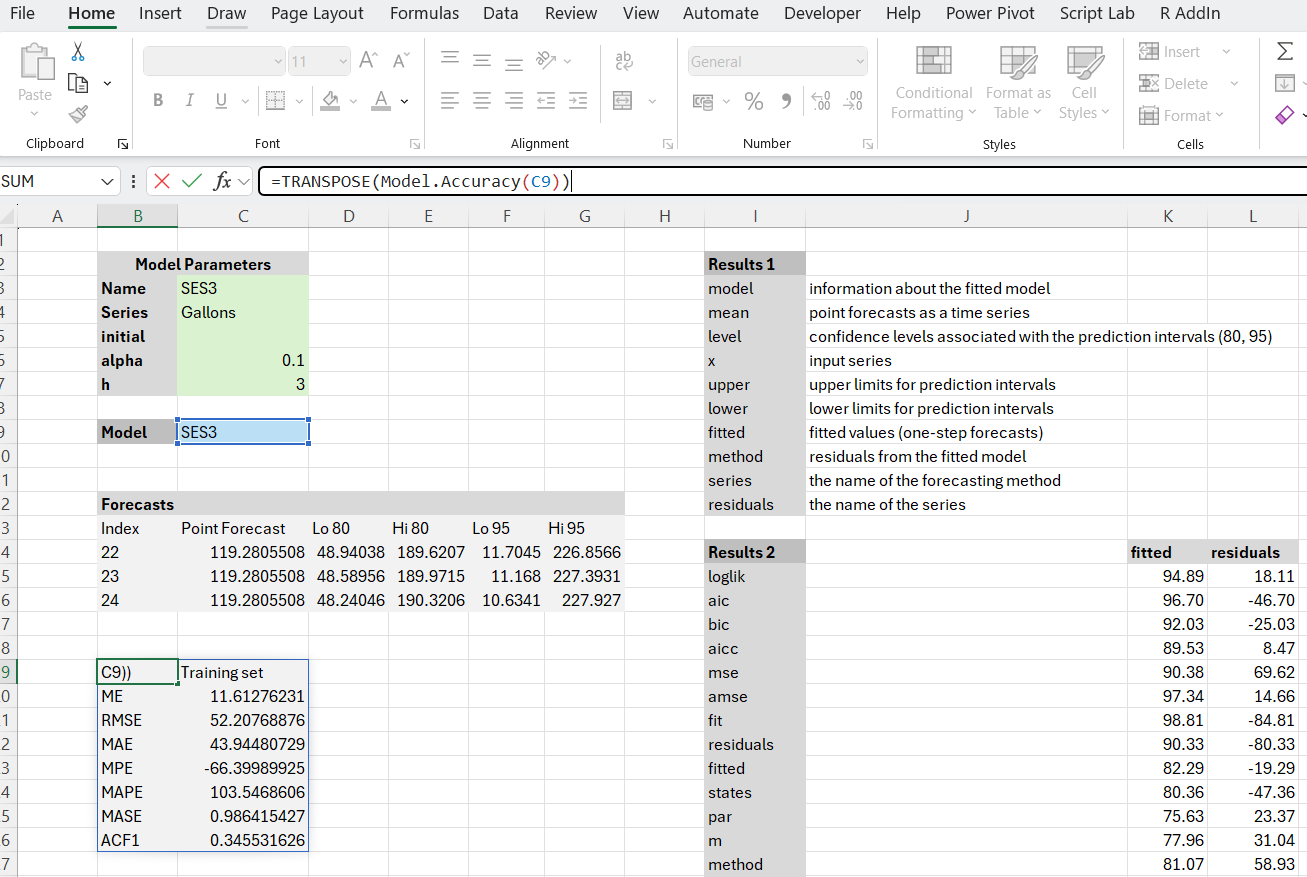
<p>In previous examples, we have extracted model results by concatenating the returned model name (‘SES3’ in this case) with labels from the model. As illustrated in <a href="https://adam-gladstone.github.io/r-project/Part-II-Using-R-in-Excel-Linear-Regression/">Part II</a>, in order to make it easier to retrieve results, the add-in provides some additional functions for querying models: <code class="language-plaintext highlighter-rouge">Model.Results</code> outputs a list of results from the model. <code class="language-plaintext highlighter-rouge">Model.Result</code> outputs the result obtained from one item of the list of model results. Optionally, the result can be formatted as a data frame. This is somewhat more convenient than having to evaluate scripts of the form <code class="language-plaintext highlighter-rouge">model name'$coeffcients</code>, etc. Finally, <code class="language-plaintext highlighter-rouge">Model.Accuracy</code> returns a number of statistics relating to measures of model accuracy.</p>

<p><img src="https://adam-gladstone.github.io/assets/images/ModelResultsAndAccuracy.png" alt="Model Results" /></p>

<h3 id="the-holt-winters-model">The Holt-Winters model</h3>
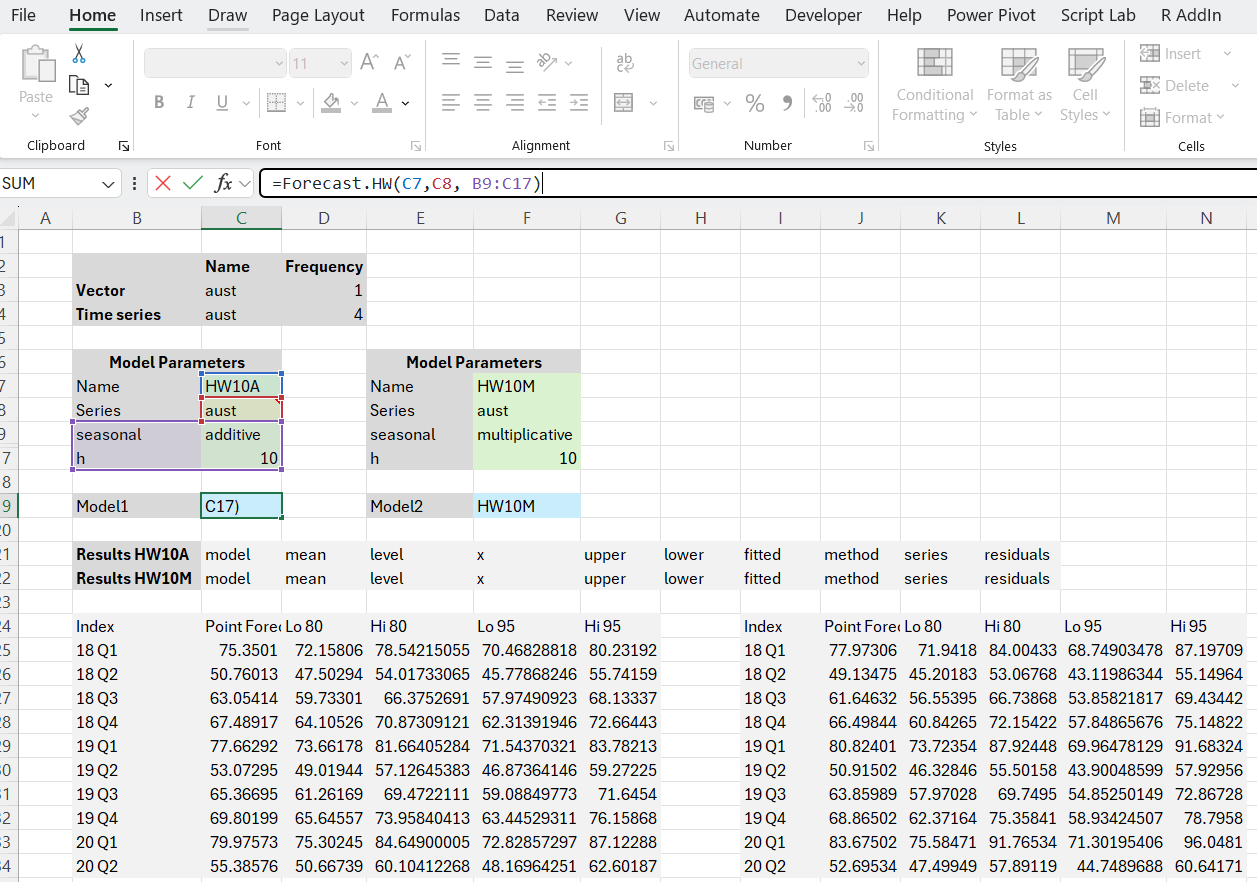
<p>The HW worksheet illustrates working with the Holt-Winters model. In this case, we set up two different models with their respective parameters, each with their own parameter block: an <strong>additive</strong> model and a <strong>multiplicative</strong> model. However, we first need to address an issue with the ‘data type’ of the dataset. Typically we can just create a numeric vector. Unfortunately, the series parameter of the Holt-Winters model requires information about the frequency with which the observations in the vector occur. Therefore we create a numeric vector first and then convert it into a <code class="language-plaintext highlighter-rouge">ts</code> time-series vector with embedded frequency information. Currently, the <strong>ExcelRAddIn</strong> does not support <strong>time series</strong> as a data type. This will be added as a future enhancement.</p>

<p><img src="https://adam-gladstone.github.io/assets/images/HoltWintersModels.png" alt="Holt-Winters Models" /></p>

<h3 id="arima">ARIMA</h3>
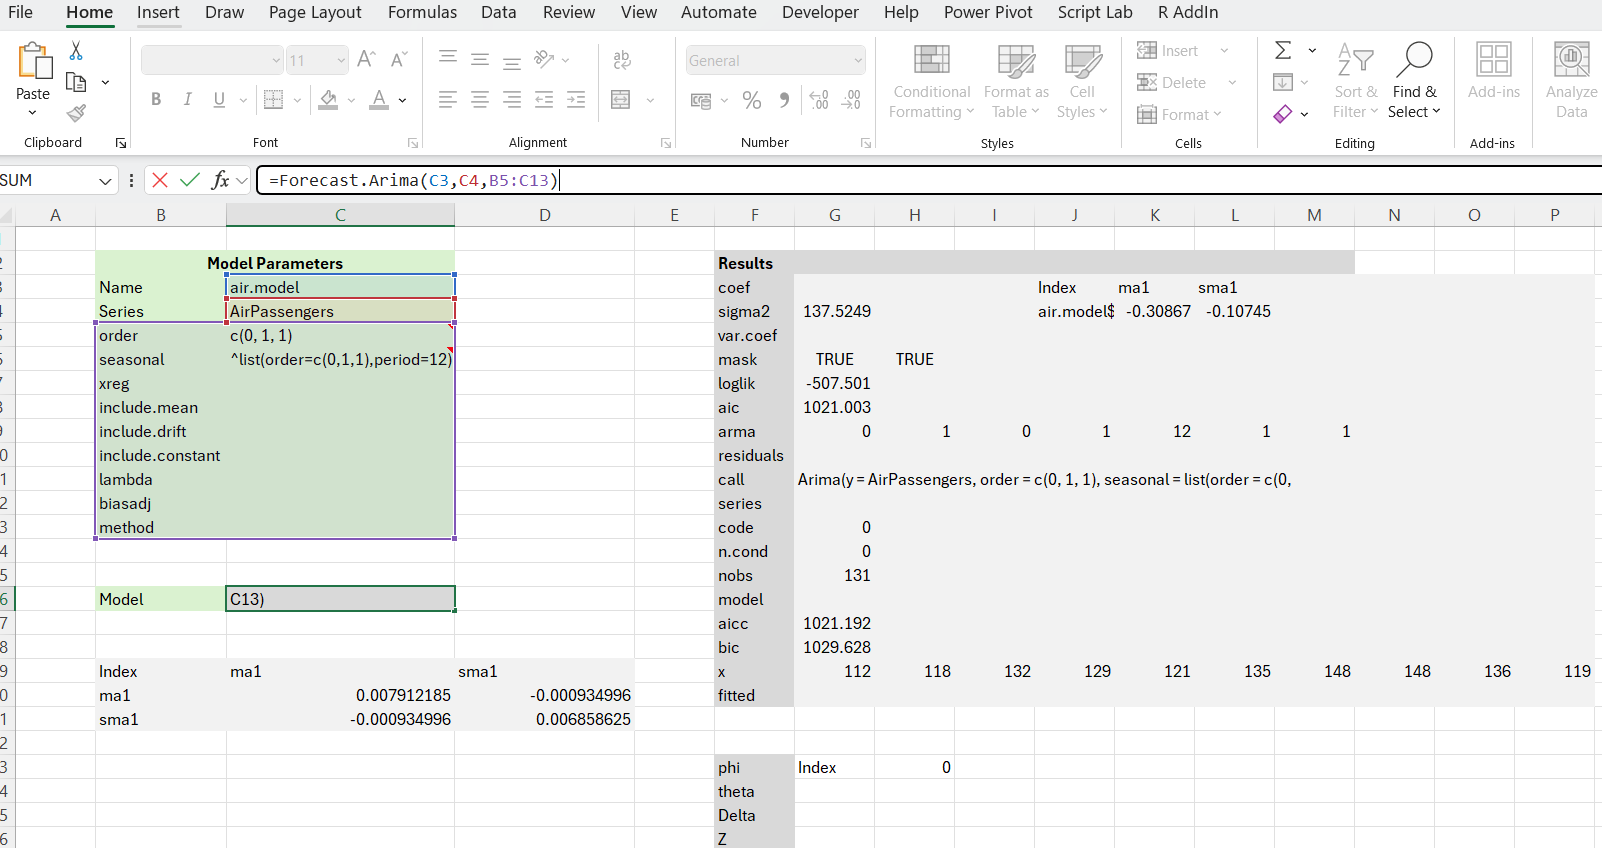
<p>The final example concerns the ARIMA model. The setup of the model is somewhat more complicated than in previous cases. Specifically, the <code class="language-plaintext highlighter-rouge">order</code> and the <code class="language-plaintext highlighter-rouge">seasonal</code> parameters.</p>

<p>From the documentation we know that the <code class="language-plaintext highlighter-rouge">order</code> parameter is a specification of the non-seasonal part of the ARIMA model: the three components (p, d, q) are the AR order, the degree of differencing, and the MA order. To handle this specification, we input the components using the vector notation: <code class="language-plaintext highlighter-rouge">c(0, 1, 1)</code>.</p>

<p>For the <code class="language-plaintext highlighter-rouge">seasonal</code> parameter, the documentation says: <em>“A specification of the seasonal part of the ARIMA model, plus the period (which defaults to frequency(y)). This should be a list with components order and period, but a specification of just a numeric vector of length 3 will be turned into a suitable list with the specification as the order.”</em></p>

<p>To achieve this we add a <strong>script</strong> parameter. This is a parameter with a leading ‘^’ character as follows:</p>

<p><code class="language-plaintext highlighter-rouge">^list(order=c(0,1,1),period=12)</code></p>

<p>With this setup we can create the ARIMA model.</p>

<p><img src="https://adam-gladstone.github.io/assets/images/ArimaModel.png" alt="ARIMA Model" /></p>

<p>The results can be extracted using a combination of <code class="language-plaintext highlighter-rouge">Model.Results</code> and <code class="language-plaintext highlighter-rouge">Model.Result</code> functions or by using a ‘raw’ R script. The model accuracy can be checked via the function <code class="language-plaintext highlighter-rouge">Model.Accuracy(...)</code>.</p>

<h3 id="wrap-up">Wrap Up</h3>
<p>In this post we have used R in Excel to perform some forecasting and time series analyses. We have seen how to set up and retrieve model data. In addition to evaluating R scripts, we have also made use of a number of wrapper functions around the <strong>Forecast</strong> package provided by the add-in to make model setup and evaluation easier.</p>

<p>In the last part of the series I will look at using R in Excel to call Python scripts.</p>]]></content><author><name>Adam Gladstone</name></author><category term="R-project" /><category term="R" /><category term="RStudio" /><category term="r-project" /><category term="Office365" /><category term="Excel" /><category term="ExcelRAddIn" /><summary type="html"><![CDATA[This post describes how to use the R Forecast package in Excel.]]></summary></entry><entry><title type="html">Part IV - Using R in Excel - Calling Python</title><link href="https://adam-gladstone.github.io/r-project/Part-IV-Using-R-in-Excel-Calling-Python/" rel="alternate" type="text/html" title="Part IV - Using R in Excel - Calling Python" /><published>2025-07-25T00:00:00+00:00</published><updated>2025-07-25T00:00:00+00:00</updated><id>https://adam-gladstone.github.io/r-project/Part%20IV%20-%20Using%20R%20in%20Excel%20-%20Calling%20Python</id><content type="html" xml:base="https://adam-gladstone.github.io/r-project/Part-IV-Using-R-in-Excel-Calling-Python/"><![CDATA[<h3 id="introduction">Introduction</h3>
<p>In the last post in this series I am going to look at calling Python from R. Even though Excel now provides a means of calling Python scripts directly, using the <code class="language-plaintext highlighter-rouge">=PY()</code> formula in a worksheet, there are still occasions when it is beneficial to call Python via R. For example, it turns out that importing <code class="language-plaintext highlighter-rouge">yfinance</code> produces a ‘module not found’ error using Excel’s function. According to the documentation, <code class="language-plaintext highlighter-rouge">yfinance</code> is not one of the open source libraries that the Excel Python secure distribution supports. To get around this issue, we can use the R package <a href="https://cran.r-project.org/web/packages/reticulate/index.html"><strong>Reticulate</strong></a>. This lets us load and run Python scripts from R. As we have seen in the previous parts of this series, the <strong>ExcelRAddIn</strong> allows us to run R scripts from an Excel worksheet. And putting these two together is quite simple.</p>

<p>The workbook for this part of the series is: <a href="https://adam-gladstone.github.io/assets/images/Part-IV-R-in-Excel-Calling-Python.xlsx">“Part IV - R in Excel - Calling Python.xlsx”</a>. As before, the ‘References’ worksheet lists links to external references. The ‘Libraries’ worksheet loads additional (non-default) packages. In this demonstration, I use the <code class="language-plaintext highlighter-rouge">reticulate</code> package and this is loaded here. The ‘Datasets’ worksheet contains the data referenced in the worksheets. In addition there are two auxilliary workksheets: Session Info and Setup. The Session Info retrieves information about the R environment and R version. The Setup worksheet performs some initialisation required for the <code class="language-plaintext highlighter-rouge">reticulate</code> package. First we point to the Python executable that we want to use. Next, we confirm the Python version is actually the one requested. Finally we set up a section that we can return to if there are errors from Reticulate and Python itself. It is worth ensuring that these cells are evaluated correctly.</p>

<h3 id="ticker-info">Ticker Info</h3>
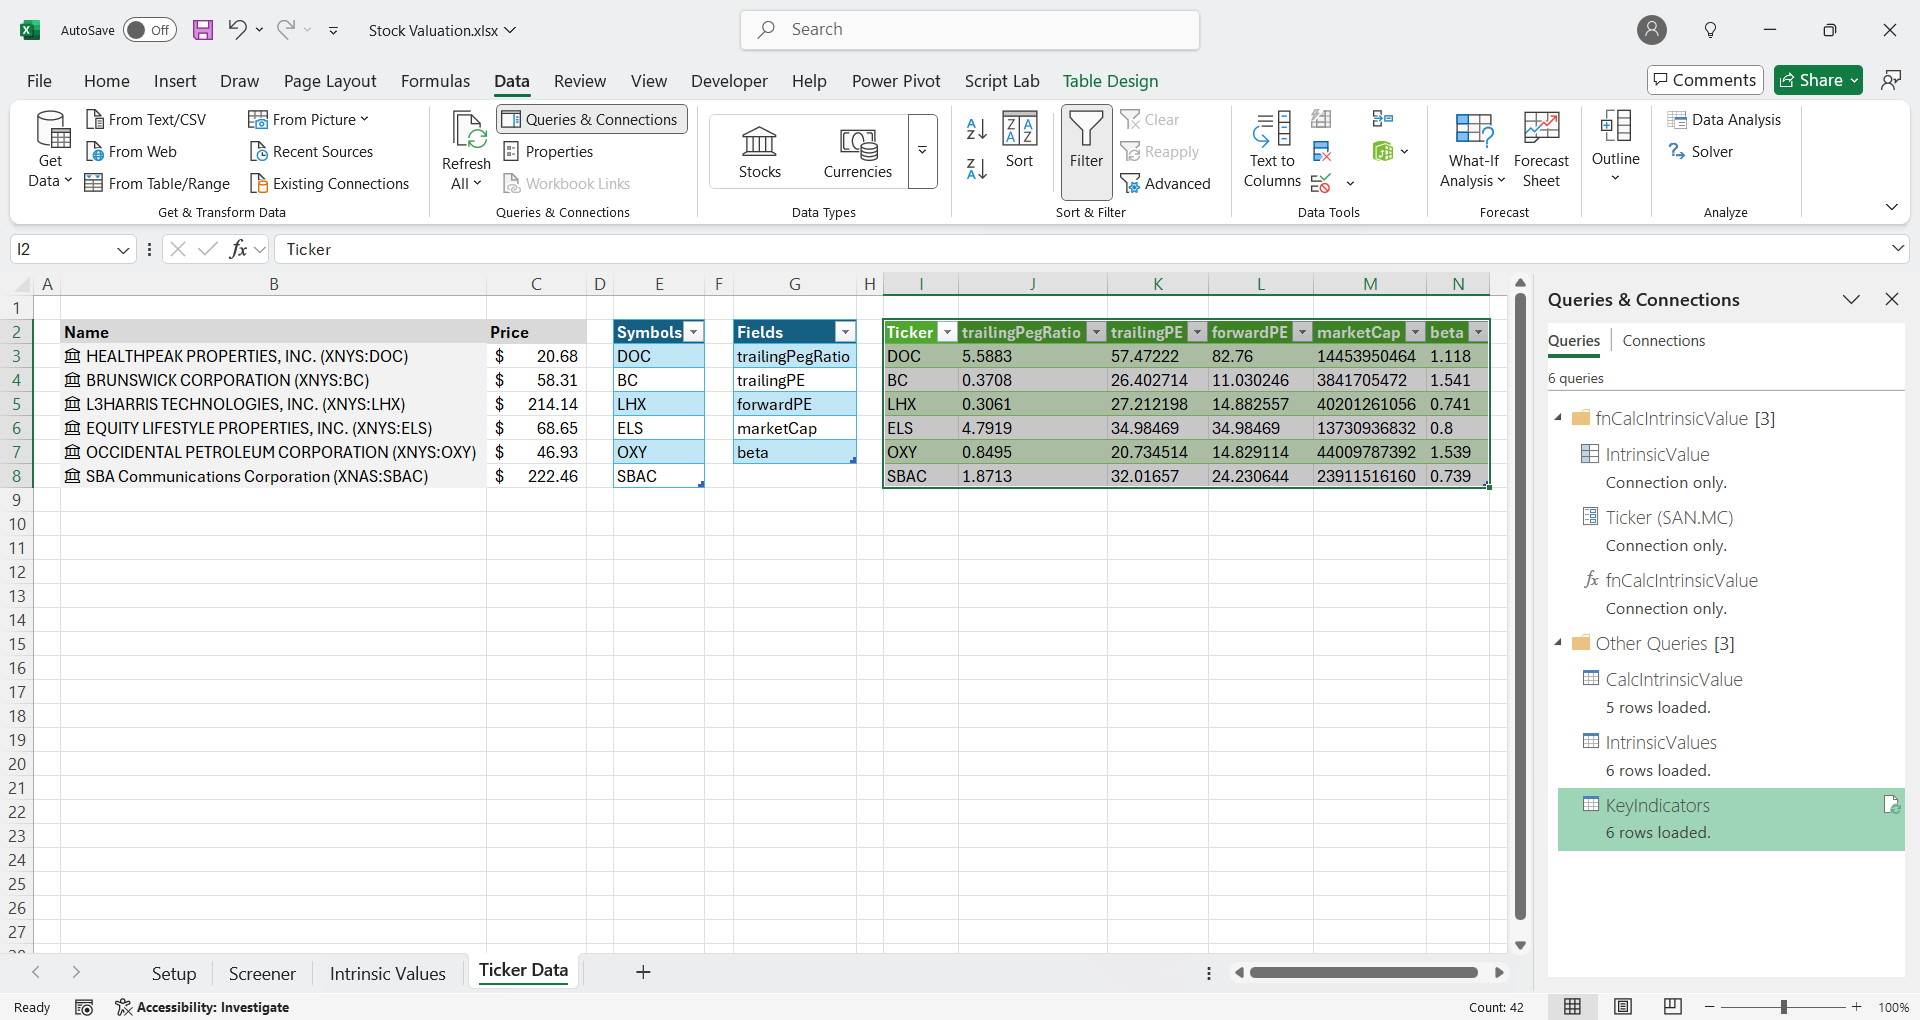
<p>This worksheet requests some basic ticker info for a number of stocks. The first step is to load the script <a href="https://adam-gladstone.github.io/assets/images/ticker_data.py">ticker_data.py</a> and ensure it compiles.</p>

<h4 id="the-python-script">The Python script</h4>
<p>The script consists of two main functions: <code class="language-plaintext highlighter-rouge">get_ticker_data</code> and <code class="language-plaintext highlighter-rouge">get_ticker_weights</code>.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>"""
ticker_data.py

Retrieve ticker data from yfinance

"""

import pandas as pd
import yfinance as yf


def get_value(info: dict, key: str):
    """
    Retrieve a value from a ticker info dictionary
    or None if the key doesn't exist
    """

    if info is not None:
        if key in info.keys():
            return info[key]

    return None


def get_items(symbol: str, fields: list) -&gt; list:
    """
    Retrieve data from the corresponding fields for the specified ticker
    """

    items: list = [symbol]

    try:
        tk: dict = yf.Ticker(symbol)
        info: dict = tk.info

        for field in fields:
            items.append(get_value(info, field))
    # pylint: disable=broad-exception-caught
    except Exception:
        # pylint: enable=broad-exception-caught
        pass

    return items


def get_ticker_data(symbols: list, fields: list) -&gt; pd.DataFrame:
    """
    Retrieve the specified fields from the input tickers
    """

    headers: list = ["Ticker"]
    for field in fields:
        headers.append(field)

    rows: list = []

    try:
        for symbol in symbols:
            rows.append(get_items(symbol, fields))

    # pylint: disable=broad-exception-caught
    except Exception:
        # pylint: enable=broad-exception-caught
        print("An error occured")

    df = pd.DataFrame(rows, columns=headers)

    return df


def get_ticker_weights(ticker_values: dict) -&gt; pd.DataFrame:
    """
    Returns:
        ticker_weights
    """

    # Set up the structure
    rows: list = []
    headers: list = ["ticker", "weight"]

    # Calculate the portfolio value
    total_portfolio_value = sum(ticker_values.values())

    for ticker, value in ticker_values.items():
        weight = value / total_portfolio_value
        rows.append([ticker, weight])

    df = pd.DataFrame(rows, columns=headers)

    return df
</code></pre></div></div>

<p><code class="language-plaintext highlighter-rouge">get_ticker_data</code> takes a list of ticker symbols and a list of fields. The fields are the items we want to retrieve from yfinance’s ticker info function. It uses the utility function <code class="language-plaintext highlighter-rouge">get_value</code> to retrieve the requested value or 0 if the key is not available. No doubt the Python script could be simplified and made more pythonic.</p>

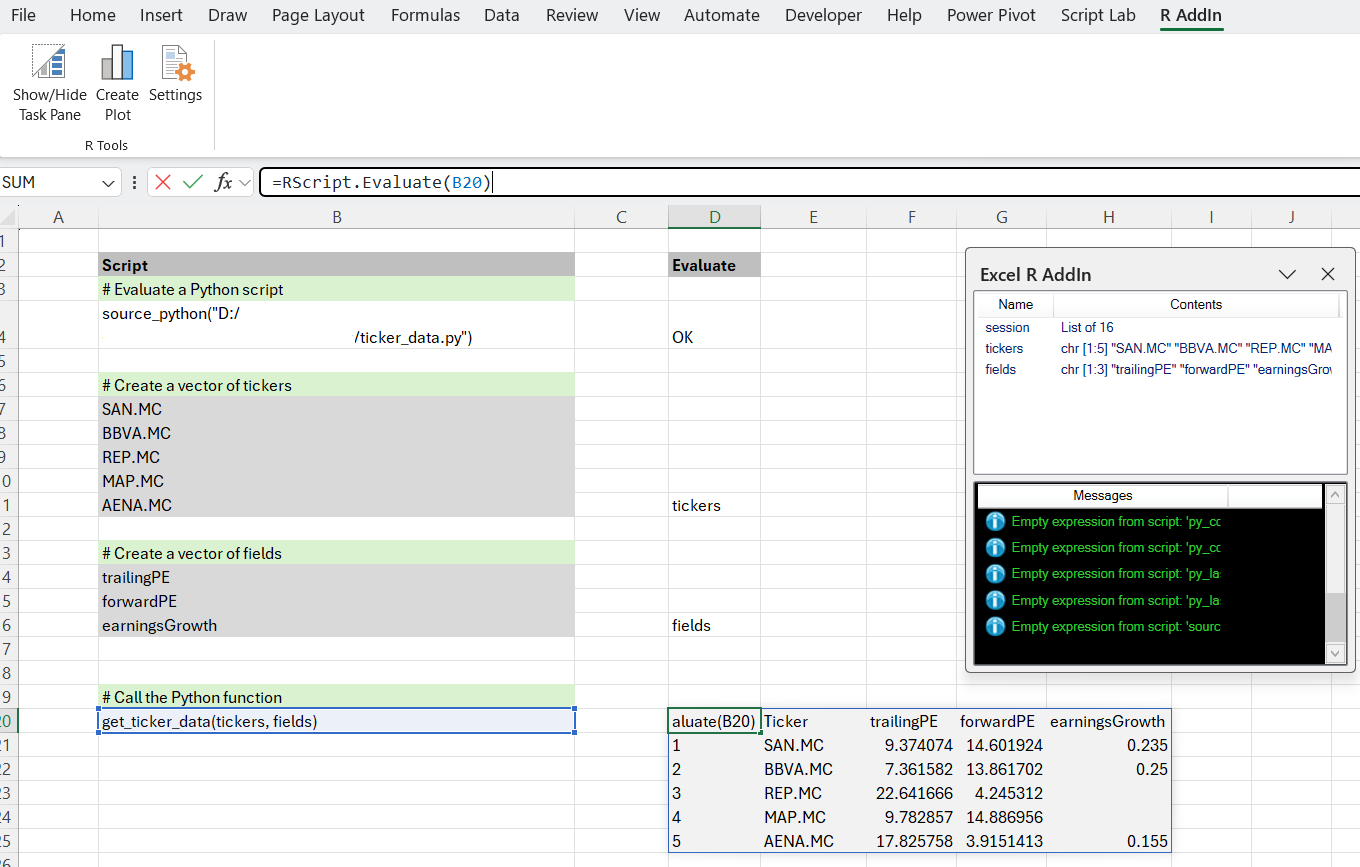
<p>In the worksheet, we create a vector of tickers and a vector of fields, and then call the Python function.</p>

<p><img src="https://adam-gladstone.github.io/assets/images/TickerInfo.png" alt="Ticker Info" /></p>

<p>The result is a data frame with the values for the fields that we requested (if available).</p>

<h4 id="portfolio-weights">Portfolio Weights</h4>
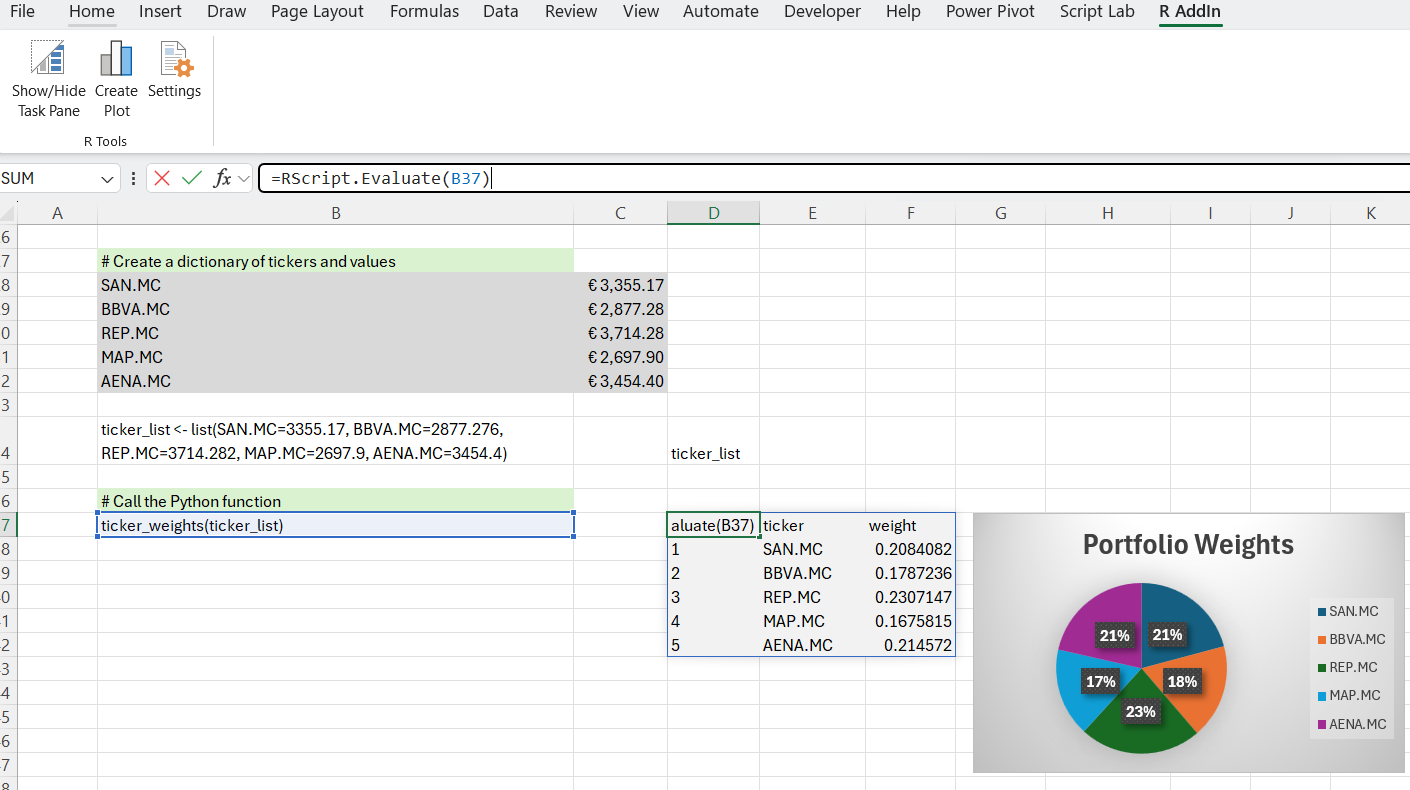
<p>The second function <code class="language-plaintext highlighter-rouge">get_ticker_weights</code>, simply computes the weights of a list of ticker symbols. The Python function requires that the input is a dictionary of symbols and their corresponding values. Therefore we create a <code class="language-plaintext highlighter-rouge">ticker_list</code> via R, since Reticulate converts R lists to Python dictionaries. The construction is somewhat mechanical and could certainly be improved just by changing the Python function inputs. With the <code class="language-plaintext highlighter-rouge">ticker_list</code> created we can call the Python function.</p>

<p><img src="https://adam-gladstone.github.io/assets/images/PortfolioWeights.png" alt="Portfolio Weights" /></p>

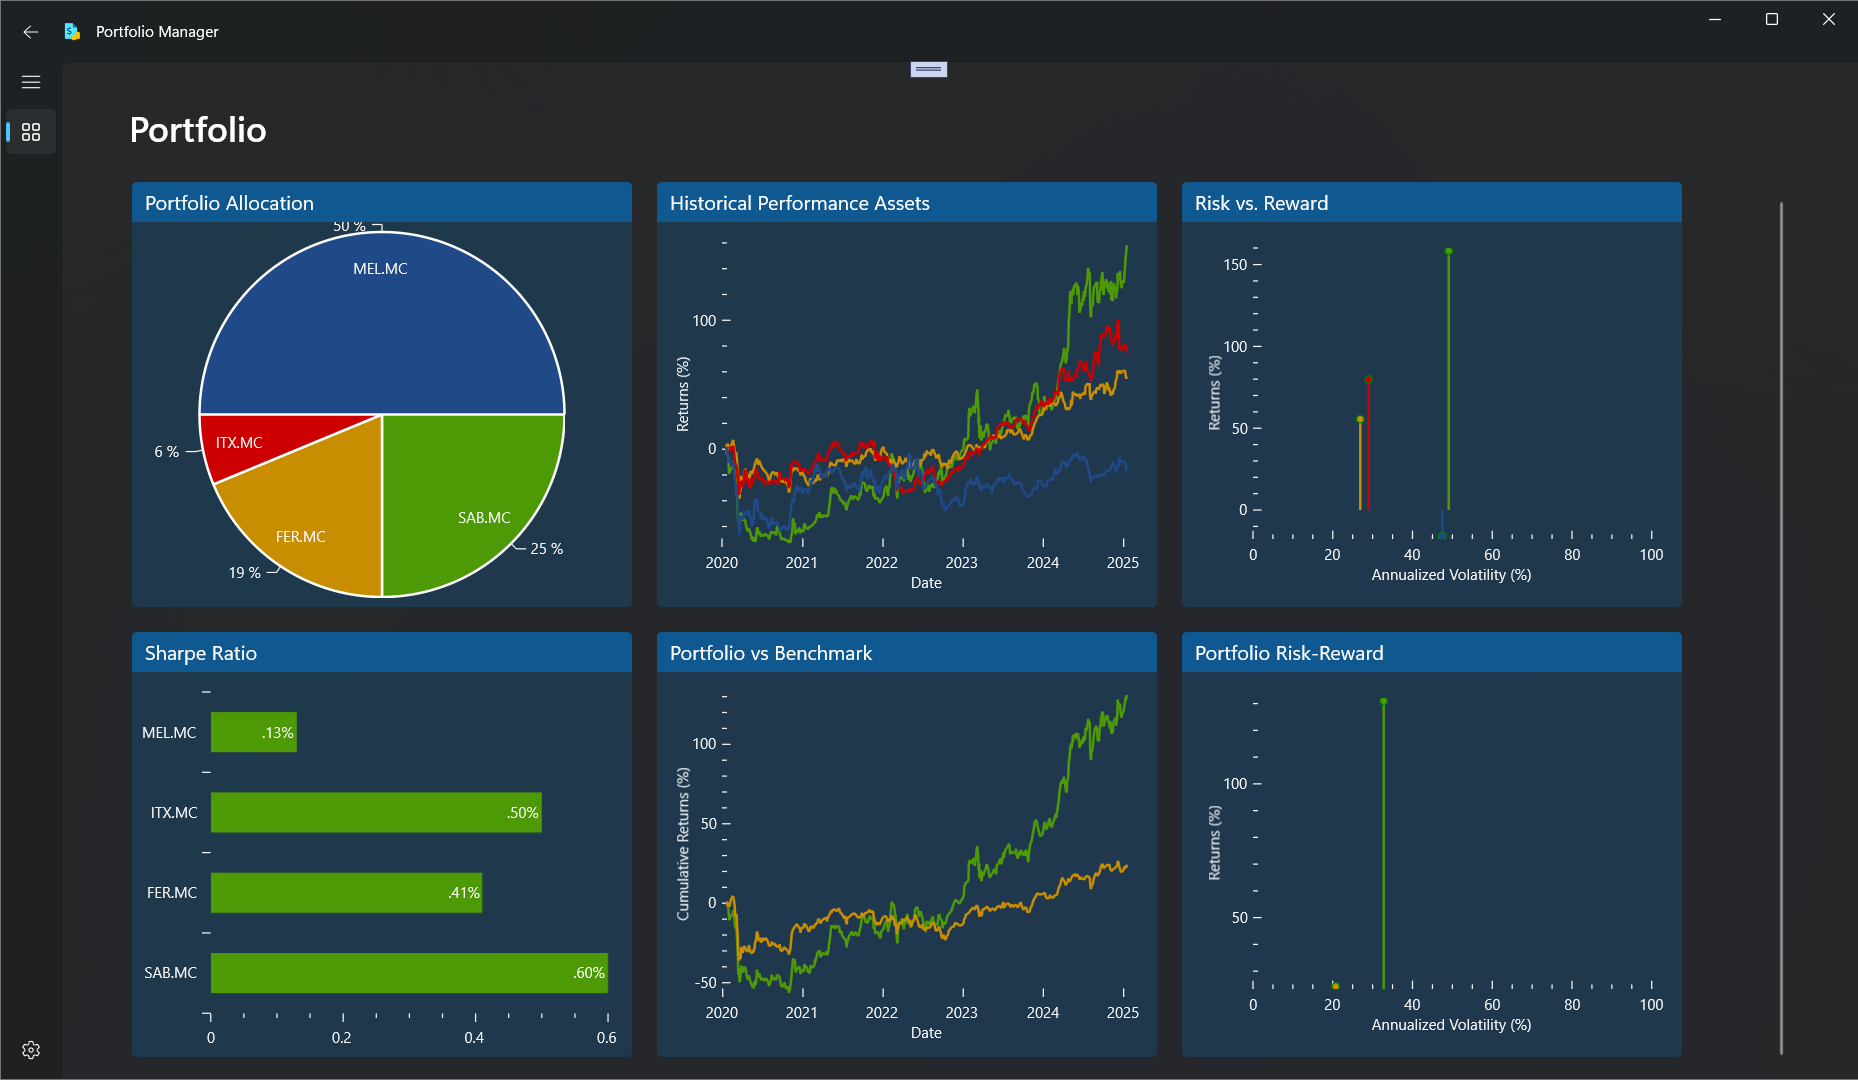
<p>This returns the portfolio weights which we can use to display graphically. From here, we could extend the Python code to compute portfolio returns for the tickers over a specified period. We could then compare the returns with a benchmark, and compute Sharpe ratios for the components.</p>

<h3 id="wrap-up">Wrap up</h3>
<p>In this post we have seen how to call Python scripts from R using the <code class="language-plaintext highlighter-rouge">reticulate</code> package. While the setup is not completely trivial, it is worth bearing in mind the advantages of this approach: from within Excel, we have access to both R and Python’s extensive ecosystems, which in turn gives us a good deal of flexibility in creating solutions. And that concludes this series of posts on using R in Excel. I hope this has been useful.</p>]]></content><author><name>Adam Gladstone</name></author><category term="R-project" /><category term="R" /><category term="RStudio" /><category term="r-project" /><category term="Office365" /><category term="Excel" /><category term="ExcelRAddIn" /><category term="Python" /><category term="python-project" /><summary type="html"><![CDATA[This post describes using R to call Python scripts inside Excel.]]></summary></entry><entry><title type="html">Building a Flask service to get yfinance data - Part I</title><link href="https://adam-gladstone.github.io/python-project/Building-a-Flask-service-to-get-yfinance-data-Part-I/" rel="alternate" type="text/html" title="Building a Flask service to get yfinance data - Part I" /><published>2025-03-19T00:00:00+00:00</published><updated>2025-03-19T00:00:00+00:00</updated><id>https://adam-gladstone.github.io/python-project/Building-a-Flask-service-to-get-yfinance-data-Part-I</id><content type="html" xml:base="https://adam-gladstone.github.io/python-project/Building-a-Flask-service-to-get-yfinance-data-Part-I/"><![CDATA[<h3 id="introduction">Introduction</h3>
<p>Recently, I’ve been doing some portfolio analysis and I came across an interesting video: <a href="https://www.youtube.com/watch?v=8jmjxXc5H8c">How to Calculate the Intrinsic Value of a Stock like Benjamin Graham</a>. Since not all the data is available in Excel, I thought it might be useful to automate the calculation using data from the (excellent) <strong>yfinance</strong> Python library. The formula itself, written in Python, is quite simple. The challenge was to obtain the individual parameters and inputs and be able to call the Python function from an Excel worksheet.</p>

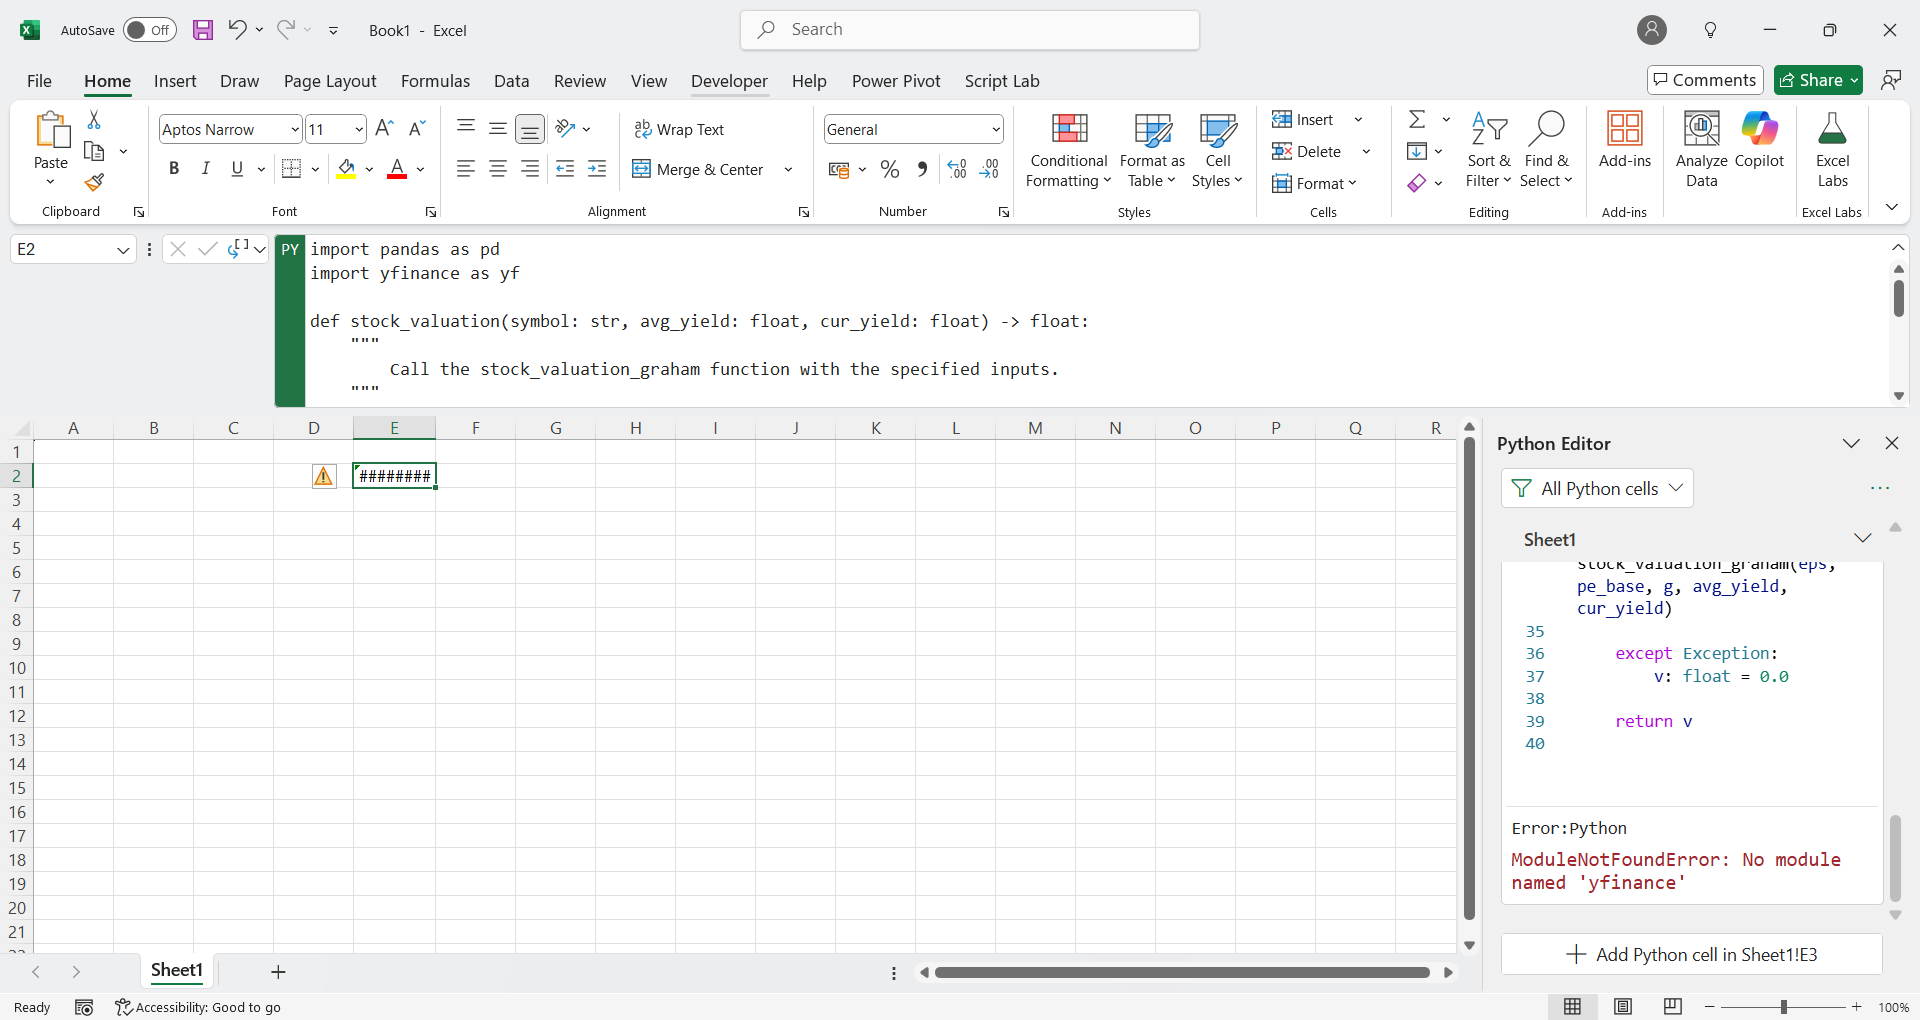
<p>It would have been nice to be able to use Excel’s Python support <a href="https://support.microsoft.com/en-us/office/get-started-with-python-in-excel-a33fbcbe-065b-41d3-82cf-23d05397f53d">PY=</a>. But it turns out that importing <strong>yfinance</strong> produces a <em>module not found</em> error.</p>

<p><img src="https://adam-gladstone.github.io/assets/images/Module-Not-Found-Error.png" alt="module not found error" />.</p>

<p>According to the documentation <strong>yfinance</strong> is not one of the open source libraries that the Excel Python secure distribution <a href="https://support.microsoft.com/en-us/office/open-source-libraries-and-python-in-excel-c817c897-41db-40a1-b9f3-d5ffe6d1bf3e">supports</a>.</p>

<p>So, in order to bridge the gap between Excel and Python I thought it might be a good idea to write a <a href="https://flask.palletsprojects.com/en/stable/">Flask API</a>. This arrangement allows us access to Python’s ecosystem, and provides a (relatively) simple means by which we can consume the data in Excel using the Power Query Web Connector.</p>

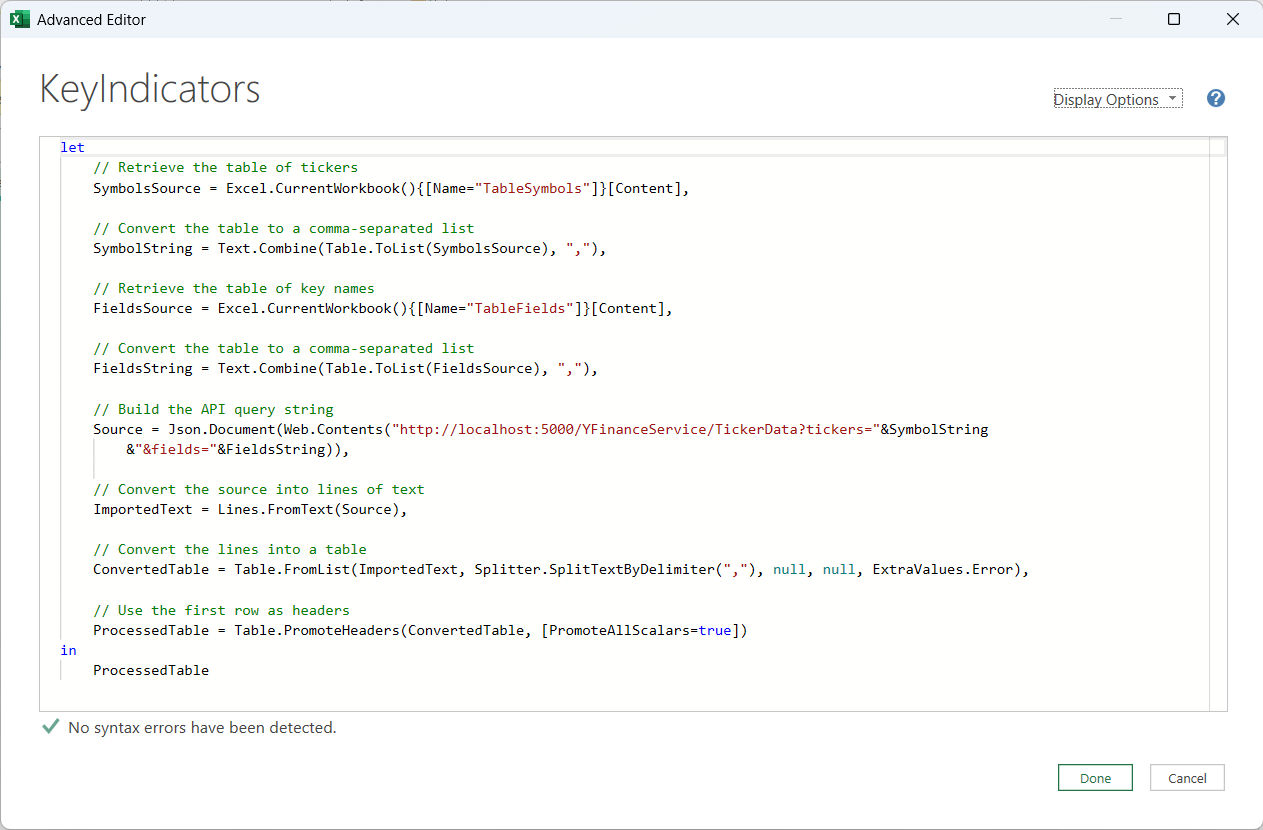
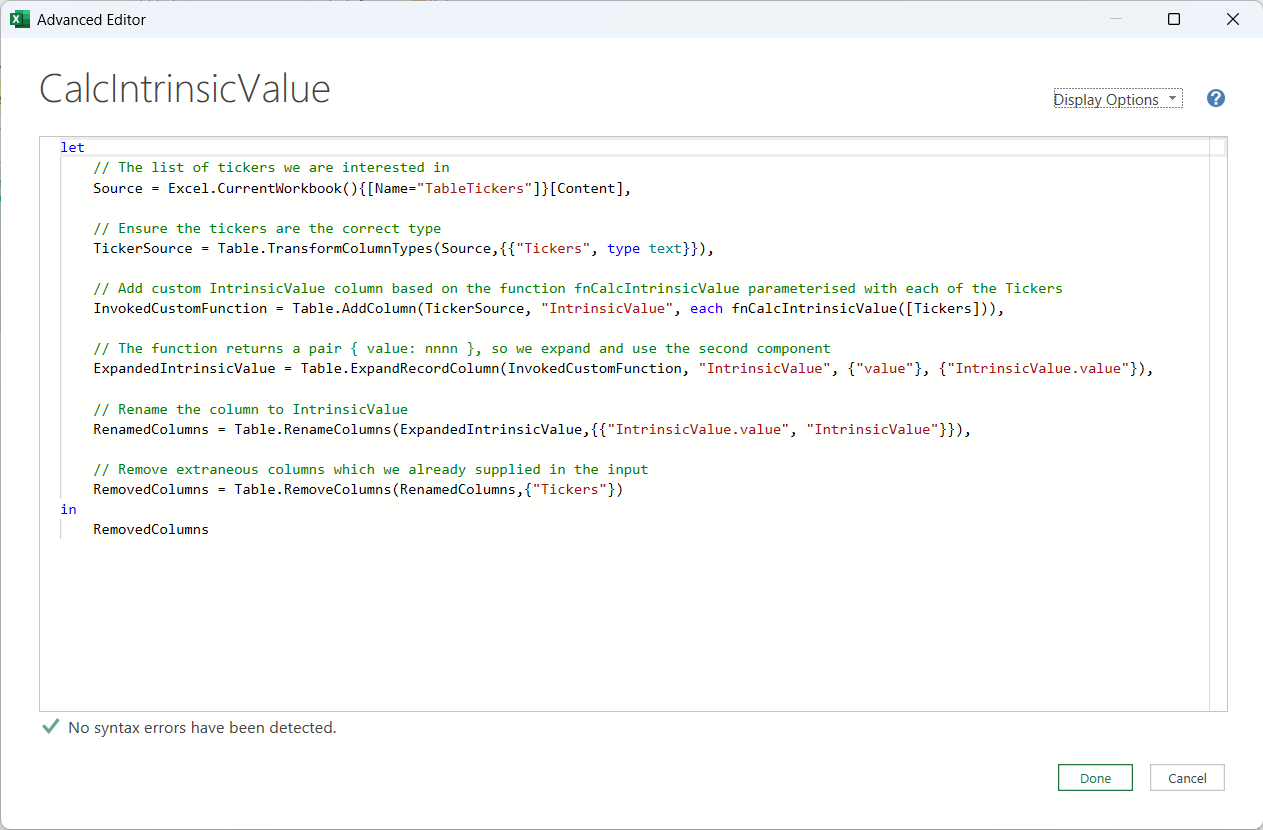
<p>This blog is divided into two parts. In <a href="https://adam-gladstone.github.io/python-project/Building-a-Flask-service-to-get-yfinance-data-Part-I/">Part I</a>, I describe the <a href="https://github.com/Adam-Gladstone/YFinanceService"><strong>YFinanceService</strong></a>. This is a basic Flask service with APIs to perform the stock valuation calculation and more generally to obtain ticker data using <strong>yfinance</strong>.</p>

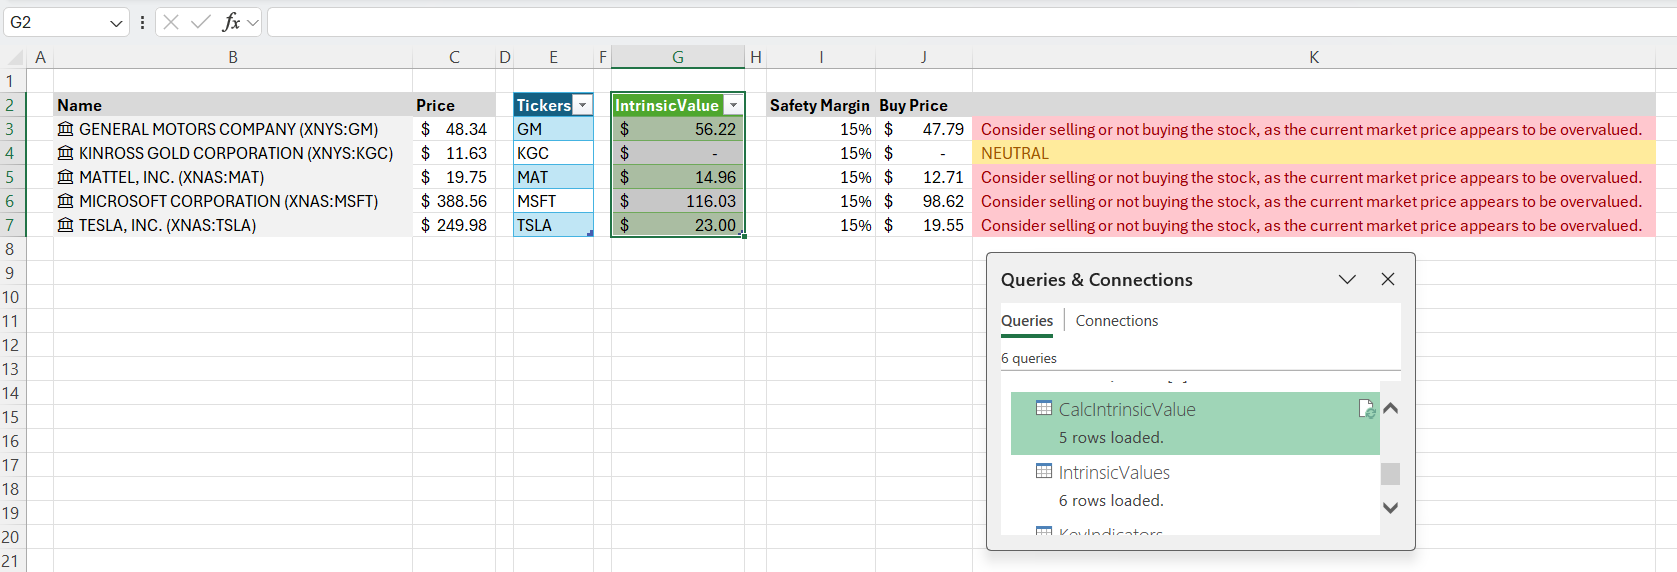
<p>In <a href="https://adam-gladstone.github.io/python-project/Consuming-yfinance-data-in-Excel-Part-II/">Part II</a>, I describe how to use the <strong>YFinanceService</strong> from Excel Power Query to automate the process of performing a stock valuation calculation and to obtain a simple table of ticker data.</p>

<p>There are several alternative approaches. One could try a custom Python add-in for Excel. If you have non-financial data perhaps use Excel’s built-in Python support. The approach adopted here is a simple and quite generic way to have access to Python and its ecosystem. It allows you to obtain data and invoke / perform calculations.</p>

<h3 id="calculate-the-intrinsic-value-of-a-stock-using-grahams-formula">Calculate the intrinsic value of a stock using Graham’s formula</h3>
<p>In general, calculating stock values is quite involved. There are a number of different methods each with their advantages and disadvantages. For example <a href="https://github.com/SimplyWallSt">Simply Wall St.</a> describes a number of more complicated approaches. The approach adopted here is to use Graham’s formula to calculate the intrinsic value of a stock with a view to determining whether it is cheap or expensive compared to its current price. The Python code is as follows:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>"""
Estimates the intrinsic value of a stock
"""


def stock_valuation_graham(eps: float, pe_base: float, g: float, avg_yield: float, cur_yield: float) -&gt; float:
    """
    Calculate the intrinsic value of a stock using Graham's formula
    Reference: https://stablebread.com/how-to-calculate-the-intrinsic-value-of-a-company-like-benjamin-graham/

        V = (eps * (pe_base + 2g) * avg_yield) / cur_yield

    where:
    V = intrinsic value per share (over the next 7-10 years)
        EPS = earnings per share (over the trailing twelve months (TTM))
        8.5 = price-to-earnings (P/E) base for a no-growth company
        g = reasonably expected annual growth rate (over the next 7-10 years)
        avg_yield = average yield of AAA Corporate Bonds
        cur_yield = current yield of AAA Corporate Bonds
    """

    V = (eps * (pe_base + 1.1 * g) * avg_yield) / cur_yield

    return V

</code></pre></div></div>

<p>The formula itself is self-explanatory. A more detailed explanation of the calculation is available <a href="https://stablebread.com/how-to-calculate-the-intrinsic-value-of-a-company-like-benjamin-graham/">here</a>. The parameters are divided into those values that we obtain per ticker and some global values. Thus, the EPS and the expected annual growth rate are obtained from the ticker info using <strong>yfinance</strong>. On the other hand, the average yield of AAA Corporate Bonds, and the current yield of AAA Corporate Bonds are setup as input parameters.</p>

<p>Finally, both the price-to-earnings (P/E) base for a no-growth company and the factor applied to the expected annual growth are hardcoded. 
The price-to-earnings (P/E) base for a no-growth company is established at <em>8.5</em>. The factor applied to the expected annual growth - <em>2g</em> seemed somewhat aggressive so we lower our expectations to <em>1.1g</em>. Later, both these values may be set up as input parameters.</p>

<h3 id="the-yfinanceservice">The YFinanceService</h3>
<p>The <strong>YFinanceService</strong> consists of four main APIs (endpoints):</p>

<ul>
  <li>TickerInfo</li>
  <li>TickerData</li>
  <li>IntrinsicValue</li>
  <li>IntrinsicValues</li>
</ul>

<p>These are declared in <a href="https://adam-gladstone.github.io/assets/images/YFinanceService.py">YFinanceService.py</a>.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code># Flask application
app = Flask(__name__)
api = Api(app)

# Register Endpoints
api.namespace('YFinanceService', description='YFinance Service API')

api.add_resource(VersionInfo, '/YFinanceService/VersionInfo')
api.add_resource(TickerInfo, '/YFinanceService/TickerInfo')
api.add_resource(TickerData, '/YFinanceService/TickerData')
api.add_resource(IntrinsicValue, '/YFinanceService/IntrinsicValue')
api.add_resource(IntrinsicValues, '/YFinanceService/IntrinsicValues')


if __name__ == '__main__':
    DEBUG = False
    HOST = environ.get('SERVER_HOST', 'localhost')
    try:
        PORT = int(environ.get('SERVER_PORT', '5000'))
    except ValueError:
        PORT = 5000
    # run our Flask app
    app.run(HOST, PORT, DEBUG)

</code></pre></div></div>

<h4 id="running-the-yfinanceservice">Running the YFinanceService</h4>
<p>The <strong>YFinanceService</strong> can be run from the command line. Locate the <code class="language-plaintext highlighter-rouge">\YFinanceService</code> subdirectory. At the command prompt, type <code class="language-plaintext highlighter-rouge">python YFinanceService.py</code>. Alternatively, the service can be run directly with the debugger from within VSCode.</p>

<p>You should see a message similar to the following:</p>

<p><img src="https://adam-gladstone.github.io/assets/images/Running-Flask-app.png" alt="Starting the YFinanceService" /></p>

<p>To test the service from a browser, type the following in the address bar:</p>

<p><a href="http://localhost:5000/YFinanceService/VersionInfo">http://localhost:5000/YFinanceService/VersionInfo</a></p>

<p>and you should see the json response packet: <code class="language-plaintext highlighter-rouge">{"VersionInfo": {"flask": "3.1.0", "yfinance": "0.2.54", "pandas": "2.2.3"}}</code></p>

<h3 id="yfinanceservice-endpoints">YFinanceService Endpoints</h3>
<p>With the service running, the API endpoints can be exercised via a browser using the examples below (assuming the service is running on port 5000).</p>

<h4 id="intrinsicvalue-api">IntrinsicValue API</h4>
<p>The Flask API <code class="language-plaintext highlighter-rouge">IntrinsicValue</code> only supports the GET method. The other REST methods (PUT, POST, etc.) are not defined. The GET API takes three parameters:</p>

<ul>
  <li>ticker - The ticker symbol</li>
  <li>avg_yield - The average yield of AAA Corporate Bonds</li>
  <li>cur_yield - The current yield of AAA Corporate Bonds</li>
</ul>

<p>The GET function is divided into two parts. The first part obtains the (required) parameters. The second part calls a wrapper function <code class="language-plaintext highlighter-rouge">stock_valuation</code>.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>class IntrinsicValue(Resource):
    """ Calculate the intrinsic value of a single stock using Graham's formula. """
    def get(self):

        parser = reqparse.RequestParser()

        parser.add_argument("ticker", type=str, required=True, help="The ticker symbol of the stock")
        parser.add_argument("avg_yield", type=float, required=True, help="Average yield of AAA Corporate Bonds")
        parser.add_argument("cur_yield", type=float, required=True, help="Current yield of AAA Corporate Bonds")

        args = parser.parse_args()

        symbol: str = args.get("ticker")
        avg_yield: float = args.get("avg_yield")
        cur_yield: float = args.get("cur_yield")

        v: float = stock_valuation(symbol, avg_yield, cur_yield)

        return {"value": v}, 200  # return info and 200 OK code

</code></pre></div></div>

<p>The <code class="language-plaintext highlighter-rouge">stock_valuation</code> function obtains the <code class="language-plaintext highlighter-rouge">ticker.info</code> dictionary from <strong>yfinance</strong>, and uses this to get the trailing EPS. The price-to-earnings (P/E) base for a no-growth company is hardcoded at <code class="language-plaintext highlighter-rouge">8.5</code>. The expected growth rate <code class="language-plaintext highlighter-rouge">g</code> is obtained from the Yahoo finance stock info library. Finally, the <code class="language-plaintext highlighter-rouge">stock_valuation_graham</code> function is called with all the required parameters and the intrinsic value is returned.</p>

<p>For example, to determine the instrinsic value of GM we can use the following query: http://localhost:5000/YFinanceService/IntrinsicValue?ticker=GM&amp;avg_yield=4.25&amp;cur_yield=3.25.</p>

<p>This returns a dictionary with a single value: {“value”: 82.07549}. Comparing this to the current price of GM (46.72), we might conclude that the stock is undervalued.</p>

<p>The <code class="language-plaintext highlighter-rouge">stock_valuation</code> function is also used by the <code class="language-plaintext highlighter-rouge">IntrinsicValues</code> API. This does the same as the <code class="language-plaintext highlighter-rouge">IntrinsicValue</code> API but for a list of tickers. For this reason, the <code class="language-plaintext highlighter-rouge">stock_valuation</code> function handles any errors and exceptions and returns <code class="language-plaintext highlighter-rouge">0.0</code> for example if a ticker is not found or the data item is not available. If this had been part of a web application, we might have returned an error code and some exception message via the API into an HTML page. However, in this arrangement, the client is Excel, and specifically the Power Query Web Connector. So to simplify the client (Excel) processing we have tried to make the API calls as resilient as possible.</p>

<p>For example, the following: http://localhost:5000/YFinanceService/IntrinsicValues?tickers=SAN.MC,BBVA.MC,IBE.MC,AENA.MC&amp;avg_yield=3.25&amp;cur_yield=1.25 queries for the intrinsic values of four Spanish stocks. The results are returned as a comma-separated table with two columns: the ticker and the intrinsic value.</p>

<h4 id="tickerdata-api">TickerData API</h4>

<p>The Flask API <code class="language-plaintext highlighter-rouge">TickerData</code> also only supports the GET method. The purpose of the API is to retrieve one or more fields from the <strong>yfinance</strong> ticker info for a given list of ticker symbols. The output is a <em>csv</em> string that can be parsed into a table with the column headers being the field names and the rows being the data corresponding to each ticker.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>class TickerData(Resource):
    """ Retrieve the specified fields from the input tickers """
    def get(self):

        parser = reqparse.RequestParser()

        parser.add_argument("tickers", type=str, action='split', required=True, help="One or more ticker symbols")
        parser.add_argument("fields", type=str, action='split', required=True, help="One or more fields")

        args = parser.parse_args()

        symbols: list = args.get("tickers")
        fields: list = args.get("fields")

        headers: list = ['Ticker']
        for field in fields:
            headers.append(field)

        rows: list = []

        try:

            for symbol in symbols:
                rows.append(get_items(symbol, fields))

        except Exception:
            print("An error occured")

        df = pd.DataFrame(rows, columns=headers)

        return df.to_csv(index=False, header=True), 200  # return info and 200 OK code

</code></pre></div></div>

<p>As previously described, the API is divided into two parts. The first part obtains the parameters, checks that the required parameters are present and sets up the table headers. The second part iterates over the input list of ticker symbols and for each symbol requests the data items from the <code class="language-plaintext highlighter-rouge">ticker.info</code> structure. Each row is appended to a list of rows. Finally, the <em>csv</em> table is returned using the <code class="language-plaintext highlighter-rouge">DataFrame.to_csv</code> method.</p>

<p>The parameters are a comma-separated list of ticker symbols and a comma-separated list of fields (key names in the <code class="language-plaintext highlighter-rouge">ticker.info</code> dictionary). This provides a relatively flexible way to obtain stock financial data.</p>

<p>For example to obtain the following indicators:</p>
<ul>
  <li>trailingPegRatio</li>
  <li>trailingPE</li>
  <li>forwardPE</li>
</ul>

<p>for the symbols: MSFT, AMZN, WAL and TSLA we can create the following query:
http://localhost:5000/YFinanceService/TickerData?tickers=MSFT,AMZN,WAL,TSLA&amp;fields=trailingPegRatio,trailingPE,forwardPE</p>

<p>As before, the error handling is resilient rather than informative. The table will be built with empty values if there is a problem obtaining the data, if the key doesn’t exist, or if the ticker symbol is unavailable and so on. This is not necessarily ideal but it simplifies the client processing.</p>

<h3 id="wrap-up">Wrap Up</h3>
<p>This blog has introduced the <strong>YFinanceService</strong>, a simple Flask service that defines some endpoints to allow us to perform a stock valuation calculation and more generally to obtain ticker data using the Python <strong>yfinance</strong> library. In <a href="https://adam-gladstone.github.io/python-project/Consuming-yfinance-data-in-Excel-Part-II/">Part II</a> of the blog, I describe how to use the <em>raw</em> APIs in Excel via the Power Query Web Connector.</p>]]></content><author><name>Adam Gladstone</name></author><category term="python-project" /><category term="Python" /><category term="yfinance" /><category term="Flask" /><category term="finance" /><category term="Excel" /><category term="Power Query" /><category term="Power Query M Language" /><category term="Web Connector" /><summary type="html"><![CDATA[Have you ever wanted access to __yfinance__ data in an Excel spreadsheet? If so, this two-part blog may be of interest. It describes an approach using a Flask API to access __yfinance__ data and the Power Query queries required to consume the data in Excel.]]></summary></entry><entry><title type="html">Consuming yfinance data in Excel - Part II</title><link href="https://adam-gladstone.github.io/python-project/Consuming-yfinance-data-in-Excel-Part-II/" rel="alternate" type="text/html" title="Consuming yfinance data in Excel - Part II" /><published>2025-03-19T00:00:00+00:00</published><updated>2025-03-19T00:00:00+00:00</updated><id>https://adam-gladstone.github.io/python-project/Consuming-yfinance-data-in-Excel-Part-II</id><content type="html" xml:base="https://adam-gladstone.github.io/python-project/Consuming-yfinance-data-in-Excel-Part-II/"><![CDATA[<h3 id="introduction">Introduction</h3>
<p>The <a href="https://adam-gladstone.github.io/python-project/Building-a-Flask-service-to-get-yfinance-data-Part-I/">first part</a> of this two-part blog described the <a href="https://github.com/Adam-Gladstone/YFinanceService">YFinanceService</a>. This is a Flask service that wraps calls to the Python <strong>yfinance</strong> library and which served up some of the data via the APIs (/IntrinsicValue, /TickerData and so on). <a href="https://adam-gladstone.github.io/python-project/Consuming-yfinance-data-in-Excel-Part-II/">Part II</a> of the blog describes how to make use of the APIs in an Excel spreadsheet, specifically using the Power Query Web Connector to retrieve the data.</p>

<h3 id="consuming-the-apis-from-excel">Consuming the APIs from Excel</h3>
<p>One of the main objectives of this project was to be able to obtain the data from <strong>yfinance</strong> via the <strong>YFinanceService</strong> and use it in Excel. For this, we use the <a href="https://adam-gladstone.github.io/assets/images/Stock%20Valuation.xlsx">Stock Valuation Spreadsheet</a>.</p>

<p><img src="https://adam-gladstone.github.io/assets/images/Excel-Calculate-Intrinsic-Value.png" alt="Calculate Intrinsic Value" /></p>

<p>The spreadsheet uses the <a href="https://learn.microsoft.com/en-us/power-query/connectors/web/web">Power Query Web Connector</a>. However, rather than using the Web Connector directly to call our <strong>YFinanceService</strong> APIs, we use Power Query to create blank queries and write the Power Query M language code to obtain the parameters from the worksheets and to process the results into a table.</p>

<p>The spreadsheet consists of the following worksheets:</p>
<ul>
  <li>Setup - defines a table (<code class="language-plaintext highlighter-rouge">Parameters</code>) with global model parameters (average yield and current yield). This table is passed into the Power Query queries when needed.</li>
  <li>Screener - this sheet obtains the current prices for a number of stocks and calculates the intrinsic value for each, displaying a recommendation alongside the computed safety margin. The margin of safety is discussed in the article <a href="https://stablebread.com/how-to-calculate-the-intrinsic-value-of-a-company-like-benjamin-graham/">How to Calculate the Intrinsic Value of a Company Like Benjamin Graham</a>.</li>
  <li>IntrinsicValues - this sheet defines a list of tickers and requests the intrinsic values for all of them. Similar to the above, it displays a recommendation alongside the computed safety margin.</li>
  <li>Ticker Data - this sheet requests a number of key indicators for a list of stock tickers and displays the results.</li>
</ul>

<p><img src="https://adam-gladstone.github.io/assets/images/Ticker-Data-Request.png" alt="Ticker Data Request" /></p>

<p>After opening the spreadsheet, select the Setup worksheet and from the Data menu select Queries and Connections. This will list the queries that are used in this sheet. The three main queries are:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">KeyIndicators</code> (in the TickerData worksheet)</li>
  <li><code class="language-plaintext highlighter-rouge">IntrinsicValues</code> (in the IntrinsicValues worksheet)</li>
  <li><code class="language-plaintext highlighter-rouge">CalcIntrinsicValue</code> which depends on the function <code class="language-plaintext highlighter-rouge">fnCalcIntrinsicValue</code> (in the Screener worksheet)</li>
</ul>

<h4 id="keyindicators-query">KeyIndicators Query</h4>
<p>The <strong>TickerData</strong> worksheet sets up two tables: <code class="language-plaintext highlighter-rouge">TableSymbols</code> and the <code class="language-plaintext highlighter-rouge">TableFields</code>. These are used as the inputs to the <code class="language-plaintext highlighter-rouge">KeyIndicators</code> query. The Power Query M code builds up the API query string from these inputs and processes the result to produce a table. The query can be refreshed using the refresh symbol on the right-hand side of the <em>Queries &amp; Connections</em> panel.</p>

<p><img src="https://adam-gladstone.github.io/assets/images/Ticker-Data-Query-M.png" alt="Building a KeyIndicators Table" /></p>

<h4 id="intrinsicvalues-query">IntrinsicValues Query</h4>
<p>The <strong>IntrinsicValues</strong> worksheet sets up a table called <code class="language-plaintext highlighter-rouge">TickerList</code>. Additionally the query obtains the values for the average yield (<code class="language-plaintext highlighter-rouge">avg_yield</code>) and the current yield (<code class="language-plaintext highlighter-rouge">cur_yield</code>) from the parameters table defined in the <strong>Setup</strong> worksheet. With these values it constructs the API query string and calls the appropriate <strong>YFinanceService</strong>. If the query succeeds, the resulting string is processed into a table with two columns: <em>Ticker</em> and <em>Intrinsic Value</em>.</p>

<h4 id="calcintrinsicvalue-query">CalcIntrinsicValue Query</h4>
<p>The <strong>CalcIntrinsicValue</strong> query depends on the <code class="language-plaintext highlighter-rouge">fnCalcIntrinsicValue</code> query/function. This in turn depends on a query (<code class="language-plaintext highlighter-rouge">IntrinsicValue</code>) which has had a parameter (<code class="language-plaintext highlighter-rouge">Ticker</code>) added to it. The parameter is added using the Manage Parameters menu on the Home menu strip. Once the parameter is added we can convert the original query to a function - <code class="language-plaintext highlighter-rouge">fnCalcIntrinsicValue</code>. The function can be invoked either by double clicking it or by entering a parameter, the ticker symbol in this case, and pressing “Invoke”. However, we will not use this method of calling the function.</p>

<p>Instead, we create a further query <code class="language-plaintext highlighter-rouge">CalcIntrinsicValue</code>. This creates a new table. The table uses the tickers defined in the <code class="language-plaintext highlighter-rouge">TableTickers</code> (input) table and adds a new custom column. The custom column invokes the intrinsic value function for each ticker value.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>	// Add custom IntrinsicValue column based on the function fnCalcIntrinsicValue parameterised with each of the Tickers
    InvokedCustomFunction = Table.AddColumn(TickerSource, "IntrinsicValue", each fnCalcIntrinsicValue([Tickers])),
</code></pre></div></div>

<p>The function <code class="language-plaintext highlighter-rouge">fnCalcIntrinsicValue</code> returns a key-value pair <code class="language-plaintext highlighter-rouge">{ value: nnnn }</code>, so we expand the result and use only the second component:</p>
<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>    ExpandedIntrinsicValue = Table.ExpandRecordColumn(InvokedCustomFunction, "IntrinsicValue", {"value"}, {"IntrinsicValue.value"}),
</code></pre></div></div>

<p>The resulting table is processed to display on the Intrinsic Value column (which is what appears in the worksheet).</p>

<p><img src="https://adam-gladstone.github.io/assets/images/Calc-Intrinsic-Value.png" alt="CalcIntrinsicValue Query" /></p>

<h3 id="a-word-about-performance">A word about performance</h3>
<p>Overall the performance of the queries is slow. Assuming the <strong>YFinanceService</strong> is already running, and the Excel spreadsheet is open. Then, pressing the refresh button on any of the queries needs to 1) construct a query string, 2) call the API via Web.Contents, and 3) process the results. The call via Web.Contents calls a Flask API which wraps Python code, and in this case calls via <strong>yfinance</strong> and <strong>yahoo_fin</strong>. Both these use web scraping and this is what determines the slow performance.</p>

<h3 id="wrap-up">Wrap Up</h3>
<p>In <a href="https://adam-gladstone.github.io/python-project/Building-a-Flask-service-to-get-yfinance-data-Part-I/">Part I</a> we described the <a href="https://github.com/Adam-Gladstone/YFinanceService">YFinanceService</a> and the API calls to the Python <strong>yfinance</strong> library. <a href="https://adam-gladstone.github.io/python-project/Consuming-yfinance-data-in-Excel-Part-II/">Part II</a> described how to make use of the APIs in an Excel spreadsheet, specifically using the Power Query Web Connector to retrieve the data.</p>

<p>Overall the arrangement that we have is:</p>
<ul>
  <li>The <strong>YFinanceService</strong> API query (“What is the intrinsic value of this stock using Graham’s formula?”) takes its parameters and inputs from an Excel table and invokes the stock valuation function via the Power Query Web Connector.</li>
  <li>The calculation is done in Python using data from the <strong>yfinance</strong> library.</li>
  <li>The result is served up over Flask endpoints (the API).</li>
  <li>The result data is massaged using the Power Query Web Connector and used in the Excel worksheet for additional calculations.</li>
</ul>

<h4 id="advantages-and-disadvantages">Advantages and Disadvantages</h4>
<p>There are advantages and disadvantages to this approach. The main advantages are:</p>
<ul>
  <li>it is simple to debug (on the Python side); somewhat less so using the Power Query M language.</li>
  <li>it is relatively simple to extend: you can add more functionality on the Python side, and/or extend the Flask API to support additional endpoints that expose more of the data from <strong>yfinance</strong>.
The disadvantages are mainly concerned with the performance.</li>
  <li>the performance is somewhat disappointing. Specifically, in this case we needed some data from another finance package <strong>yahoofinance</strong>. The underlying mechanism requires web-scraping specific yahoo finance pages (and tables and elements etc.) which results in relatively slow performance.</li>
</ul>]]></content><author><name>Adam Gladstone</name></author><category term="python-project" /><category term="Python" /><category term="yfinance" /><category term="Flask" /><category term="finance" /><category term="Excel" /><category term="Power Query" /><category term="Power Query M Language" /><category term="Web Connector" /><summary type="html"><![CDATA[Have you ever wanted access to __yfinance__ data in an Excel spreadsheet? If so, this two-part blog may be of interest. It describes an approach using a Flask API to access __yfinance__ data and the Power Query queries required to consume the data in Excel.]]></summary></entry><entry><title type="html">Calling Python from C# using Python.NET</title><link href="https://adam-gladstone.github.io/python-project/Calling-Python-from-C-using-PythonNET/" rel="alternate" type="text/html" title="Calling Python from C# using Python.NET" /><published>2025-02-21T00:00:00+00:00</published><updated>2025-02-21T00:00:00+00:00</updated><id>https://adam-gladstone.github.io/python-project/Calling%20Python%20from%20C#%20using%20PythonNET</id><content type="html" xml:base="https://adam-gladstone.github.io/python-project/Calling-Python-from-C-using-PythonNET/"><![CDATA[<h3 id="introduction">Introduction</h3>
<p>Recently, I’ve been using Python’s <strong>yfinance</strong> library to perform some simple portfolio analysis. Rather than using a Jupyter notebook to run the Python code and visualise the results, I thought it might be a nice idea to build a .NET desktop application using WinUI 3.0, XAML and C#. The application allows you to define a portfolio and manages the presentation of the results graphically. The underlying analysis is performed using Python. In order to call the Python code from C#, I use <a href="https://github.com/pythonnet/pythonnet">Python.NET</a>. The purpose of this blog post is to describe how to use <strong>Python.NET</strong> to call Python functions from a C# application. The complete <a href="https://github.com/Adam-Gladstone/PortfolioManager">PortfolioManager application</a> is available on github.</p>

<p><img src="https://adam-gladstone.github.io/assets/images/PortfolioAnalysisResults.png" alt="Portfolio Manager" /></p>

<p>The main advantage of this approach is that it allows access to Python’s extensive ecosystem from .NET. In this specific case, I wanted to build a simple portfolio management application while at the same time taking advantage of Python’s <strong>yfinance</strong> library to get the financial data I wanted and to use <strong>pandas</strong> and <strong>numpy</strong> to perform the calculations. I also wanted a slightly more real-world project using <strong>Python.NET</strong>. Information about this is somewhat limited and the examples are a little sketchy.</p>

<h4 id="versions">Versions</h4>
<p>We use the following versions:</p>
<ul>
  <li>Python 3.12</li>
  <li>yfinance 0.2.54</li>
  <li>Python.NET 3.0.5</li>
</ul>

<h4 id="the-python-api">The Python API</h4>
<p>To start off, I wrote a simple <a href="https://adam-gladstone.github.io/assets/images/portfolio_analysis.py">portfolio analysis script</a>. The script is based on a <a href="https://medium.com/python-in-plain-english/building-an-investment-portfolio-management-app-with-python-a68c2841f04b">portfolio management app</a> written in Python. However, I refactored the main functionality in order to separate the calculations and analysis from the (graphical) presentation layer. This allowed me to call the Python functions from C# to obtain the data and then process the (converted) data in the C# application.</p>

<p>The API consists of four functions.</p>

<ol>
  <li>
    <p><code class="language-plaintext highlighter-rouge">portfolio_returns(ticker_values, start_date, end_date)</code>
This function takes the user-supplied tickers (and values), start date and end date. The function computes the ticker weights and obtains the adjusted close prices (if available) for each ticker using the <strong>yfinance</strong> library. The function returns a dictionary with the ticker weights, a DataFrame containing the individual ticker returns, and the overall portfolio returns.</p>
  </li>
  <li>
    <p><code class="language-plaintext highlighter-rouge">perform_portfolio_analysis(data, ticker_weights, risk_free_rate)</code>
This function takes the portfolio returns DataFrame computed previously, the ticker weights, and a user-supplied risk free rate and uses this to calculate individual security returns, cumulative returns, volatility, and Sharpe Ratios. These are returned in a dictionary.</p>
  </li>
  <li>
    <p><code class="language-plaintext highlighter-rouge">benchmark_returns(benchmark, start_date, end_date)</code>
This function obtains the benchmark data from <strong>yfinance</strong> using the supplied parameters. It also returns a dictionary.</p>
  </li>
  <li>
    <p><code class="language-plaintext highlighter-rouge">portfolio_vs_benchmark(port_returns, benchmark_returns, risk_free_rate)</code>
This function calculates the cumulative returns, annualized volatility, and Sharpe Ratios for both the portfolio and the benchmark using the data obtained in the previous functions. It provides a side-by-side comparison to assess the portfolio’s performance relative to the benchmark.</p>
  </li>
</ol>

<p>These four functions define the API that is used by the .NET application.</p>

<h4 id="the-net-application">The .NET Application</h4>
<h5 id="prerequisites">Prerequisites</h5>
<p>For the .NET application we first need to download and build Python.NET. The code is available from https://github.com/pythonnet/pythonnet. Once downloaded, open the solution file (<code class="language-plaintext highlighter-rouge">pythonnet.sln</code>), and select the <strong>Python.Runtime</strong> as the startup project. Then right-click and build the debug version. If the build is successful the <code class="language-plaintext highlighter-rouge">Python.Runtime.dll</code> will be located in the pythonnet directory under \pythonnet\runtime.</p>

<h5 id="the-portfoliomanager-application">The PortfolioManager Application</h5>
<p>Having built the <code class="language-plaintext highlighter-rouge">Python.Runtime.dll</code>, we need to add it to the Portfolio Manager application. This is a WinUI 3.0 (C#/XAML) application which makes use of the <a href="https://github.com/CommunityToolkit/Windows">Windows Community Toolkit</a> for dependency injection and the MVVM architecture. It also uses an Sqlite database to manage a collection of one or more portfolios.</p>

<p>Aside from the test framework (<strong>PortfolioManager.Tests.MSTest</strong>), the solution consists of two main projects: the <strong>PortfolioManager</strong> and <strong>PortfolioManager.Core</strong>. The <strong>PortfolioManager</strong> project deals with the application logic, user settings, the views and the view models. The reusable logic and data models are located in the <strong>PortfolioManager.Core</strong> project. So we add the <code class="language-plaintext highlighter-rouge">Python.Runtime.dll</code> to the <strong>Dependencies</strong> here under the <strong>Assemblies</strong> node.</p>

<p><img src="https://adam-gladstone.github.io/assets/images/PythonNetRuntime.png" alt="Python.NET Runtime" /></p>

<h5 id="the-python-service">The Python service</h5>
<p>In the core library, we define a simple <code class="language-plaintext highlighter-rouge">IPythonService</code> interface that encapsulates the initialisation and the calls to the Python API.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>public interface IPythonService
{
    void Initialize(string pythonDll);

    bool RunPortfolioAnalysis(PortfolioItem portfolio);
}
</code></pre></div></div>

<p>In the <strong>PortfolioManager</strong> project, in the App.xaml.cs, we add the <code class="language-plaintext highlighter-rouge">IPythonService</code> to the list of services to be activated</p>
<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>...
services.AddSingleton&lt;IPythonService, PythonService&gt;();
</code></pre></div></div>

<p>Finally, we pass an instance of the <code class="language-plaintext highlighter-rouge">IPythonService</code> into the <code class="language-plaintext highlighter-rouge">PortfolioDetailViewModel</code>. This view model manages the graphs output as a result of running the portfolio analysis. When the view is activated after clicking on the ‘Run’ button, the <code class="language-plaintext highlighter-rouge">PythonService</code> can be initialised and the view model can run the portfolio analysis based on the selected portfolio.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>    public PortfolioDetailViewModel(IPythonService pythonService)
    {
        _pythonService = pythonService;

        var settings = App.GetService&lt;SettingsViewModel&gt;();

        var pythonDll = settings.PythonLibrary;
        _pythonService.Initialize(pythonDll);

		//...
    }
</code></pre></div></div>

<p>Initialisation of the <code class="language-plaintext highlighter-rouge">PythonService</code> consists of setting the path to the Python dll. This is configured via the application settings page. Additionally, we set up a couple of empty output streams to redirect any console output from the Python.Runtime.</p>

<h4 id="portfolio-analysis">Portfolio Analysis</h4>
<p>The main function <code class="language-plaintext highlighter-rouge">RunPortfolioAnalysis</code> is called with the currently selected <code class="language-plaintext highlighter-rouge">PortfolioItem</code>. The <code class="language-plaintext highlighter-rouge">PortfolioItem</code> contains the user supplied parameters which have been obtained from the UI.</p>

<p><img src="https://adam-gladstone.github.io/assets/images/PortfolioAnalysisParams.png" alt="Portfolio Analysis Parameters" /></p>

<p>The <code class="language-plaintext highlighter-rouge">RunPortfolioAnalysis</code> function loads the <a href="https://adam-gladstone.github.io/assets/images/portfolio_analysis.py">portfolio_analysis.py</a> script and passes it to Python.NET, which creates a Python <code class="language-plaintext highlighter-rouge">module</code> object. The <code class="language-plaintext highlighter-rouge">module</code> object is used to access the script functions and variables. We use C#’s ‘dynamic’ keyword to delay the binding. We can see the available dynamically bound functions and parameters if we expand the <code class="language-plaintext highlighter-rouge">module</code> variable in the Watch window.</p>

<p><img src="https://adam-gladstone.github.io/assets/images/PortfolioAnalysisDynamicModule.png" alt="Dynamic binding" /></p>

<p>The portfolio analysis proceeds by calling the Python functions using the user-supplied parameters and any intermediate results. Once these have been appropriately converted they are copied into the portfolio item’s data members.</p>
<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>	...
	dynamic portfolioResults = module.portfolio_returns(tickers, startDate, endDate);

	var pyTickerWeights = new PyDict(portfolioResults["weights"]);

	portfolio.TickerWeights = Interop.Converters.ConvertTickerWeights(pyTickerWeights);
	...
</code></pre></div></div>
<p>In this snippet, the Python object <code class="language-plaintext highlighter-rouge">pyTickerWeights</code> is extracted from the dictionary returned from calling <code class="language-plaintext highlighter-rouge">module.portfolio_returns</code>. The Python ‘dict’ is converted into a C# <code class="language-plaintext highlighter-rouge">List&lt;TickerWeight&gt;</code>. The <code class="language-plaintext highlighter-rouge">ConvertTickerWeights</code> function just iterates over each ticker and obtains the corresponding weight. This is then assigned to the <code class="language-plaintext highlighter-rouge">TickerWeights</code> member of the portfolio item. The <code class="language-plaintext highlighter-rouge">TickerWeights</code> list is then used in a Pie Chart that displays the percentage allocation of tickers in the portfolio.</p>

<p>Once the analysis is complete, the <code class="language-plaintext highlighter-rouge">PortfolioDetailViewModel</code> initialises the <code class="language-plaintext highlighter-rouge">PlotModel</code> with the data from the portfolio item, which then updates the graph view as it is bound to the specific <code class="language-plaintext highlighter-rouge">PlotModel</code>.</p>

<p>It is worth highlighting that the performance is quite slow. There seem to be two main aspects to this:</p>
<ol>
  <li>The initialisation of the Python engine seems to take some time, and perhaps this could be done once at startup.</li>
  <li>The <code class="language-plaintext highlighter-rouge">PortfolioDetailViewModel</code> renders six graphs with different datasets serially. It seems to me that this might be better refactored to use C# asynchronous processing.</li>
</ol>

<p>I am currently investigating both these issues.</p>

<h4 id="the-interop-layer">The interop layer</h4>
<p>This layer provides facilities to convert between C# and Python types. Basic types (strings, ints, doubles etc.) are converted transparently. From C#, we use the <code class="language-plaintext highlighter-rouge">.ToPython()</code> extension method to convert to a Python object. And from Python, we use the <code class="language-plaintext highlighter-rouge">.AsManagedObject(typeof(T))</code> function to return a C# object which we can then cast. Converting from a pandas DataFrame or series can be somewhat more involved.</p>

<h3 id="wrap-up">Wrap-up</h3>
<p>This blog post has described how to call Python functions from a C# desktop application using Python.NET. This arrangement (WinUI 3.0 C# front-end, Python.NET and Python) has the advantage of flexibility. The approach is quite generalisable. I could just as easily have created a TensorFlow model and called it from a C# application, if that had been my interest. On the other hand, the main disadvantage is the slow performance. This is an area that I am still currently investigating.</p>]]></content><author><name>Adam Gladstone</name></author><category term="python-project" /><category term="Python" /><category term="yfinance" /><category term="WinUI 3.0" /><category term="C#" /><summary type="html"><![CDATA[Recently, I've been using Python's __yfinance__ library to perform some simple portfolio analysis. Rather than using a Jupyter notebook to run the Python code and visualise the results, I thought it might be a nice idea to build a .NET desktop application using WinUI 3.0, XAML and C#. The application allows you to define a portfolio and manages the presentation of the results graphically. The underlying analysis is performed using Python. In order to call the Python code from C#, I use [Python.NET](https://github.com/pythonnet/pythonnet). The purpose of this blog post is to describe how to use Python.NET to call Python functions from a C# application. The complete application is available on github: (https://github.com/Adam-Gladstone/PortfolioManager).]]></summary></entry><entry><title type="html">Calling C++ functions from R using Rcpp</title><link href="https://adam-gladstone.github.io/r-project/Calling-C++-functions-from-R-using-Rcpp/" rel="alternate" type="text/html" title="Calling C++ functions from R using Rcpp" /><published>2024-12-24T00:00:00+00:00</published><updated>2024-12-24T00:00:00+00:00</updated><id>https://adam-gladstone.github.io/r-project/Calling%20C++%20functions%20from%20R%20using%20Rcpp</id><content type="html" xml:base="https://adam-gladstone.github.io/r-project/Calling-C++-functions-from-R-using-Rcpp/"><![CDATA[<h3 id="introduction">Introduction</h3>
<p>If you are an R/RStudio user and you are learning C/C++ then this blog post may be interesting. Suppose that you’ve written a function in C/C++ (or even a whole program). You know how to run your code from the command line, passing in arguments and so on. However, this is not necessarily very convenient. Wouldn’t it be nice to have your C/C++ functionality available in R? Well you can. In a few easy steps (using Rcpp) you can make your C/C++ functions available in R/RStudio.</p>

<p>This blog post describes the steps required. I won’t dwell too much on the technicalities. The details are covered elsewhere: <a href="http://adv-r.had.co.nz/Rcpp.html">Rcpp</a>. What I’m interested in here is <strong>setting up an Rcpp package that can call C++ functions from R/RStudio</strong>.</p>

<p>This project is no more than a starting point. Later on, I may add bells-and-whistles. The complete <strong>FinancialFunctions</strong> project is available on GitHub <a href="https://github.com/Adam-Gladstone/FinancialFunctions">FinancialFunctions</a>.</p>

<p>We’ll start off by creating an Rcpp package. This will give us a framework that we can use to <em>drop in</em> the C++ code. Then, we will tweak the Rcpp code to call our C++ functions and build the package. For reference we are using the following versions:</p>
<ul>
  <li>R version 4.4.1</li>
  <li>RStudio version 2024.04.2 (Build 764)</li>
  <li>RTools version 4.4</li>
</ul>

<h3 id="1-creating-an-rcpp-package">1. Creating an Rcpp package</h3>
<p>Follow these steps to create an Rcpp package.</p>

<p>First, make sure Rcpp is installed. If not, just run the following command in RStudio: <code class="language-plaintext highlighter-rouge">install.packages("Rcpp")</code></p>

<ul>
  <li>Select File &gt; New Project …</li>
  <li>In the New Project Wizard dialog, select New Directory</li>
  <li>In the Project Type page, scroll down the list of project types and select ‘R Package using Rcpp’.</li>
</ul>

<p><img src="https://adam-gladstone.github.io/assets/images/Rcpp-project-type.png" alt="R Package using Rcpp" /></p>

<ul>
  <li>In the ‘Create R Package using Rcpp’ page, fill in the Directory name. In this case it is <strong>FinancialFunctions</strong>.</li>
  <li>Press the Create Project button. A new RStudio session is started, and the project opens with a helpful <strong>Read-and-delete-me</strong> file.</li>
</ul>

<p>Navigate to the \src directory and open the file <strong>rcpp_hello_world.cpp</strong>. Here there is a test C++ function called <code class="language-plaintext highlighter-rouge">rcpp_hello_world()</code> which we can call from R after we build the package.</p>

<p><img src="https://adam-gladstone.github.io/assets/images/Rcpp-hello-world.png" alt="Rcpp Hello World" /></p>

<ul>
  <li>Select the menu: Build &gt; Build binary package</li>
</ul>

<p>If everything goes okay, we should see a message similar to this:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>...
packaged installation of 'FinancialFunctions' as FinancialFunctions_1.0.zip
─  DONE (FinancialFunctions)
[1] "D:/TEMP/FinancialFunctions_1.0.zip"

Binary package written to D:/TEMP
</code></pre></div></div>

<p>Now we have built a fully functional Rcpp package. Open the zip-file and copy the contents into your R library directory (e.g. D:\R\R-4.4.1\library). Then, in RStudio, run the following script:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>&gt; library(FinancialFunctions)		# Load the package
&gt; results &lt;- rcpp_hello_world()		# Call the C++ function
&gt; results							# Print the results
[[1]]
[1] "foo" "bar"

[[2]]
[1] 0 1
</code></pre></div></div>

<h3 id="2-adding-c-code">2. Adding C++ code</h3>
<p>Now that we have a working skeleton, we can add our own C++ functions to the package.</p>

<p>Copy the two files <a href="https://adam-gladstone.github.io/assets/images/FinancialFunctions.h"><strong>FinancialFunctions.h</strong></a> and <a href="https://adam-gladstone.github.io/assets/images/FinancialFunctions.cpp"><strong>FinancialFunctions.cpp</strong></a> into the <strong>\src</strong> directory.</p>

<p>There are two functions declared in the header file: <code class="language-plaintext highlighter-rouge">price</code> and <code class="language-plaintext highlighter-rouge">ytm</code> (yield-to-maturity).</p>

<p>The price function computes the present value of a stream of periodic cashflows using a single discount rate. The yield-to-maturity function computes the single rate of return implied by the periodic cashflows and the price (present value).</p>

<p>The price function takes a vector of times and a vector of cashflows (for a bond these are the coupons and the final principal repayment). In addition, the function takes a single rate, which is used to discount all the cashflows.</p>

<p>The yield-to-maturity function also takes a vector of times and a vector of cashflows (as above) and a (bond) price. From this, it iteratively determines the single rate at which the periodic stream of cashflows should be discounted to obtain the supplied price.</p>

<h3 id="3-connecting-r-with-c-using-rcpp">3. Connecting R with C++ using Rcpp</h3>
<p>Delete the file <strong>rcpp_hello_world.cpp</strong> as we no longer need the test function. Then copy the file <a href="https://adam-gladstone.github.io/assets/images/rcpp_functions.cpp"><strong>rcpp_functions.cpp</strong></a> into the <strong>\src</strong> directory. This file contains the functions that we want to <strong>export</strong> from C++ to R using Rcpp.</p>

<p>At the top of the file, we include the main Rcpp header file. This is followed by the STL vector include and finally, we include the declarations of our functions in <strong>FinancialFunctions.h</strong>.</p>

<p>The code in <strong>rcpp_functions.cpp</strong> declares an Rcpp function called <code class="language-plaintext highlighter-rouge">bond_price</code>. Most importantly, it is preceded by the line <code class="language-plaintext highlighter-rouge">// [[Rcpp::export]]</code>. This attribute indicates that the function should be <strong>exported</strong>, that is, made visible to R. As simple as that. Rcpp takes care of all the details. All we are concerned about is what parameters we are passed and how to call our function and get the results.</p>

<p>The <code class="language-plaintext highlighter-rouge">bond_price</code> function takes as its parameters two numeric vectors (the times and the cashflows), and a rate (a double). These are passed in from R. The function returns a double value, the calculated price. The Rcpp function looks like this.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>// [[Rcpp::export]]
double bond_price(Rcpp::NumericVector times, Rcpp::NumericVector cashflows, double rate)
{
  std::vector&lt;double&gt; _times = Rcpp::as&lt;std::vector&lt;double&gt;&gt;(times);
  std::vector&lt;double&gt; _cashflows = Rcpp::as&lt;std::vector&lt;double&gt;&gt;(cashflows);
  
  double price = FinancialFunctions::Bonds::price(_times, _cashflows, rate);
 
  return price;
}
</code></pre></div></div>

<p>Inside the function, the Rcpp types <code class="language-plaintext highlighter-rouge">NumericVector</code> are converted to <code class="language-plaintext highlighter-rouge">std::vector&lt;double&gt;</code>, which is what our function expects.</p>

<p>Finally we call our function and return the result.</p>

<p>The Rcpp code for <code class="language-plaintext highlighter-rouge">bond_ytm</code> is very similar.</p>

<p>Everything is now ready to be built.</p>

<ul>
  <li>Select the menu: Build &gt; Build binary package.</li>
</ul>

<p>Keep our fingers crossed that we have not made any mistakes. If everything goes okay, we should see a message similar to this:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Binary package written to D:/Development/Projects/R
</code></pre></div></div>

<p>Copy the contents of the zip file into your R library directory as previously, overwriting the initial version of the package.</p>

<p>In order to check that everything works as expected, run the following script.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>library(FinancialFunctions)
# Example: a 3 year bond with a face value of $100 makes annual coupon 
# payments of 10%. The current interest rate (with annual compounding) is 9%.
times &lt;- c(1, 2, 3)
cashflows &lt;- c(10, 10, 110)
rate &lt;- 0.09

# Calculate price and yield to maturity
price &lt;- FinancialFunctions::bond_price(times, cashflows, rate)
ytm &lt;- FinancialFunctions::bond_ytm(times, cashflows, price)

# Display the results
price
ytm
</code></pre></div></div>

<p>There should be no errors. We can check the results against the manual calculations in a spreadsheet if required.</p>

<h3 id="wrap-up">Wrap up.</h3>
<p>That’s all there is to it. We now have a working Rcpp package that calls C/C++ functions from R.</p>

<p>But that really is only the beginning. There’s a lot more that can be done. For starters, we could improve the project design by isolating our code in a static library. We could also add some test cases, perhaps using a package like ‘testthat’. Finally, we could add a couple more functions: perhaps bond duration and convexity calculations. I might look at how to do all this in a future article. The complete project is available on GitHub, <a href="https://github.com/Adam-Gladstone/FinancialFunctions">FinancialFunctions</a>.</p>]]></content><author><name>Adam Gladstone</name></author><category term="R-project" /><category term="R" /><category term="r-project" /><category term="rcpp" /><category term="cpp" /><category term="cplusplus" /><summary type="html"><![CDATA[If you are an R/RStudio user and you are learning C/C++ then this blog post may be interesting. Suppose that you've written a function in C/C++ (or even a whole program). You know how to run your code from the command line, passing in arguments and so on. However, this is not necessarily very convenient. Wouldn't it be nice to have your C/C++ functionality available in R? Well you can. In a few easy steps (using Rcpp) you can make your C/C++ functions available in R/RStudio.]]></summary></entry></feed>